


The OpenAI Realtime Voice API is a speech-to-speech interface that lets applications hold natural, low-latency voice conversations with an AI model, handling transcription, reasoning, and audio generation in a single persistent session. It supports WebRTC and WebSocket transports, semantic turn detection, tool calling, and multilingual speech. Developers building production voice agents can pair it with infrastructure like VideoSDK's AI agent runtime to manage sessions, telephony, and deployment at scale.
Real-time voice AI has crossed the threshold from demo to product. In 2026, the expectation is no longer a clunky wake-word assistant with two-second pauses; users want conversations that feel human, with interruptions, quick replies, and natural back-and-forth. The OpenAI Realtime Voice API is one of the main reasons that expectation is now achievable.
Before this API existed, developers stitched together three separate systems: a speech-to-text engine, a language model, and a text-to-speech service. Each hop added latency, and each boundary broke the conversational flow. The Realtime API collapses that pipeline into a single speech-to-speech model, cutting end-to-end response times dramatically.
In this guide, you'll learn what the OpenAI Realtime Voice API is, how a realtime session works under the hood, how to choose between WebRTC and WebSocket transports, and the security and operational practices that separate a prototype from a production deployment.
What is the OpenAI Realtime Voice API?
The OpenAI Realtime Voice API is defined as a hosted API for bidirectional, speech-to-speech conversations between a user and an AI model over a persistent connection. Instead of sending text prompts and receiving text back, your application streams raw audio in and receives synthesized speech out, with the model managing listening, understanding, and responding as one continuous process.
The OpenAI Realtime Voice API works by maintaining a long-lived session between the client and OpenAI's infrastructure. Audio from the user is streamed continuously, the model processes it in real time, and responses are streamed back as audio before the user has even finished their thought in some configurations. This eliminates the transcription-then-generation-then-synthesis round trips that made older voice assistants feel sluggish.
The problems it solves are concrete: latency, conversation state management, and interruption handling. Traditional pipelines often took 1.5 to 3 seconds to respond; realtime speech-to-speech models target sub-second first-audio latency. The API also handles barge-in, meaning the model stops talking when the user starts speaking, which is essential for natural conversation.
For developers building voice agents, the API is a model layer, not a full application stack. You still need session orchestration, telephony bridges, and deployment infrastructure, which is where agent runtimes like VideoSDK's open-source agents framework come in.
Core capabilities
The Realtime API's headline capability is speech-to-speech conversation: audio in, audio out, with no intermediate text required on your side. Under the hood, the model still produces transcripts, which you can consume for logging, display, or analytics.
Tool calling lets the model invoke your application's functions mid-conversation. If a user asks to book an appointment, the model can trigger your booking function, wait for the result, and speak the outcome, all within the same session. This turns a voice interface into an actionable agent rather than a chatbot.
Multilingual support means the model can understand and respond across languages, and emerging configurations support real-time translation, where a user speaks one language and the model responds in another. Low-latency turn-taking, powered by semantic voice activity detection, keeps the conversation fluid even when users pause mid-sentence or interrupt.
Supported transports: WebRTC vs WebSocket
The Realtime API supports two connection methods, and choosing between them is one of the most consequential architectural decisions you'll make.
WebRTC is the browser-native option. It handles audio capture, encoding, jitter buffering, and playback through the browser's media stack, which means consistent performance across devices without you implementing audio processing yourself. It's the right choice for web and mobile applications where the client device holds the microphone and speaker.
WebSocket is the server-to-server option. You open a persistent socket from your backend and push raw PCM audio frames directly, receiving synthesized audio back over the same connection. This suits server-side pipelines: SIP bridges carrying phone calls, media servers processing audio, or custom pipelines where you already have raw audio and want full control over buffering and routing.
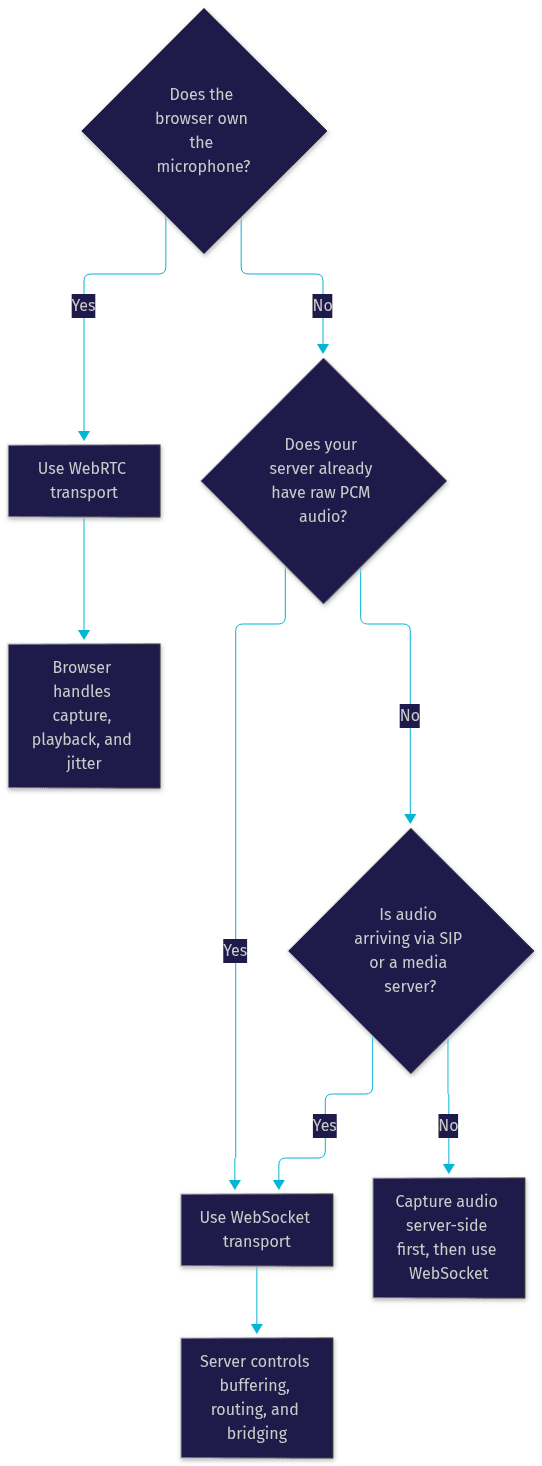
The rule of thumb: if the browser owns the audio, use WebRTC. If your server owns the audio, use WebSocket.
How a Realtime Voice Session Works
A realtime voice session is a stateful conversation between your client and the model, and understanding its lifecycle is the key to building reliable voice applications.
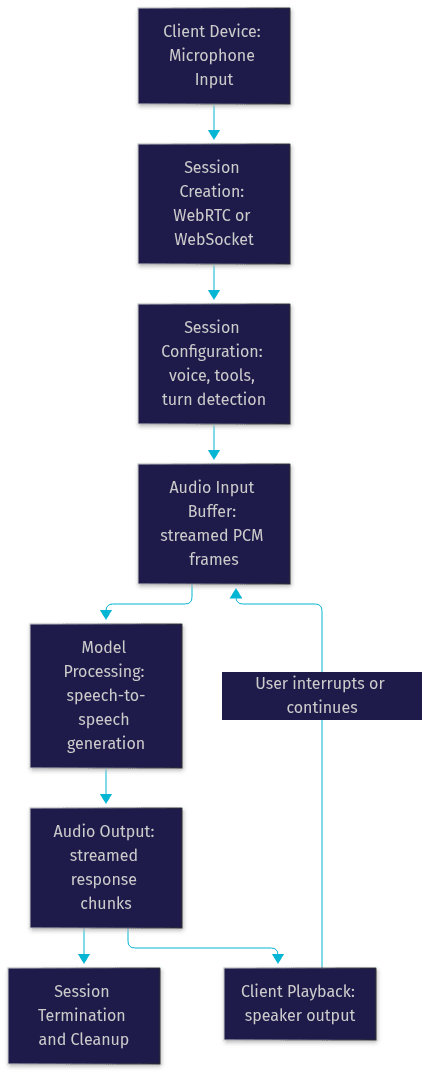
The flow begins with session creation. Your application authenticates and opens a connection, either a WebRTC peer connection or a WebSocket, and the server responds with a session-created event containing a session identifier and the default configuration. At this point you can update session parameters: the voice the model will use, the turn detection mode, the audio format, instructions that define the assistant's persona, and the tools available to it.
Once configured, audio flows continuously. The client appends incoming audio into the session's input buffer, and the model listens constantly. When turn detection decides the user has finished speaking, the model generates a response, streaming audio back in chunks. Your client plays those chunks as they arrive rather than waiting for the complete response, which is what keeps perceived latency low.
If the user interrupts, the model cancels the in-progress response, clears any unplayed audio, and returns to listening. When the conversation ends, the session is closed and its resources are released.
Session lifecycle and events
The Realtime API is event-driven, and every state change arrives as a discrete event your application reacts to. The three most important are session creation, session updates, and response creation.
The session-created event fires when the connection is established and carries the session identifier plus the current configuration. Treat it as your initialization signal: only after it arrives should you begin streaming audio or updating parameters.
Session-update events let you change configuration mid-conversation. You can swap the voice, adjust instructions, register new tools, or toggle turn detection without tearing down the connection. This matters for dynamic applications, for example switching the assistant's language when the user switches, or enabling a booking tool only after the user has authenticated.
Response-creation events mark the boundary between listening and speaking. When the model begins generating, you'll see events describing the response being created, audio chunks as they stream, and a completion event when the response finishes. Tracking these events correctly is what lets your UI show accurate listening and speaking states, and what lets your backend log full transcripts for analytics.
Turn detection and latency considerations
Turn detection is the mechanism that decides when the user has finished speaking and the model should respond. The Realtime API uses semantic voice activity detection, which goes beyond simple silence detection: it considers whether an utterance appears complete in meaning, so a mid-sentence pause doesn't trigger a premature response.
First-audio latency, the time between the user finishing speaking and the first chunk of model speech arriving, is the metric users feel most. The speech-to-speech architecture targets sub-second first audio, but your transport choice, network conditions, and client buffering all add overhead. WebRTC's built-in jitter handling often delivers more consistent perceived latency in browsers, while WebSocket gives you control over buffering at the cost of implementing that handling yourself.
For latency-critical applications, keep the audio path short. Avoid routing audio through unnecessary intermediary servers, and prefer streaming playback over accumulating the full response before playing it.
Choosing the Right Transport for Your Application
Transport choice shapes your entire architecture, so it deserves a deliberate decision rather than a default. The framework below covers the main scenarios.
Start with one question: where does the audio originate? If it originates on a user's device with a browser or mobile app handling the microphone, WebRTC is almost always correct. The browser's media stack handles capture, echo cancellation, noise suppression, and playback synchronization, and the Realtime API's WebRTC endpoint manages the peer connection negotiation for you.
If the audio originates on your server, such as a SIP trunk delivering a phone call, a media server processing recorded audio, or a pipeline that already produces PCM frames, WebSocket is the right fit. You push audio frames directly over the socket and receive responses on the same connection, with no browser in the loop.
Hybrid architectures are also valid. A phone-based AI agent might receive calls through a telephony provider, bridge them into a realtime session over WebSocket, and simultaneously connect a human supervisor through a WebRTC-based interface.
When to use WebRTC
WebRTC shines in browser-centric applications: web-based voice assistants, in-app support widgets, and any product where the user talks directly through their browser or mobile WebView. The browser's media track handling means you attach the microphone track to the peer connection and the API's audio output arrives as a track you play directly, with no manual frame management.
Performance is the second reason. WebRTC was designed for real-time media, with built-in congestion control, jitter buffering, and adaptive bitrate behavior. On inconsistent networks, such as mobile connections, this often produces smoother conversations than a hand-rolled WebSocket audio pipeline.
Use WebRTC when you want fast time-to-market for a web voice product and don't need server-side access to the raw audio stream.
When to use WebSockets
WebSockets are the choice for server-side ingestion. If you're building an AI phone agent, your telephony provider delivers audio from the PSTN to your server, and that audio needs to reach the model. A WebSocket connection from your server to the Realtime API carries those frames directly.
SIP and media-stream bridges are the canonical case. Providers like Twilio, Telnyx, and Plivo stream call audio to your backend, and your backend relays it into a realtime session. VideoSDK's telephony and SIP integration follows exactly this pattern, bridging traditional phone calls into WebRTC-based rooms where AI agents participate.
Custom audio pipelines are the third case. If you're processing audio before sending it, mixing multiple streams, or generating audio from a non-microphone source, WebSocket gives you frame-level control that WebRTC's managed tracks don't.
Building a Voice Assistant with the Realtime API
Building a production voice assistant on the Realtime API follows a recognizable high-level path, regardless of transport.
First, design your session configuration. Decide the assistant's persona and instructions, the voice it will use, the tools it can call, and the turn detection mode. These choices define the product experience more than any code will.
Second, build your token layer. The client should never hold your permanent OpenAI API key. Instead, your backend generates a short-lived ephemeral secret scoped to a single session and hands it to the client. This is a hard security requirement, not a nice-to-have.
Third, implement the audio path. For WebRTC, attach the microphone track and play the returned track. For WebSocket, stream PCM audio frames in and route response chunks to your playback or telephony bridge.
Fourth, handle the event stream. Maintain accurate listening and speaking states, log transcripts as they arrive, and execute tool calls when the model requests them, returning results over the same session.
Finally, wrap the whole thing in operational tooling: logging, session analytics, error handling, and reconnection logic. Agent runtimes like VideoSDK's AI agents framework provide much of this scaffolding out of the box, including session management, observability, and deployment options from managed cloud to self-hosted Kubernetes.
Ephemeral client secrets and security
Ephemeral client secrets exist because browser-based clients cannot keep secrets. If your permanent API key shipped to the browser, any user could extract it and run up charges against your account.
The mechanism works like this: your backend requests a short-lived secret from OpenAI, scoped to a single realtime session and expiring within minutes. The client uses that secret to establish its WebRTC or WebSocket connection. Even if the secret is intercepted, it's useless after expiry and can't be replayed for a different session.
Best practices are straightforward. Generate a fresh secret for every session, never cache and reuse them, keep expiry windows tight, and serve them only over authenticated endpoints so you know which user is starting which session. Rate-limit secret generation to prevent abuse.
Managing audio streams and voice output
The Realtime API's native audio format is 24 kHz PCM, and matching that format on your side avoids resampling artifacts and wasted CPU. If your audio source produces a different sample rate, such as the 8 kHz audio typical of phone networks, resample before sending, and resample the model's output back for the return path.
Voice selection happens at the session level. The API offers a set of built-in voices with distinct characteristics, and you can change the voice mid-session via a session update, which enables features like per-user voice preferences or multilingual agents that switch voices by language.
On the output side, the practical concern is playback handling. Response audio arrives in chunks, and you should play chunks as they arrive rather than buffering the full response. When the user interrupts, discard any queued but unplayed audio immediately, otherwise the assistant keeps talking over the user and the conversation breaks down.
Best Practices for Production Deployments
Moving from prototype to production changes the requirements around reliability, privacy, and cost.
Start with connection hygiene. Realtime sessions are stateful, so a dropped connection loses conversation context unless you plan for it. Implement session resumption where the platform supports it, and design your application so a failed session degrades gracefully rather than hanging.
Monitor the metrics that matter: first-audio latency, session duration, interruption frequency, and tool call success rates. These reveal whether the experience users actually receive matches what you designed. VideoSDK's agent observability tooling captures exactly these signals for voice agent deployments.
Control costs with session limits. Cap maximum session duration, cap total audio minutes per user, and enforce idle timeouts so abandoned sessions don't run indefinitely. Log every session with its transcript for dispute resolution and quality review.
Finally, test on real networks. Latency measured on a development machine with a fast connection tells you little about how the agent behaves on a congested mobile network or a poor cellular call.
Safety identifiers and user privacy
The Realtime API supports a safety identifier header whose purpose is abuse prevention across sessions without compromising user privacy. It lets OpenAI detect and rate-limit abusive patterns tied to a user across many sessions, even though each session uses a fresh ephemeral secret.
The critical practice is hashing. Never send raw user identifiers to the API. Instead, hash your internal user ID with a stable salt before setting it as the safety identifier. The hash is consistent for the same user, so rate limiting works, but it's not reversible, so you haven't transmitted personal data to a third party.
This matters for compliance too. Under privacy frameworks like GDPR, minimizing data shared with external processors is a core obligation, and a hashed identifier is a clean way to satisfy it while retaining abuse protection.
Handling disconnections and reconnections
Network interruptions are inevitable in voice applications, especially mobile and telephony scenarios, so reconnection handling is a production requirement.
The first strategy is fast failure detection. Use heartbeat or keepalive mechanisms so your application notices a dead connection within seconds rather than waiting for a TCP timeout.
The second is state preservation. Keep the recent conversation transcript on your side, so when a new session is established you can replay or summarize prior context, letting the conversation continue rather than restart. Some agent frameworks support checkpointing conversation state for exactly this purpose.
The third is graceful fallback. If reconnection fails after a bounded number of attempts, fall back to a simpler experience: a text chat interface, a callback promise, or a human handoff. A voice agent that silently hangs up is worse than one that says it will call back.
For phone-based agents, telephony bridges add another layer. VideoSDK's SIP integration handles call survival and transfer scenarios, including warm transfer to human agents when the AI can't complete the interaction.
Common Pitfalls and How to Avoid Them
Several mistakes recur across realtime voice projects, and all of them are avoidable.
The first is shipping without configuring turn detection. If turn detection is disabled or misconfigured, the model either responds to every pause as a completed utterance, producing choppy, fragmented replies, or never responds at all. Decide your turn detection mode explicitly during session setup and test it with realistic speech patterns, including users who pause mid-sentence.
The second is embedding a static API key in a browser client. This is the most dangerous mistake on the list because it exposes your account to unlimited abuse. The fix is always the ephemeral secret pattern described earlier: backend-generated, short-lived, session-scoped.
The third is mismatched audio rates. Sending 16 kHz audio into a session configured for 24 kHz, or forgetting to resample 8 kHz telephony audio, produces garbled or failed input. Standardize on the API's native 24 kHz PCM at every boundary, and resample deliberately at the edges of your pipeline.
The fourth is blocking playback on full responses. Waiting for a complete response before playing audio multiplies perceived latency. Stream chunks as they arrive.
The fifth is ignoring interruption cleanup. If you don't discard unplayed audio when the user barges in, the assistant talks over them and the illusion of conversation collapses.
Future Directions and Roadmap
The Realtime API's trajectory through 2026 points toward richer multimodality and broader deployment surfaces.
Model versions continue to improve on latency, naturalness, and multilingual quality, with newer realtime models extending coverage across languages and improving interruption handling. Real-time translation, where the model listens in one language and speaks in another, is moving from preview toward mainstream availability, opening use cases like live interpretation agents and multilingual customer support.
On the platform side, the ecosystem around the API is maturing. Agent frameworks now handle the orchestration layer, VideoSDK's Conversational Graph adds deterministic flow control for compliance-driven conversations, and telephony integrations bring realtime voice AI to ordinary phone numbers. The practical direction is clear: the model API becomes one component in a fuller voice agent stack, and developers who understand the whole stack will ship the better products.
Definitions Glossary
Realtime session: A stateful, long-lived connection between a client and the Realtime API during which audio streams bidirectionally and conversation context is maintained.
Turn detection: The mechanism, using semantic voice activity detection, that decides when a user has finished speaking and the model should generate a response.
Ephemeral client secret: A short-lived, session-scoped credential generated server-side and used by clients to connect without ever holding the permanent API key.
WebRTC transport: The browser-native connection method where the browser's media stack handles audio capture, playback, and jitter management through media tracks.
WebSocket transport: The server-to-server connection method where raw PCM audio frames are pushed directly over a persistent socket, suited to SIP bridges and custom pipelines.
Safety identifier: A hashed user identifier sent with requests so the provider can detect abuse across sessions without receiving personal data.
Key Takeaways
- The OpenAI Realtime Voice API enables true speech-to-speech conversation in a single session, eliminating the multi-service pipeline that made older voice assistants slow.
- Choose WebRTC when the browser owns the microphone and WebSocket when your server owns the audio, such as SIP and telephony bridges.
- Ephemeral client secrets are mandatory for browser clients; a permanent API key in the browser is a critical security failure.
- Semantic turn detection and streamed playback are what make conversations feel natural, so configure both deliberately and test with realistic speech.
- Production deployments need hashed safety identifiers, reconnection handling, session limits, and latency monitoring, which agent runtimes like VideoSDK's provide as built-in infrastructure.
Conclusion
The OpenAI Realtime Voice API has made natural, low-latency voice conversation a buildable product feature rather than a research demo. The developers who succeed with it treat the model as one layer in a full stack: transport choice, session security, audio handling, and operational monitoring all carry equal weight. Start with WebRTC if you're building for the browser, generate ephemeral secrets from your backend, and instrument first-audio latency from day one. To go further, explore VideoSDK's AI agents documentation for orchestration, telephony, and deployment tooling, grab a free account at app.videosdk.live, and check the code samples to accelerate your prototype. What are you building with the OpenAI Realtime Voice API? Drop a comment, I'd love to hear what kind of voice agent use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ