


The OpenAI text to speech voice API is a cloud-based REST service that converts written text into natural-sounding spoken audio using models like tts-1, tts-1-hd, and gpt-4o-mini-tts. Developers send text along with a chosen voice preset to a single endpoint and receive an audio payload, either as a complete file or as a streaming response. It powers voice assistants, audiobooks, accessibility tools, and IVR systems, and pairs naturally with real-time communication platforms like VideoSDK for live voice experiences.
Introduction
Voice is becoming the default interface. Developers building chatbots, support lines, and content platforms increasingly expect speech output that sounds human rather than robotic, and they expect it from a simple API call rather than a self-hosted synthesis stack. That shift explains the surge of interest in the OpenAI text to speech voice API since its introduction and through its 2026 model lineup.
The appeal is straightforward: one authenticated request, a handful of parameters, and you get studio-quality audio back. There is no model training, no GPU fleet, and no audio engineering pipeline to maintain. You pick a model, pick a voice, send text, and receive audio.
This guide walks through the full developer surface of the API: what it is, how requests and responses flow, how to authenticate, how to choose voices and models, how streaming works, what it costs, and how to avoid the quality and latency traps that catch first-time integrators. By the end, you will know exactly how to plan a production integration.
What Is the OpenAI Text to Speech Voice API?
The OpenAI text to speech voice API is defined as a hosted speech synthesis service exposed through a REST endpoint that accepts text input and returns generated spoken audio. It sits alongside OpenAI's other API products and uses the same account, API key, and billing infrastructure, so a team already calling the chat completions endpoint can add speech output without new vendor onboarding.
The service works by taking your input text, processing it through a neural speech synthesis model, and rendering the result into an audio encoding such as MP3 or PCM. The voice you hear is a preset persona baked into the model, such as alloy, echo, or nova, rather than a voice you train yourself. This keeps setup trivial while still offering meaningful variety across tone and delivery.
What makes it distinct from older concatenative or parametric synthesis systems is prosody. The models handle pacing, emphasis, and intonation from punctuation and phrasing alone, so well-written input text largely determines output quality. For developers, that means the API is a text-quality amplifier: good copy becomes good audio.
Core Features and Model Options in the OpenAI Text to Speech Voice API
Every request to the OpenAI text to speech voice API revolves around four decisions: model, voice, speed, and output format. Getting these right is most of the integration work.
The model lineup currently spans three tiers. The original tts-1 model is optimized for low latency and is the default choice for real-time and interactive use cases. The tts-1-hd variant trades some latency for higher audio fidelity, which suits pre-generated content like audiobooks or narration. The newest addition, gpt-4o-mini-tts, goes further: it accepts natural-language instructions about delivery, so you can ask for an empathetic tone or an energetic read rather than relying purely on the preset persona.
Voice presets include alloy, echo, fable, onyx, nova, shimmer, and newer additions such as coral. Each preset has a distinct gender presentation, tonal character, and energy level. There is no custom voice cloning in the standard API, so voice selection is a curation exercise rather than a training exercise.
Speed control lets you compress or stretch delivery relative to the model's natural pace, which matters for accessibility settings and for matching the cadence of a conversational agent. Response formats cover compressed and raw encodings, and a streaming mode delivers audio in chunks as it is synthesized rather than waiting for the full clip.
How the API Works: Request and Response Flow
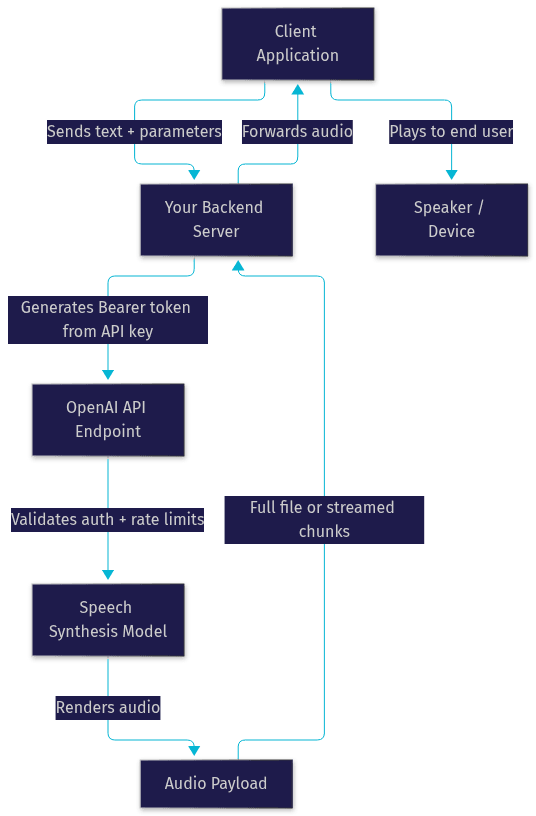
The OpenAI text to speech voice API works by receiving an authenticated HTTP request containing your text and parameters, synthesizing audio server-side, and returning the audio payload either whole or streamed. Understanding this flow helps you reason about latency, error handling, and where to place the API call in your architecture.
The typical flow looks like this:
Request Anatomy
A request contains a small set of fields, each with a clear purpose. The model field selects the synthesis engine and determines the quality-latency trade-off. The input field carries the text to speak, and it is the single biggest lever on output quality: punctuation, sentence length, and paragraph breaks all shape prosody. The voice field selects the preset persona. The speed field adjusts delivery pace around the model's natural cadence. The response format field selects the audio encoding, with compressed formats minimizing transfer size and raw formats suiting downstream processing. Newer models also accept an instructions field describing desired delivery style in plain language.
Response Details
The response is an audio payload, not a JSON document. The content type reflects the chosen encoding, for example an audio MPEG type for MP3 output. When streaming is enabled, audio chunks arrive progressively as synthesis completes, which lets a client start playback before the full clip exists. This is the difference between a user hearing the first word in a few hundred milliseconds versus waiting seconds for a long passage. Non-streaming responses are simpler to handle and fine for pre-generated content. Errors, when they occur, come back as structured JSON with an error type and message, so your error handling path parses a different body shape than your success path.
Setting Up Authentication and Access
Access starts with an OpenAI account and an API key generated from the platform's key management dashboard. Every request carries this key as a Bearer token in the authorization header, and the platform validates it against your account's limits and billing before any synthesis happens.
The critical rule: never expose the key in a browser, mobile binary, or any client-side code. Treat it like a database password. All calls to the speech endpoint should originate from a server you control, with the key stored in a secrets manager or environment configuration rather than committed to source control. If your app needs client-initiated speech, have your backend expose its own thin endpoint that injects the key server-side.
Rotate keys periodically, scope monitoring to usage anomalies, and set hard spending limits on the account so a runaway loop in your code cannot produce a surprise bill. Teams integrating speech into live products also typically add their own application-layer authentication in front of the proxy endpoint, so only legitimate users can trigger paid synthesis calls.
Choosing the Right Voice and Model
Voice and model selection is a design decision, not a default. The right pairing depends on your product's personality, your latency budget, and your cost ceiling.
For models, the practical rule is simple: use the low-latency tier for anything interactive, where a user is waiting for a response, and use the high-definition or instruction-following tier for anything pre-generated, where quality compounds over long listening sessions. For voices, audition several presets against your actual copy rather than picking from descriptions alone, because the same voice reads marketing copy and technical documentation very differently.
| Voice | Character | Best For |
|---|---|---|
| Alloy | Neutral, balanced, widely used | General-purpose assistants and product narration |
| Echo | Clear, steady, measured | Corporate, technical, and instructional content |
| Fable | Expressive, storytelling energy | Audiobooks and narrative content |
| Onyx | Deep, authoritative | News reads and formal announcements |
| Nova | Bright, energetic | Consumer apps and marketing audio |
| Shimmer | Soft, warm, approachable | Wellness, meditation, and accessibility tools |
| Coral | Conversational, modern | Chatbots and casual voice agents |
The most important row depends on your use case, but in practice teams building conversational agents gravitate toward alloy or coral for neutrality, while content teams split between fable and onyx depending on whether the material is narrative or informational.
Managing Audio Output Formats and Streaming
The format and streaming choices determine how audio moves through your system. Compressed formats like MP3 minimize bandwidth and play everywhere, making them the safe default for web and mobile playback. Raw formats like PCM suit cases where you pipe audio into another system, such as a telephony gateway or a real-time communication SDK, without an intermediate decode step. WAV wraps PCM in a file header and is convenient for storage and editing workflows.
Streaming changes the delivery model rather than the audio itself:
For interactive voice experiences, streaming is the difference between a responsive agent and a sluggish one. A common production pattern is to stream synthesized chunks directly into a real-time communication layer, for example a VideoSDK audio room, so remote participants hear the agent speak with minimal delay. VideoSDK's audio calling and AI agent infrastructure is built for exactly this kind of low-latency audio piping, and its AI agents documentation covers connecting synthesis pipelines into live sessions.
Pricing, Rate Limits, and Cost Considerations
The API is priced per input character, with different rates for the standard and high-definition models, and the instruction-following tier priced separately again. Rate limits are tiered by account usage level, measured in requests and tokens per minute, and heavy users get higher ceilings automatically.
A cost example in prose: suppose a support product reads a typical 400-character response aloud on every ticket reply, and the team handles 50,000 such replies per month. That is 20 million characters of synthesis monthly. Multiplying by the per-character rate of the chosen model gives the monthly speech line item, and repeating the calculation for the high-definition tier shows exactly how much fidelity costs at that volume. This kind of arithmetic, done before launch, prevents the most common billing surprise.
Two cost controls matter in practice. First, cache or persist audio for repeated text, such as standard greetings, rather than synthesizing it fresh each time. Second, set account spending limits so a bug that loops synthesis cannot run unbounded.
Best Practices for Quality and Latency
Output quality is mostly an input-text problem. The models read your punctuation as a performance script, so text preprocessing delivers more improvement than any parameter tuning.
A practical checklist:
- Break long passages into sentences of natural spoken length; run-on sentences become run-on audio.
- Use punctuation deliberately: commas create pauses, periods create stops, and question marks change intonation.
- Spell out or rewrite ambiguous tokens, dates, and abbreviations the way you want them spoken.
- Keep the speed parameter near default; extreme values degrade naturalness.
- Prefer the low-latency model plus streaming for any interactive flow.
- Pre-generate long-form content with the higher-fidelity model and cache the files.
- Place synthesis calls close to your users regionally to cut network round-trip time.
- Add retry logic with backoff for transient errors rather than failing a user-facing flow outright.
Latency has three components: network round trip, synthesis time, and audio transfer. Streaming attacks the third, model choice attacks the second, and regional placement attacks the first. Teams that measure all three separately usually find the network hop is the piece they ignored.
Common Integration Scenarios
Four patterns cover most production use of the OpenAI text to speech voice API.
Voice assistants and chatbots: the agent's text response is synthesized and streamed to the user, often alongside a larger pipeline where speech-to-text handles the input side. Latency budgeting is critical here, and streaming is effectively mandatory.
Audiobooks and content narration: long-form text is batch-processed with the high-definition model, stored as audio files, and delivered through a normal content pipeline. Cost per character and caching strategy dominate the design.
Accessibility tools: applications read interface text, articles, or documents aloud for users who benefit from audio output. Consistent voice choice and speed control matter more than raw fidelity, and predictable behavior across sessions builds trust.
IVR and phone systems: synthesized audio feeds a telephony layer, either through a SIP integration or a WebRTC bridge. VideoSDK's telephony and SIP integration is designed for bridging traditional phone infrastructure with real-time sessions, and its Python SDK supports connecting synthesis pipelines to live media streams.
Troubleshooting and Error Handling
Most failures fall into a handful of categories. Authentication errors mean the key is missing, malformed, or revoked; check that the Bearer token is being attached server-side and that the key is still active. Permission errors indicate the account lacks access to a specific model tier, often the newest models, which may require a usage threshold or separate enablement. Rate limit errors mean too many requests or characters per minute; the fix is backoff and retry logic, plus batching small texts into fewer requests where natural. Invalid request errors usually trace to a parameter problem, such as an unsupported voice and model combination or text exceeding the per-request input limit, and the error message names the offending field. Server-side errors are transient; retry with exponential backoff and alert if they persist.
Two integration bugs account for most support tickets: playing the wrong content type, where the client tries to parse the audio payload as JSON, and silently swallowed errors, where a failed synthesis leaves a user-facing flow hanging with no audio and no message. Handle both explicitly.
Definitions Glossary
Text-to-Speech (TTS): The conversion of written text into spoken audio by a software system. Modern neural TTS, like the OpenAI text to speech voice API, generates natural prosody directly from the input text.
Voice Preset: A named persona, such as alloy or nova, baked into a synthesis model that determines the tone and delivery of generated speech. Presets are selected per request rather than trained.
Streaming Audio Response: A delivery mode where synthesized audio is sent in progressive chunks as it is produced, letting playback begin before the full clip is ready. Essential for interactive voice applications.
Bearer Token: An authentication credential passed in the HTTP authorization header that proves the request comes from your API account. OpenAI API keys are used this way and must be kept server-side.
PCM: An uncompressed raw audio encoding suited to piping audio into telephony gateways or real-time communication SDKs like VideoSDK audio rooms without intermediate decoding.
Key Takeaways
- The OpenAI text to speech voice API converts text to natural spoken audio through a single authenticated REST endpoint, with no model training or audio infrastructure required.
- Model choice is a latency-versus-fidelity trade: the low-latency tier for interactive flows, the high-definition and instruction-following tiers for pre-generated content.
- Streaming delivery is the single biggest latency lever for voice assistants, letting playback begin on the first chunk instead of waiting for the full clip.
- Output quality is driven primarily by input text quality, so punctuation and sentence structure are your main tuning tools.
- For live voice experiences, pairing synthesis output with a real-time communication layer such as VideoSDK's audio rooms or AI agent infrastructure keeps end-to-end delay low.
Conclusion
The OpenAI text to speech voice API compresses what used to be an entire audio engineering stack into a single request: pick a model, pick a voice, send text, receive speech. The engineering work shifts to the parts around the call, including secure key handling, streaming delivery, cost arithmetic, and text preprocessing, and those are exactly the areas this guide covered.
Start by auditioning voices against your real copy, wire up streaming before you optimize anything else, and run the character-volume cost math before launch. The official OpenAI audio documentation is the source of truth for current models, voices, and rates. And if you are building live voice agents, VideoSDK's AI agents quickstart shows how to pipe synthesized speech into real-time sessions with low latency. What are you building with the OpenAI text to speech voice API? Drop a comment, I'd love to hear what kind of voice experience you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ