


An AI noise remover is a tool that uses machine learning models, typically neural networks trained on speech and noise pairs, to separate a clean voice signal from background noise in a recording or live stream. Unlike traditional noise gates and EQ, modern AI noise removers work in real time, preserve natural voice timbre, and require no manual tuning. If you build apps with embedded audio or video, VideoSDK includes built-in noise suppression so participants get cleaner calls without any extra integration work.
Listeners forgive a mediocre camera far more easily than they forgive unlistenable audio. Podcasters lose subscribers, remote teams lose meeting clarity, and streamers lose viewers when hiss, keyboard clicks, or air conditioning hum sits under the voice track. For decades, cleaning that audio meant wrestling with noise gates, EQ sweeps, and DSP plugins that demanded real engineering judgment. That era is ending. AI noise removers now handle the problem in seconds, often in real time, and often with no technical knowledge required. This guide explains how the technology actually works under the hood, how to evaluate the leading tools, and how to pick the right one for your specific use case in 2026.
What Is an AI Noise Remover?
An AI noise remover is defined as software that applies machine learning models to an audio signal in order to suppress unwanted background noise while preserving the primary speech or music content. It works by analyzing the spectral and temporal patterns of the incoming audio, identifying which components statistically resemble noise versus human voice, and reconstructing a cleaned signal from only the desirable components.
The distinction from traditional methods matters. A classic noise gate simply mutes audio below a volume threshold, which fails badly for steady low-level noise like fan hum. Spectral gating, popularized by open-source projects in the DSP era, subtracts a noise profile from the signal's frequency spectrum, but it often leaves metallic artifacts and watery-sounding speech. Neural speech enhancement, the approach behind modern AI noise removers, learns from thousands of hours of paired noisy and clean recordings, so it can remove noise it has never explicitly been told about, including dogs barking, street traffic, and overlapping keyboard typing.
For developers, the practical consequence is that an AI noise remover can be treated as a preprocessing stage: feed it raw audio, receive cleaned audio, and move on.
How AI Noise Removal Works
Every AI noise remover follows the same core pipeline: audio capture, spectral analysis, neural model inference, and signal reconstruction. The audio is first captured and converted from a time-domain waveform into a frequency-domain representation, usually a spectrogram, which shows how energy distributes across frequencies over time. This representation is what the neural network actually sees.
The neural model then processes that spectrogram and produces a mask or an enhanced version of it, effectively deciding, frame by frame, which parts of the spectrum belong to the voice and which belong to noise. The cleaned spectrogram is converted back into a time-domain waveform, and post-processing stages may apply loudness normalization or residual artifact smoothing.
Three model families dominate in 2026. Convolutional neural networks remain the workhorse for real-time noise removal because they are fast and lightweight enough to run on a single CPU core. Transformer-based models capture longer-range context, which helps them distinguish speech from speech-like noise, at the cost of higher latency and compute. Diffusion-based generative models produce the most natural-sounding results for offline restoration, since they can regenerate damaged speech segments, but they are still too slow for live use.
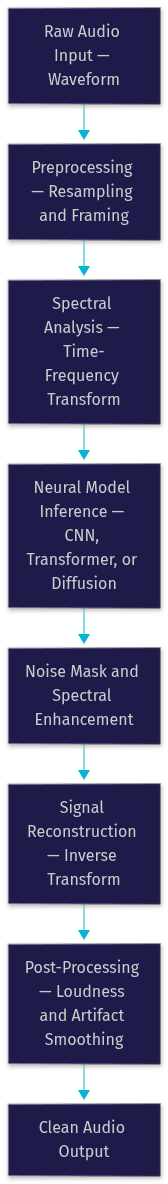
The key engineering tradeoff across the pipeline is accuracy versus latency. Offline tools can afford heavy models and multiple refinement passes, while real-time noise removal for calls and streams must complete inference in well under 50 milliseconds to avoid noticeable conversation lag.
Key Features to Look For in an AI Noise Remover
Not every AI noise remover is built for the same job, so evaluate candidates against a short list of capabilities before committing.
Real-time processing. If you clean live meetings or streams, the tool must process audio faster than it arrives. Offline-only tools are fine for podcast post-production but useless for a live call.
High-fidelity and Dolby-grade output. Tools that support HD audio and Dolby-style processing preserve the full frequency range of the voice, which matters for music-adjacent content and professional voice-overs.
Privacy guarantees. Check whether audio is processed in the cloud or on-device. Cloud processing sends your recordings to third-party servers, which is a compliance problem for healthcare, legal, and enterprise use.
Batch versus streaming modes. Batch processing handles long files efficiently for post-production, while streaming mode handles continuous live input.
Format compatibility. Confirm support for your source formats, ideally including lossless inputs like WAV and FLAC, and check export options for your editing suite.
Common Use Cases for AI Voice Cleaning
Podcasts. Home studios rarely have acoustic treatment, so HVAC hum and room echo leak into every episode. AI voice cleaning lets podcasters record in imperfect spaces and still ship broadcast-quality audio.
Video voice-overs. Creators recording narration on laptops or budget microphones use an AI audio cleaner to close the quality gap with studio productions, often saving an entire re-record session.
Remote meetings. Real-time noise removal suppresses keyboard typing, family noise, and office chatter on both ends of a call. Platforms built on VideoSDK get this through built-in noise suppression in the SDK, so meeting apps ship cleaner audio without custom DSP work.
Field recordings. Interviews captured outdoors or in cafes contain wind, traffic, and crowd noise that traditional tools cannot cleanly separate. Neural models trained on diverse noise conditions handle these far better.
Live streaming. Streamers cannot fix audio in post, so real-time background noise reduction running locally on the machine is the only viable option.
Evaluating AI Noise Remover Tools: A Scoring Framework
Most comparison articles rank tools by marketing claims. A better approach is to score each candidate on five dimensions, weighted for your use case, so the decision is defensible rather than vibes-based.
Accuracy. Test each tool on the same 30-second clip of your actual worst-case audio. Score the output for noise removal completeness, voice preservation, and artifacts. Artifacts matter more than most people expect: aggressive removal that makes the speaker sound underwater is worse than mild residual noise.
Latency. For live use, measure the delay between input and output. Anything above roughly 50 milliseconds becomes audible as an echo in conversation. Offline tools can ignore this dimension.
Privacy. Determine where inference happens. On-device processing keeps audio local, which is essential for regulated industries. Cloud processing is fine for public content.
Pricing. Compare cost per minute of processed audio, not just headline plan prices. Free tiers with per-minute caps add up quickly for weekly podcast production.
Platform support. Check for a web interface, desktop app, mobile SDK, and API access if you plan to embed noise removal into your own product.
Score each dimension from 1 to 5, multiply by your use-case weights, and total the results. A podcaster might weight accuracy and pricing heavily; a meeting-app developer weights latency and privacy instead.
Top AI Noise Remover Solutions Compared
The following overviews are deliberately brief and unbiased. Model types and pricing change frequently, so verify current details on each vendor's site before purchasing.
VEED. A browser-based online noise remover aimed at video creators. It handles background noise removal as part of a broader editing suite, which makes it convenient for creators who want cleanup and editing in one place. Strength: integrated workflow. Weakness: cloud-only processing means uploads of your raw footage.
LALAL.AI. A vocal and instrument separation service whose speech enhancement is strong for music-adjacent content. It processes files in the cloud with per-minute pricing. Strength: excellent separation quality on mixed content. Weakness: no real-time mode.
Adobe Podcast Enhance. Adobe's free-tier speech enhancement tool became a default recommendation for podcasters because of its natural-sounding output. Strength: remarkably good voice restoration for the price. Weakness: processing is offline and cloud-based, with length limits on free usage.
Krisp. A real-time noise removal layer that sits between your microphone and any calling app, suppressing noise on both incoming and outgoing audio. Strength: genuine real-time performance with local processing. Weakness: subscription pricing adds up for occasional users.
VideoSDK noise suppression. For developers building calling or streaming apps, VideoSDK's SDKs include built-in noise suppression alongside the full real-time communication stack, so participants get cleaner audio with zero additional integration. Strength: real-time, embedded, no separate vendor. Weakness: it is an SDK capability, not a standalone file-cleaning tool for post-production.
[LINKABLE ASSET — comparison table]
| Tool | Model Approach | Real-Time | Privacy | Pricing Model | Best For |
|---|---|---|---|---|---|
| VEED | Cloud neural enhancement | No | Cloud only | Subscription | Video creators wanting an all-in-one editor |
| LALAL.AI | Cloud separation models | No | Cloud only | Per-minute credits | Music and mixed-content cleanup |
| Adobe Podcast Enhance | Cloud speech enhancement | No | Cloud only | Free tier plus paid limits | Podcast post-production |
| Krisp | On-device neural model | Yes | Local processing | Subscription | Live calls and remote meetings |
| VideoSDK | Embedded SDK noise suppression | Yes | Runs in the RTC pipeline | Included in SDK plans | Developers building call and stream apps |
The most important row depends on your mode of work: if audio is live, only Krisp and VideoSDK qualify; if audio is a file, the offline cloud tools deliver higher fidelity per dollar.
Choosing the Right AI Noise Remover for Your Project
The decision comes down to four questions, in order: is your audio live or recorded, is privacy a hard requirement, what is your budget, and do you need to embed the capability into your own product?
In prose: live audio forces you into real-time tools, and a strict privacy requirement forces those tools to run on-device. Recorded files open the cheaper cloud options, where your budget and processing volume decide between free tiers and paid per-minute services. Developers building their own applications should skip standalone tools entirely and choose an SDK with noise suppression built in, since stitching a third-party cleaner into a real-time call pipeline introduces latency and integration risk that an integrated SDK avoids.
Step-by-Step Workflow: Cleaning Audio Without Code
Every mainstream online noise remover follows the same five-step workflow, so learning it once transfers across tools.
Step 1: Upload the source file. Start from the highest-quality source you have, ideally a lossless WAV recording rather than a compressed MP3. Compression already discards spectral detail that the AI model needs to distinguish noise from voice.
Step 2: Preview the automatic cleanup. Most tools run their default model immediately. Listen to at least 30 seconds of the preview, focusing on a section where speech overlaps with the worst noise, since that is where models differ most.
Step 3: Adjust the noise-cancelling level. If the tool exposes a strength slider, start conservative. Over-aggressive settings produce the metallic, underwater artifact that listeners hate more than the original noise.
Step 4: Compare against the original. Toggle between the cleaned and original audio. If the voice sounds thinner or more distant after cleaning, reduce the strength and re-run.
Step 5: Download and archive. Export in a lossless format for further editing, and always keep the original recording. AI models improve every year, and a better model next year can re-clean the original better than re-processing an already-cleaned file.
Common Pitfalls
Three mistakes account for most disappointing results. First, cleaning already-compressed audio: MP3 sources lose the spectral detail the model needs, so always record or obtain lossless originals. Second, stacking multiple noise removers in sequence, which compounds artifacts instead of improving cleanliness. Third, ignoring silent sections: check a passage with no speech to hear what the tool does to pure noise, because that reveals whether it removes noise or merely ducks it.
Future Trends in AI Audio Cleaning
Three shifts are reshaping the field through 2026 and beyond. On-device models are shrinking fast: quantized neural networks now run real-time speech enhancement on phones and laptops without cloud round-trips, which collapses the privacy and latency objections simultaneously. Multimodal denoising is the second shift, where models analyze audio alongside video frames, letting a system see that a door is opening and anticipate the sound, producing cleaner separation than audio-only models can achieve. Third, open-source research continues to close the gap with commercial tools, with published models for speech enhancement approaching production quality, which pressures paid services on pricing and pushes vendors to differentiate on workflow and integration rather than raw model quality.
For developers, the direction of travel is clear: noise removal is becoming a default capability embedded in communication platforms rather than a separate product users must buy. VideoSDK's built-in noise suppression is an example of exactly this pattern, where the capability ships as part of the real-time audio and video SDK rather than as an add-on.
Definitions Glossary
AI Noise Remover: Software that applies machine learning models to suppress background noise from audio while preserving speech. Modern implementations use neural speech enhancement rather than fixed DSP rules.
Neural Speech Enhancement: A machine learning approach trained on pairs of noisy and clean recordings, enabling the model to remove noise types it was never explicitly programmed to handle.
Spectral Gating: An older noise reduction technique that subtracts a measured noise profile from the audio's frequency spectrum, often leaving metallic artifacts on the voice.
Real-Time Noise Removal: Noise suppression that processes audio faster than it is captured, typically completing inference in under 50 milliseconds so live conversations stay natural.
Noise Suppression in VideoSDK: Built-in noise suppression included in VideoSDK's real-time communication SDKs, which cleans participant audio inside the calling pipeline without any separate tool or integration effort.
Key Takeaways
- An AI noise remover uses neural networks trained on noisy and clean audio pairs, outperforming traditional noise gates and spectral gating on complex, real-world noise.
- Live audio and recorded files demand different tools: real-time use requires sub-50-millisecond on-device or embedded processing, while post-production can use heavier cloud models.
- Evaluate tools with a five-dimension scoring framework covering accuracy, latency, privacy, pricing, and platform support, weighted for your specific use case.
- Always clean from lossless sources, avoid stacking multiple removers, and archive originals because models keep improving.
- Developers building calling or streaming apps should choose an SDK with built-in noise suppression, such as VideoSDK, instead of wiring a third-party cleaner into the real-time pipeline.
Conclusion
AI noise removers have turned one of audio production's most tedious problems into a near-automatic step, whether you are shipping a weekly podcast, running remote meetings, or building the next calling app. The right choice depends on your constraints: live versus recorded, private versus public, standalone tool versus embedded SDK. Use the decision tree above to narrow your options, then test your shortlist on your own worst-case audio before committing. If you are building an app with real-time voice or video, try VideoSDK's free tier and experience built-in noise suppression alongside sub-300ms latency communication. What are you building with AI audio cleaning? Drop a comment, I'd love to hear what kind of noise problem you are solving.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ