


AI noise cancelling software uses machine-learning models to remove background noise from your microphone and speaker audio in real time, typically achieving 20 to 40 dB of suppression with under 50 ms of added latency. Unlike traditional DSP filters, these models adapt to new noise types automatically. This guide explains how the technology works, what features to compare, and how to pick the right tool, including how VideoSDK's built-in noise suppression fits into real-time calling apps.
Every remote worker knows the moment. You join a call from a cafe, and the next five minutes are a tug-of-war between your voice and an espresso machine. Podcasters fight HVAC hum. Streamers battle keyboard clatter. Gamers get drowned out by fan noise. Background noise is one of the most persistent friction points in real-time communication, and it is exactly the problem ai noise cancelling software was built to solve.
This article breaks down what AI-driven noise cancellation actually is, how it differs from the DSP filters of the past, the core technologies behind it, and a practical framework for choosing the right tool for your workflow in 2026.
What Is AI Noise Cancelling Software?
AI noise cancelling software is defined as an application or SDK that uses trained machine-learning models to separate human speech from background noise in an audio stream, in real time, without manual tuning. Instead of relying on fixed frequency filters, the software runs your microphone signal through a neural network that has learned, from thousands of hours of examples, what speech looks like versus what noise looks like.
The distinction from traditional DSP matters. Classic noise suppression uses static techniques: spectral subtraction, noise gates, and high-pass filters. These work reasonably well for steady, predictable noise like a constant hum, but they fail against dynamic, non-stationary noise like a barking dog, a siren, or overlapping conversations. They also tend to introduce audible artifacts, the metallic, underwater sound you have probably heard on cheap conference calls.
AI-powered noise suppression, by contrast, performs speech enhancement. The model predicts, frame by frame, which parts of the audio spectrum belong to a human voice and suppresses everything else. Modern systems handle non-stationary noise that DSP filters simply cannot, and they do it with fewer artifacts. That is why ai noise cancelling software has largely displaced manual EQ and gate-based workflows in professional audio over the past few years.
How AI Improves Noise Cancellation
The core advantage of machine learning in noise suppression is adaptivity. A neural network trained on diverse noise libraries generalizes to noise types it has never explicitly encountered, because it has learned the statistical signature of speech rather than the signature of specific noises.
Most production systems use a technique called spectral masking. The model analyzes short overlapping windows of incoming audio, typically 20 to 40 ms each, and produces a per-frequency-band gain mask. Bands dominated by speech keep their energy; bands dominated by noise are attenuated. Because this happens on every frame in a rolling pipeline, the result is continuous, real-time noise reduction with low latency, usually in the 10 to 40 ms range on modern hardware.
Two benefits stand out. First, suppression ratios: well-trained models routinely achieve 20 dB or more of noise reduction while preserving speech intelligibility, which is difficult for hand-tuned DSP. Second, robustness: when the noise environment changes, say you move from a quiet room to a street, the model adapts within a few frames rather than requiring you to re-profile the noise floor.
For developers building real-time apps, this matters even more. VideoSDK, for example, ships built-in noise suppression as part of its video calling SDK, so every participant's audio is cleaned before it reaches other participants, without each user installing a separate tool.
Core Technologies Behind AI Noise Cancelling
Modern deep learning noise suppression rests on three architecture families. Convolutional neural networks (CNNs) excel at extracting local spectral patterns and are efficient enough for on-device inference. Recurrent architectures (RNNs and LSTMs) model temporal continuity, which helps the network track speech through fluctuating noise. More recently, transformer-based and conformer-based models have pushed accuracy further by attending to longer-range context, at the cost of higher compute requirements.
Training data comes from two sources stitched together: clean speech corpora (studio recordings, audiobook narrations, multi-language speech datasets) and noise libraries (urban soundscapes, household sounds, crowd noise). During training, noise is mixed onto clean speech at random signal-to-noise ratios, and the model learns to reconstruct the clean signal. Data augmentation, such as pitch shifting and reverberation, improves robustness across real-world microphones.
Deployment splits into two camps. On-device inference runs the model locally on your CPU, GPU, or a dedicated neural accelerator, keeping audio private and latency minimal. Cloud processing sends audio to a server-side model, which enables larger, more accurate models but adds network latency and privacy considerations. Most consumer tools now run compact models locally; most enterprise call-center platforms still process server-side.
Here is what the typical real-time pipeline looks like:
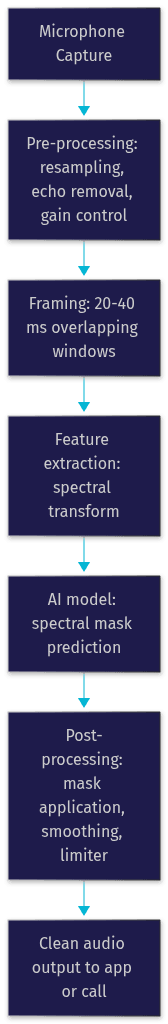
The entire loop, capture to output, must complete within the latency budget of the call. That is why model size and inference efficiency matter as much as raw accuracy.
Key Features to Look For
When comparing tools, five capabilities separate serious products from gimmicks.
Bi-directional cancellation. The best tools filter both your microphone (outbound) and the incoming audio from other participants (inbound), so you hear others clearly even when their environment is noisy.
Latency. For real-time conversation, added latency should stay under 50 ms, and ideally under 10 ms for music or streaming workflows. Anything higher creates the walkie-talkie effect that kills natural conversation.
Privacy and local processing. On-device inference means your audio never leaves your machine. This is non-negotiable for legal, medical, and financial conversations.
Platform integration. Check whether the tool works as a virtual microphone that Zoom, Teams, Discord, OBS, and browsers can all select, versus only hooking into specific apps.
Customizable profiles. Presets tuned for office, cafe, outdoor, or studio environments let you trade suppression aggressiveness against speech naturalness.
Top Use Cases
Remote work meetings are the dominant scenario. A good AI microphone filter turns a noisy apartment into a conference-grade environment, which matters more as hybrid work normalizes calls from anywhere.
Live streaming and podcasting benefit from consistent audio quality, since viewers tolerate mediocre video far longer than bad audio. Real-time noise reduction also removes the need for heavy post-production cleanup.
Gaming voice chat demands low latency above all. Sub-10 ms suppression keeps comms natural while eliminating mechanical keyboard and fan noise.
Hearing-aid assistance is an emerging and meaningful application. AI noise cancellation for hearing aids uses the same speech-enhancement models to help wearers focus on a speaker in noisy restaurants or crowds, a task where traditional DSP has struggled for decades.
Customer-support call centers apply server-side AI noise cancellation for calls at scale, cleaning agent and caller audio before it reaches transcription and analytics pipelines, which measurably improves automated transcription accuracy.
Comparison of Leading AI Noise Cancelling Solutions
The table below compares five well-known ai noise cancelling software options on the criteria that matter most. Pricing figures are approximate and change frequently, so verify before purchasing.
| Product | Approx. price (2026) | Platforms | Added latency | Privacy | AI approach |
|---|---|---|---|---|---|
| Krisp | ~$8-10/month | Windows, macOS, iOS, Android, web | Low (~20 ms) | On-device processing | Proprietary deep learning, bi-directional |
| Noise Blocker | ~$30 one-time | Windows | Very low | Fully local | Rule-based + ML hybrid, manual tuning |
| NVIDIA Broadcast (Clear Call mode) | Free with RTX GPU | Windows | Very low on GPU | Fully local | RTX-accelerated deep learning |
| Adobe Podcast Enhance | Free tier available | Browser | High (not real-time) | Cloud processing | Server-side speech enhancement |
| VideoSDK built-in suppression | Included in SDK plans | All SDK platforms (web, mobile, desktop) | Minimal, integrated | Server-side within RTC pipeline | Integrated WebRTC-level noise suppression |
Krisp remains the benchmark for cross-platform, bi-directional consumer noise cancellation. Noise Blocker suits Windows users who want a one-time purchase and full local control. NVIDIA Broadcast is the best free option if you already own an RTX graphics card, and its GPU inference keeps latency negligible. Adobe Podcast Enhance produces excellent results but is designed for recorded audio, not live calls. VideoSDK's built-in suppression is the right answer when you are building your own calling or streaming app and want every participant cleaned at the SDK level rather than depending on each user installing a third-party tool.
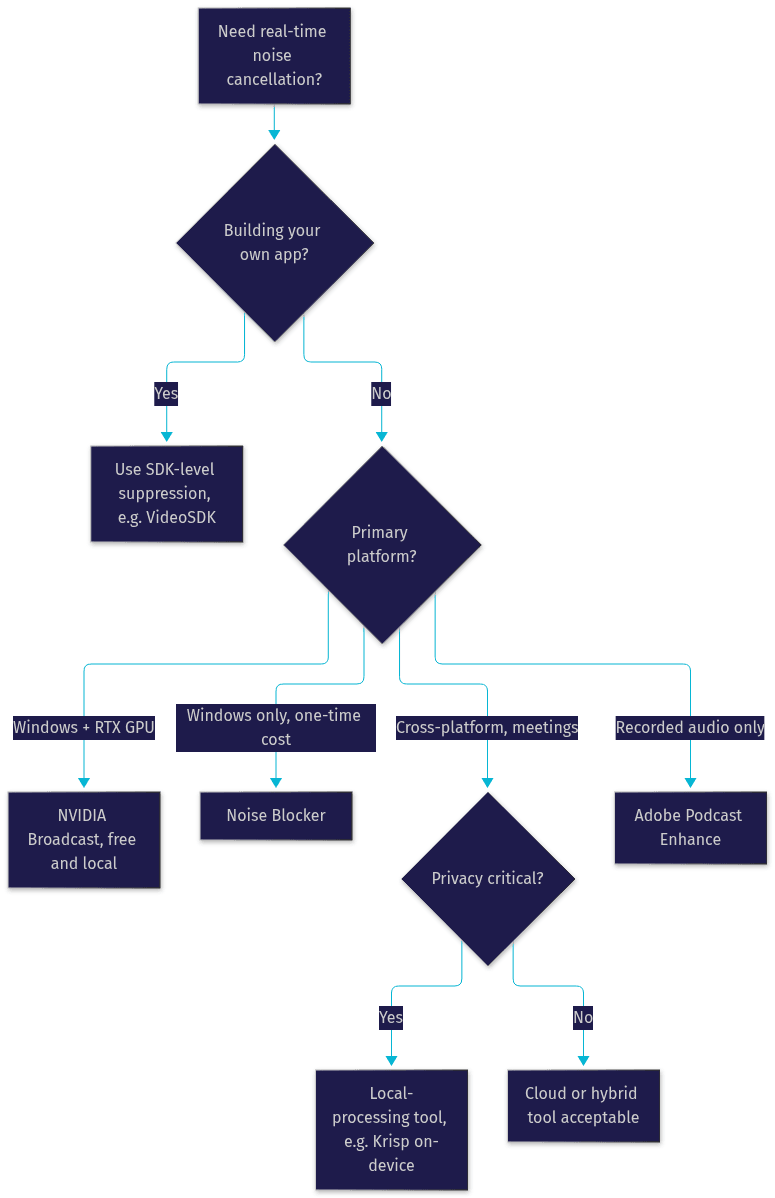
If you are deciding between these, this flowchart maps the decision:
Choosing the Right Software for Your Needs
Work through these questions in order, and the shortlist usually collapses to one or two candidates fast.
- What is your budget model? Subscription tools like Krisp keep improving monthly; one-time purchases freeze in place. For a tool you will use daily, a subscription often wins on quality.
- What OS and hardware do you have? GPU-accelerated options only make sense with compatible hardware. Mobile users need native app support, not desktop virtual microphones.
- Do you need offline or cloud processing? Regulated industries should require on-device inference. Casual users can accept cloud processing for better accuracy on difficult noise.
- What integrations are mandatory? If your workflow spans Zoom, OBS, Discord, and Chrome, you need a system-level virtual audio device, not a per-app plugin.
- Is latency or quality the priority? Music and gaming demand sub-10 ms; a weekly status call tolerates more.
Cross-reference your answers against the comparison table above. If you answered "building my own app" to the first question, skip consumer tools entirely and evaluate SDK-level suppression, which brings noise cancellation to every participant automatically.
Privacy and Local Processing Considerations
Every cloud-based noise canceller means your raw microphone audio, which includes your voice and everything around you, transits a third-party server. For most casual calls that is an acceptable trade. For lawyers, doctors, therapists, and anyone handling regulated data, it is not.
On-device inference eliminates that exposure. The model runs locally, audio never crosses the network, and the only data leaving your machine is the already-processed call audio destined for your meeting platform anyway.
How do you verify a tool actually processes locally? Three checks: read the vendor's data policy for explicit on-device claims, monitor network activity while the tool is active (a local model generates negligible traffic), and look for offline functionality. A tool that stops working without internet is processing in the cloud, full stop.
For developers building apps where privacy is a selling point, choosing an SDK with server-side suppression inside a managed RTC pipeline, like VideoSDK's, keeps audio handling within one auditable system rather than scattering it across third-party vendors.
Implementation Tips for Different Platforms
Windows
Windows is the most flexible platform for noise cancellation. Install your chosen tool, then set its virtual microphone as the default input in Windows sound settings and inside each conferencing app, since apps like Zoom override the system default. The most common pitfall is double suppression: if both your AI tool and the conferencing app's built-in suppression are active, you get compounded artifacts. Disable one. Also disable any motherboard or headset vendor audio effects, which conflict with AI filtering.
macOS
On macOS, tools that provide their own virtual audio driver handle routing automatically. For custom routing, developers and podcasters use virtual audio devices such as BlackHole to route processed audio between apps. Grant microphone permission when prompted, and check the Privacy and Security settings if a tool's audio goes silent, since macOS revokes mic access silently after some updates. Keep an eye on CPU usage: heavier models can tax fanless MacBooks during long calls.
Chrome Extension / Browser
Browser-based noise cancellation hooks into WebRTC, the same real-time media stack that powers in-browser calling. Extensions and web apps can apply suppression to the local audio track before it is published to a peer connection, which is exactly how in-browser meeting tools clean your mic without installing anything. The trade-off is browser CPU budget: heavy models in a busy tab can cause audio glitches. If you are building a browser calling app, prefer an SDK that applies suppression at the media pipeline level, like VideoSDK's JavaScript SDK, rather than bolting on a separate extension.
Mobile (iOS/Android)
Mobile relies on native SDKs rather than virtual microphones, since mobile OSes do not allow system-wide audio rerouting for third-party apps. Suppression runs inside each app's audio pipeline, typically using compact models optimized for phone CPUs and neural accelerators. The main cost is battery: continuous inference during hour-long calls measurably drains power, so efficient model quantization matters more on mobile than anywhere else. Both iOS and Android also expose OS-level voice isolation features that app SDKs can complement or replace.
Future Trends in AI Noise Cancellation
Three shifts are reshaping the field. First, multi-modal models: combining audio with visual cues, such as lip movement from your camera, lets models lock onto the active speaker and reject even overlapping human voices, a task audio-only systems still struggle with.
Second, edge-AI silicon. Dedicated neural processing units in laptops, phones, and headsets are pushing inference latency toward sub-millisecond territory while cutting power draw, enabling always-on cancellation in earbuds and hearing aids without battery anxiety.
Third, open-source momentum. Community speech-enhancement models now approach commercial quality, and benchmarking efforts such as those tracked on the DNS Challenge GitHub repository make it possible to compare deep learning noise suppression approaches on standardized data. For developers, that means SDK-level noise suppression is becoming a commodity feature, which is exactly what VideoSDK's built-in suppression represents: quality that once required a dedicated product is now part of the calling infrastructure itself.
Definitions Glossary
AI noise cancelling software: An application or SDK that uses trained machine-learning models to remove background noise from audio in real time, adapting to new noise types without manual tuning.
Spectral masking: The core technique where a neural network predicts per-frequency-band gains for each audio frame, preserving speech-dominated bands and attenuating noise-dominated ones.
DSP noise suppression: Traditional digital signal processing methods, such as spectral subtraction and noise gates, which use fixed rules and struggle with dynamic, non-stationary noise.
On-device inference: Running the noise-cancellation model locally on the user's hardware so raw audio never leaves the device, maximizing privacy and minimizing latency.
Virtual audio device: A software driver that presents processed audio as a system microphone, letting any app (Zoom, OBS, Discord) use AI-filtered sound without per-app integration.
Noise suppression in VideoSDK: Built-in AI noise removal applied inside the real-time calling pipeline, cleaning every participant's audio at the SDK level without third-party tools.
Key Takeaways
- AI noise cancelling software uses neural networks to separate speech from noise in real time, achieving 20 dB or more of suppression that traditional DSP filters cannot match on dynamic noise.
- Latency, privacy, and platform integration are the three deciding factors: aim for under 50 ms added latency, prefer on-device processing for sensitive conversations, and require system-level virtual microphone support for multi-app workflows.
- Krisp leads cross-platform consumer tools, NVIDIA Broadcast is the best free option for RTX owners, and Adobe Podcast Enhance suits recorded rather than live audio.
- Developers building calling or streaming apps should evaluate SDK-level noise suppression, such as VideoSDK's built-in noise cancellation, so every participant gets clean audio without installing anything.
- The field is moving toward multi-modal models, edge-AI chips with sub-millisecond latency, and open-source models approaching commercial quality.
Conclusion
AI noise cancelling software has gone from a nice-to-have to a baseline expectation for calls, streams, and podcasts in 2026. The right choice comes down to your budget, platform, latency tolerance, and privacy requirements, and the comparison framework above should collapse that decision quickly. If you are building your own real-time app, skip consumer tools and look at SDK-level suppression: VideoSDK's video calling SDK includes noise suppression out of the box, and you can try it free at app.videosdk.live/login. Evaluate your workflow, test a free tier, and prioritize privacy where it matters. What are you building with real-time audio? Drop a comment, I'd love to hear what kind of noise-cancellation use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ