


Streaming bytes means moving binary data through a network or file stream in small chunks instead of loading an entire payload into memory. Developers use byte streaming for large file transfers, real-time media feeds, and API responses from AI services. Frameworks like FastAPI and Node.js expose native streaming primitives, and tools like VideoSDK handle real-time audio and video streams over WebRTC with sub-300ms latency.
Moving raw bytes is the invisible backbone of the modern web. Every video call, every large file download, every token streamed from a language model, and every telemetry event your servers emit is, at the lowest level, a sequence of bytes flowing through a stream. How you move those bytes determines whether your service runs lean and fast or buckles under its own memory usage.
The naive approach, reading an entire payload into memory before sending it, works fine for a two-kilobyte JSON response. It fails spectacularly for a ten-gigabyte dataset, a live audio feed, or a model that generates output token by token. Streaming bytes solves this by processing data incrementally, keeping memory usage flat regardless of payload size.
By the end of this article you will understand how byte streaming works at the HTTP layer, how to stream bytes with FastAPI and Node.js, how to count bytes on the fly, and how durable streams guarantee exactly-once byte delivery.
What is Byte Streaming?
Byte streaming is defined as the practice of reading and writing binary data as a continuous sequence of small chunks rather than as one complete payload. A stream produces bytes on demand, and the consumer processes each chunk as it arrives, discarding it from memory once handled.
Byte streaming works by maintaining a small, fixed-size buffer between a producer and a consumer. The producer fills the buffer, the consumer drains it, and the cycle repeats until the producer signals completion. Because only the buffer, not the full payload, lives in memory, a process can stream a file of any size while using only a few kilobytes of RAM.
This contrasts with buffered loading, where the entire payload must be materialized before any of it can be used. For large files, that means huge memory spikes and long waits before the first byte reaches the client. Streaming delivers the first byte almost immediately.
Core Scenarios for Streaming Bytes
Byte streaming shows up in four dominant scenarios, and each has slightly different requirements around latency, ordering, and reliability.
File download and upload pipelines
File transfer is the classic streaming use case. A download service streams bytes from disk or object storage straight to the client, never holding the full file in memory. Uploads work the same way in reverse: the server reads the incoming request body chunk by chunk, writing each piece to storage as it arrives. This pattern lets a modest server handle thousands of concurrent multi-gigabyte transfers, because each connection only costs a small buffer. It also enables progress reporting, since the server knows exactly how many bytes have arrived at any moment.
Real-time media (audio/video) feeds
Real-time audio and video are byte streams with strict timing constraints. A video calling platform like VideoSDK routes audio and video tracks through an SFU (Selective Forwarding Unit) that forwards media chunks between participants with sub-300ms latency. The underlying principle is identical to file streaming: chunks flow producer to consumer without waiting for the full payload. The difference is that media streams are continuous and never "complete," and late bytes are worse than missing bytes, so adaptive systems drop or downsample chunks when bandwidth shrinks. VideoSDK's network-adaptive streaming handles this automatically by adjusting bitrate and resolution in real time.
API responses from AI or data services
AI services stream generated output token by token, and each token arrives as bytes on the wire. Without streaming, a user staring at a long generation waits for the entire response before seeing anything. With streaming, the first tokens render within a few hundred milliseconds. Data services benefit similarly: a query returning millions of rows can stream results as they are computed, giving clients partial results early and keeping server memory flat.
Logging and telemetry streams
Observability pipelines are byte streams that never end. Application logs, metrics, and traces flow continuously from services to collectors. Streaming keeps the producer non-blocking, so logging never stalls request handling, and lets consumers aggregate, filter, and forward events in real time.
How HTTP Handles Byte Streams
HTTP supports byte streaming natively through chunked transfer encoding. When a server knows the total payload size, it sends a Content-Length header and the client can display accurate progress. When the size is unknown ahead of time, such as with a live feed or a streaming AI response, the server uses chunked encoding: each chunk is prefixed with its byte length in hexadecimal, and a zero-length chunk marks the end of the stream.
The flow below shows how a client request travels to a server-side byte source, and how chunks flow back through the HTTP layer to the client:
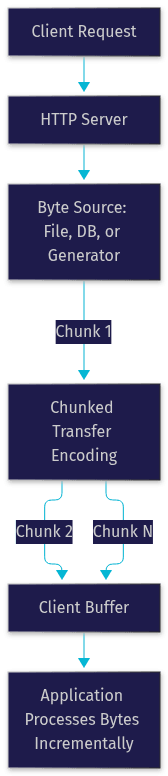
Two details matter in practice. First, chunked encoding means the server can start sending before the full response exists, which is exactly what enables streaming AI responses and live feeds. Second, the connection itself is bidirectional at the transport layer, so a client disconnect mid-stream is detectable by the server, which should stop producing bytes promptly rather than generating output nobody will read.
Streaming Bytes with FastAPI
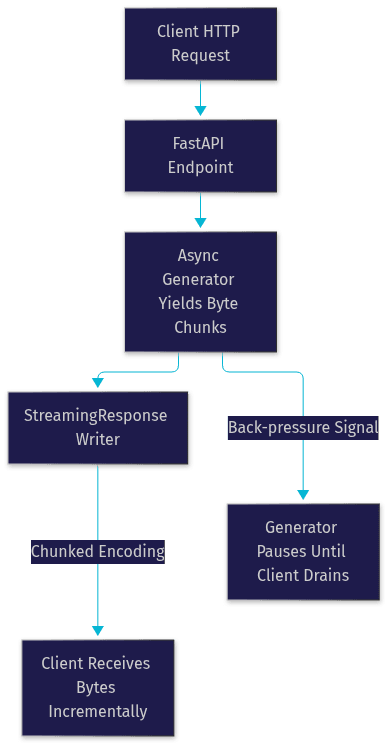
FastAPI streams bytes through its StreamingResponse construct, which accepts an iterator or asynchronous generator that yields chunks of bytes. Each yielded chunk is written to the outgoing HTTP response immediately, so the client receives data while the generator is still producing it.
The typical pattern works like this: your endpoint returns a StreamingResponse wrapping an async generator. The generator opens a file, a database cursor, or an upstream HTTP connection, reads a fixed number of bytes at a time, and yields each batch. FastAPI handles the HTTP plumbing, including chunked encoding, automatically. Because the generator is asynchronous, the event loop stays free while waiting on I/O, letting one worker serve many concurrent streams.
The pipeline looks like this:
Async versus sync generators
Use an async generator when the byte source involves awaitable I/O: reading from a network socket, querying a database, or proxying another service. Use a plain synchronous generator only for CPU-bound or trivially fast sources, and even then, FastAPI runs it in a threadpool, which costs more than the async path. For large payloads, async generators are the right default because they never block the event loop.
Returning raw bytes
When your endpoint produces a small, fully-computed binary payload, returning raw bytes directly is fine: FastAPI serializes them with an appropriate media type and a known Content-Length. Reserve streaming for payloads that are large, slow to produce, or unbounded. Streaming a tiny payload adds overhead without benefit.
Authentication and back-pressure
Protect streaming endpoints with token-based authentication, the same pattern VideoSDK uses for room access: the client presents a short-lived token issued server-side, and the endpoint validates it before the first byte flows. For a deeper example of token-based auth in real-time systems, see the VideoSDK authentication guide.
Back-pressure matters because a slow client can stall your generator. If the client stops reading, the response writer's buffer fills, and the generator should pause rather than produce unbounded output. FastAPI surfaces this through the async write path: when the client cannot keep up, writes await longer, naturally throttling production. Always also handle client disconnects, cancelling the generator and releasing file handles or database cursors when the consumer vanishes.
Streaming Bytes in Node.js
Node.js has exposed byte streams as a first-class primitive since its earliest versions. The Streams API defines readable streams (producers), writable streams (consumers), and transform streams (processors that sit in the middle). All three operate on chunks, which for binary data are Buffer objects holding raw bytes.
The idiomatic pattern is piping: you connect a readable stream, such as a file read stream or an incoming HTTP request, through a chain of transforms into a writable destination, such as an HTTP response or a storage write stream. Data flows automatically, with the stream machinery pausing the producer when the consumer falls behind. That pause-and-resume behavior is Node's built-in back-pressure, and it is the reason a piped transfer never exhausts memory even when the destination is much slower than the source.
The stream/consumers helper module simplifies the consuming side: instead of manually attaching event listeners, you can await an entire stream as a single buffer, iterate it chunk by chunk with an async loop, or collect it into a string. Iterating with an async loop is the modern way to process a stream when you want per-chunk logic without manual event wiring.
A byte-counting transform sits between source and destination, tallying bytes as they pass through:
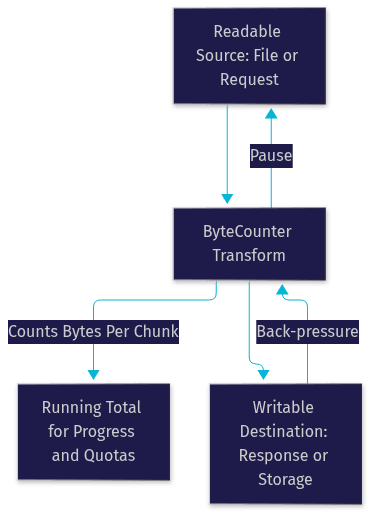
Because a transform receives each chunk before forwarding it, it can measure throughput, enforce quotas, and log progress without altering the data. If a quota is exceeded, the transform can destroy the pipeline, which propagates an error to both ends and closes the underlying file descriptor.
Counting Bytes on the Fly
Counting bytes as they stream through a pipeline is a small piece of engineering with outsized value. A byte counter is a transform or wrapper that increments a running total every time a chunk passes, exposing the count to your application in real time.
Three use cases dominate. Progress bars need byte counts to show users how much of a download or upload has completed, which requires knowing both the running total and, when available, the total size from Content-Length. Quota enforcement needs byte counts to cut off a client that exceeds its allowance, protecting your service from abuse. Logging and monitoring need byte counts to track throughput, detect anomalies, and bill accurately for data transferred.
Libraries such as the byte-counter package on npm provide a ready-made counting transform so you do not have to write your own. The principle is always the same: intercept chunks, add their length to a total, forward the chunk unchanged, and emit the count somewhere useful.
Durable Streams for Exactly-Once Byte Delivery
Standard byte streams are fast but best-effort. If a consumer crashes mid-stream, or the network drops a connection, bytes can be lost or, after a retry, delivered twice. For pipelines where every byte must arrive exactly once, such as financial event feeds or audit logs, you need a durable stream.
A durable-streams client works by persisting each produced chunk to durable storage before acknowledging it to the producer. The producer is idempotent: if it retries after a failure, the stream recognizes the duplicate and does not write the bytes twice. Consumers read from the durable log at their own pace, and each chunk is acknowledged only after the consumer has fully processed it. If a consumer fails, it resumes from its last acknowledged position, guaranteeing no byte is skipped and none is processed twice.
The trade-off is latency and cost: persisting every chunk adds milliseconds and storage overhead. Use durable streams when correctness beats speed, and plain byte streams when throughput and low latency matter more, as they do in real-time media, where a late chunk is worthless anyway.
Best Practices and Gotchas
Streaming bytes is simple in concept and subtle in practice. These are the mistakes that bite teams in production.
Choose async generators for large payloads
For anything large or slow, use asynchronous generators so I/O waits never block your worker. Synchronous iteration of a big file in an async framework stalls every other request on that worker.
Set proper Content-Length or use chunked encoding
If you know the total size, send Content-Length so clients can show progress and allocate correctly. If you do not, let the framework use chunked encoding rather than guessing. A wrong Content-Length is worse than none, because clients will truncate or error at the mismatch.
Handle back-pressure and client disconnects
Never assume the consumer keeps up. Pipe or await writes so the producer pauses when the destination is slow, and always listen for disconnect events to cancel production, close files, and release database cursors. Generating bytes for a departed client is pure waste.
Secure byte streams with TLS
Raw bytes crossing the public internet must travel inside TLS. This applies doubly to real-time media: WebRTC enforces encryption by design, and platforms like VideoSDK add end-to-end encryption for calls on top of the transport layer. For HTTP byte streams, serve everything over HTTPS and terminate TLS at your load balancer or application server.
Monitor byte counts for throttling
Track bytes per connection and bytes per client over time. Sudden spikes often signal a runaway loop or an abusive client, and per-client counters give you the data to throttle fairly before infrastructure suffers.
Choosing the Right Toolset
There is no single best tool for streaming bytes, only the best fit for your stack and requirements.
Choose FastAPI when your backend is Python and you want clean async streaming with automatic OpenAPI documentation. Its StreamingResponse pattern is concise, and it integrates naturally with the Python ecosystem's AI and data tooling, which matters when you are proxying model output.
Choose Node.js when your team lives in JavaScript or TypeScript. Its Streams API is mature, battle-tested at enormous scale, and the pipe-and-transform model makes middleware-style byte processing, including counting and throttling, straightforward.
Choose a durable-streams client when exactly-once delivery is non-negotiable. Neither FastAPI nor Node.js streams guarantee delivery on their own; durability is a property of the transport, not the language.
For real-time audio and video specifically, skip hand-rolling byte transport entirely. A purpose-built platform like VideoSDK handles media chunking, adaptive bitrate, encryption, and reconnection, exposing the result as simple audio and video tracks through SDKs for React, Node.js-adjacent web apps, Flutter, Python, and more. Its interactive live streaming mode shows the same principle this article covers, low-latency chunked delivery, applied to audience-scale media.
Definitions Glossary
Byte streaming: The practice of reading and writing binary data as a continuous sequence of small chunks rather than loading a complete payload into memory, keeping memory usage constant regardless of payload size.
Chunked transfer encoding: An HTTP mechanism where the server sends a response as a series of length-prefixed chunks, enabling streaming when the total payload size is unknown in advance.
Back-pressure: The signal flow whereby a slow consumer causes the producer to pause, preventing unbounded memory growth when the two sides of a stream operate at different speeds.
Transform stream: A stream-processing stage that receives chunks, optionally modifies or measures them, and forwards them onward, used for tasks like byte counting and filtering.
Durable stream: A streaming transport that persists every chunk before acknowledging it, enabling exactly-once byte delivery even across consumer crashes and retries.
Key Takeaways
- Streaming bytes keeps memory usage flat regardless of payload size, which is what lets modest servers handle multi-gigabyte transfers and endless telemetry feeds.
- HTTP supports byte streaming natively through chunked transfer encoding, and servers should use Content-Length only when the total size is genuinely known.
- FastAPI streams bytes through async generators feeding a StreamingResponse, while Node.js pipes readable streams through transforms into writable destinations with built-in back-pressure.
- Counting bytes on the fly powers progress bars, quota enforcement, and throughput monitoring, and a simple transform can do it without altering the data.
- Durable streams add exactly-once byte delivery guarantees at the cost of latency, making them the right choice for audit-critical pipelines but not latency-critical media.
- For real-time audio and video, purpose-built platforms like VideoSDK apply the same chunked-delivery principles with adaptive bitrate, encryption, and sub-300ms latency built in.
Conclusion
Streaming bytes efficiently is one of those fundamentals that quietly decides whether your service scales. Master the chunked-delivery model, pick async generators in FastAPI or piped transforms in Node.js, count bytes for visibility, and reach for durable streams when every byte must arrive exactly once. For real-time media workloads, explore how VideoSDK applies these same streaming principles to audio and video, and grab a free API key with credits at app.videosdk.live to try it yourself. What are you building that moves bytes? Drop a comment, I'd love to hear about your streaming use case.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ