


A TTS server is a self-hosted service that converts text into spoken audio through an API, giving you full control over latency, cost, privacy, and voice quality. Unlike cloud TTS APIs, a self-hosted text-to-speech server runs on your own hardware or containers, so audio data never leaves your infrastructure. This guide covers the architecture, open-source options, deployment strategies, and performance tuning you need to run one in production, and how it connects to real-time platforms like VideoSDK for voice agents and live apps.
Introduction to the TTS Server
Every voice-enabled application, from a phone assistant to an AI voice agent, depends on one core capability: turning text into natural-sounding speech, fast. For years, that meant calling a cloud TTS API and paying per character, with every sentence of user data routed through a third party. That model is now being challenged.
A TTS server is a dedicated service that hosts text-to-speech models behind an API endpoint you control. Instead of sending text to an external provider, your application sends requests to your own server, which runs the inference locally and returns audio. The shift matters for three reasons: cost predictability at scale, data residency for regulated industries, and latency control for real-time conversations.
The bigger trend in 2026 is the move from cloud-only APIs toward on-device and self-hosted solutions. Open-source models have closed much of the quality gap with commercial offerings, and inference runtimes like ONNX Runtime and CoreML make it practical to run them on everything from a Kubernetes node to a laptop to an Android phone. Whether you are building a voice assistant, an e-learning platform, or an AI agent that talks in real time, running your own TTS server is now a serious engineering choice, not just a cost hack.
Core Architecture of a TTS Server
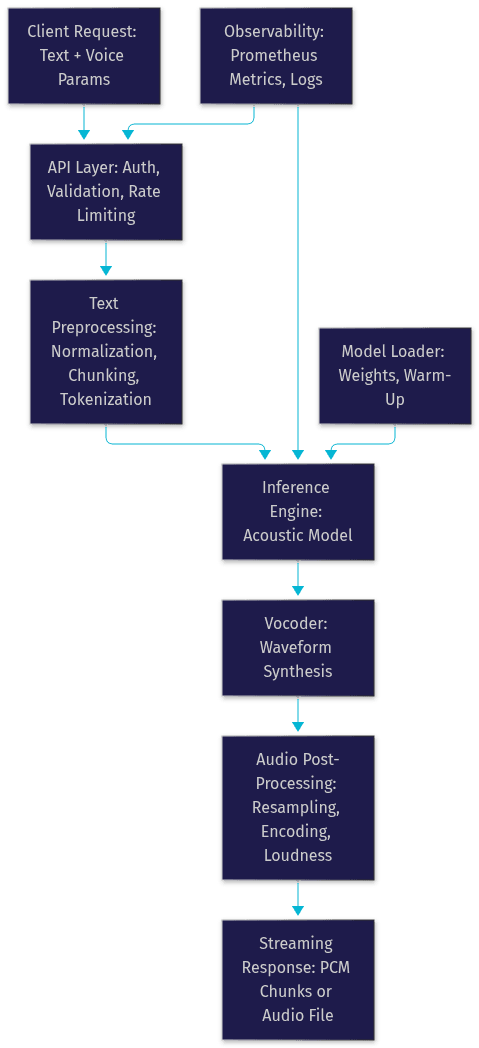
Every well-designed TTS server separates concerns into four components so each can be scaled and debugged independently. Understanding this architecture is the foundation for every deployment decision that follows.
Components of a Typical TTS Server
The model loader handles model discovery, weight loading, and warm-up. It reads model files from disk or a model registry, initializes the inference runtime, and pre-loads weights into memory so the first request does not pay a cold-start penalty of several seconds.
The inference engine is the heart of the server. It executes the neural TTS model, which typically involves two stages: a text-to-spectrogram or token-generation stage, and a vocoder stage that converts intermediate representations into raw audio samples. The engine may target CPU, CUDA GPUs, Apple Silicon via CoreML, or ONNX Runtime as a portable backend.
The API layer exposes the service to clients. Most modern TTS servers offer an OpenAI-compatible HTTP endpoint, plus WebSocket or server-sent-event streaming for real-time playback. This layer also handles authentication, request validation, and rate limiting.
The observability module tracks request latency, queue depth, GPU utilization, and error rates, usually exported as Prometheus metrics. Without it, you are tuning blind.
Data Flow from Request to Audio Output
A request arrives at the API layer, where it is authenticated and validated. Text preprocessing then normalizes the input: expanding numbers and abbreviations, splitting long text into sentence-sized chunks, and converting characters into the phoneme or token representation the model expects.
The inference engine runs the model on those tokens, producing intermediate acoustic features, then the vocoder synthesizes the final waveform. Audio post-processing applies sample-rate conversion, format encoding (such as WAV, MP3, or raw PCM), and optional loudness normalization. Finally, the response is streamed back to the client, ideally chunk by chunk so playback can begin before the full clip is generated.
Open-Source TTS Server Options
The open-source TTS server ecosystem has matured rapidly. Three projects illustrate the range of approaches, from portable CPU inference to GPU-heavy multi-model serving.
Supertonic-Server
Supertonic-server targets portability above all. It runs models through ONNX Runtime, which means the same server can execute on CPU, NVIDIA GPUs via CUDA, or Apple Silicon via CoreML without code changes. Its standout feature is an OpenAI-compatible API, so any client already written against the OpenAI TTS endpoint can switch to your self-hosted server by changing a base URL. That makes it one of the easiest migration paths for teams moving off cloud TTS.
Pocket-TTS-OpenAPI
Pocket-tts-openapi takes the opposite approach: minimal footprint. It is a lightweight Python TTS server designed to run on small machines and even single-board computers, with WebSocket streaming for low-latency playback and compatibility with XTTS-family models, including voice cloning. If you need a TTS server that boots in seconds on modest hardware and streams audio as it is generated, this is the category to evaluate.
vLLM-Omni TTS Server
The vllm-omni style of server borrows the serving philosophy of vLLM, the popular LLM inference engine: multi-model support, continuous batching, and GPU acceleration as first-class concerns. These servers stream raw PCM audio, handle concurrent requests efficiently, and are built for teams whose TTS workload looks like their LLM workload: bursty, high-volume, and GPU-bound.
Android-Focused TTS Server
On the mobile side, projects like tts-server-android turn an Android device itself into a TTS server. The app exposes a local HTTP endpoint that other apps or system-level TTS engines can call, effectively letting you replace the device's default speech engine with a modern neural model. This is the purest form of on-device TTS: zero network round trips, zero data leaving the phone, and latency measured in tens of milliseconds. It is especially relevant for accessibility tools and offline voice assistants.
Deployment Strategies for a TTS Server
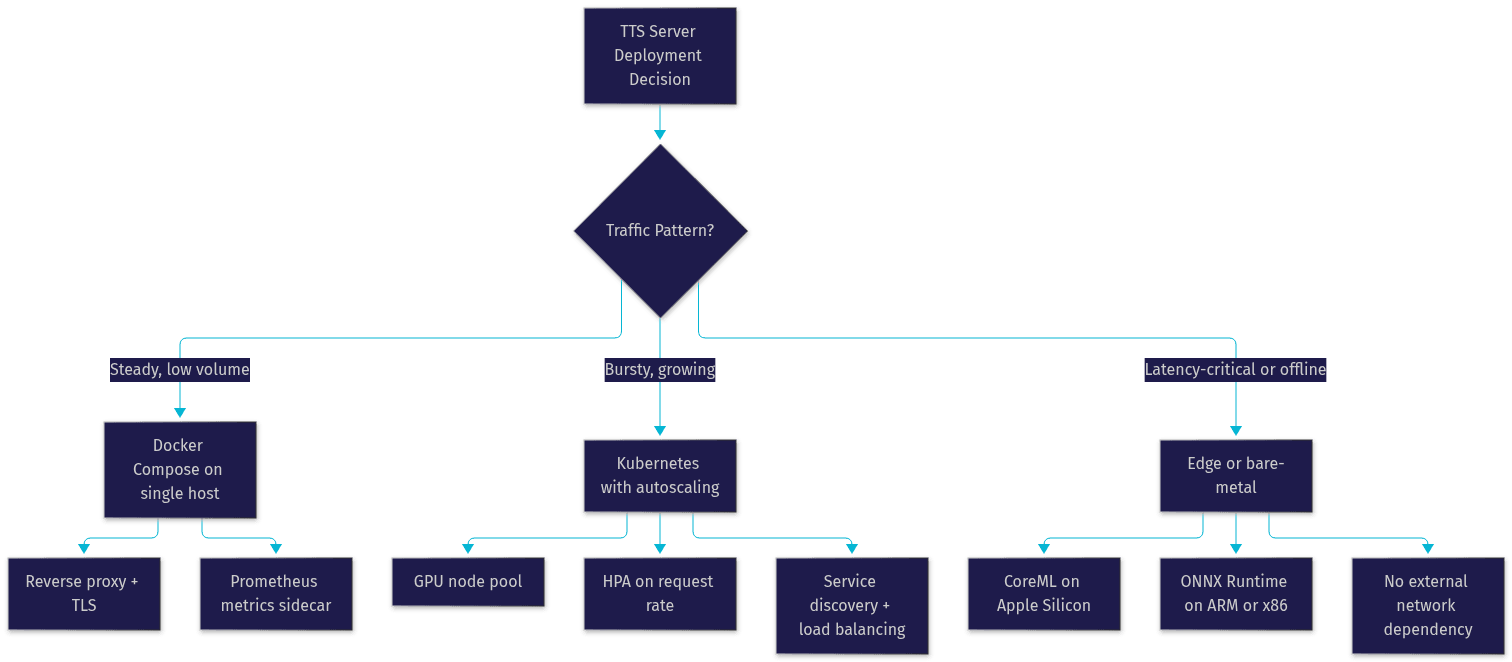
Choosing where your TTS server runs is as important as choosing which one. The three dominant strategies each fit a different stage of growth.
Single-Host Containerized Deployment
Containerization is the default starting point. Packaging the TTS server as a container guarantees that model weights, runtime dependencies, and system libraries travel together, eliminating the classic "works on my machine" failure mode. A single-host container stack lets you run the TTS server alongside its supporting services, such as a reverse proxy for TLS termination and a metrics collector, as one reproducible unit that can be lifted from a laptop to a production machine without surprises.
For most teams, a single host running two or three replicated TTS containers behind a load balancer handles surprising traffic volume. GPU access is handled by exposing the host's accelerator devices to the container, and model weights are typically attached as persistent storage so restarts do not re-download gigabytes of data.
Kubernetes and Cloud-Native
Move to Kubernetes when you need auto-scaling, self-healing, and service discovery. A TTS server deployment on Kubernetes typically runs as a stateless workload with a horizontal pod autoscaler keyed on request rate or GPU utilization. Because inference is CPU- or GPU-bound rather than memory-stateful, pods can be replaced freely.
The main Kubernetes-specific considerations are GPU scheduling (requesting GPU resources per pod and tolerating node pools dedicated to inference), graceful shutdown so in-flight audio streams finish before a pod terminates, and liveness probes that distinguish a cold model load from a hung process.
Bare-Metal and Edge Deployment
Edge deployment is where a self-hosted TTS server shines hardest. Running inference on hardware physically close to the user, or on the user's own device, removes network round trips entirely. For real-time voice agents, a round trip to a distant cloud region can add 100 to 300 milliseconds before a single audio sample is generated; an edge server on the local network can cut that to near zero.
Hardware considerations matter here. Apple Silicon with CoreML delivers excellent latency-per-watt for on-prem Mac clusters. ARM boards work for lightweight models. For industrial or offline scenarios, a bare-metal server with no internet dependency is often a compliance requirement, not a preference.
Performance Tuning and Scalability
A TTS server is only as good as its worst-case latency. Tuning falls into three buckets: the model, the runtime, and the pipeline.
Model-level tuning starts with quantization. Converting model weights from full precision to 8-bit or 4-bit representations can cut memory usage dramatically and speed up CPU inference, at a small and often imperceptible cost to voice quality. Always benchmark quality after quantizing; some voices degrade more than others.
Runtime-level tuning includes batch inference, where multiple concurrent requests share a single model pass, and warm-up strategies, where the server generates a silent dummy request at startup to force JIT compilation and memory allocation before real traffic arrives. Skipping warm-up is a classic mistake: the first production request takes ten times longer than the hundredth.
Hardware trade-offs are straightforward. GPUs win on throughput and concurrent streams but add cost and operational complexity. Modern CPUs with ONNX Runtime are competitive for single-stream, short-utterance workloads. CoreML on Apple Silicon is the sweet spot for on-prem deployments where power and noise matter.
Real-time streaming is the difference between a TTS server that feels conversational and one that feels sluggish. Streaming PCM over WebSockets means the client starts playing audio after the first few chunks rather than waiting for the entire clip. For conversational AI, target first-audio latency under 200 milliseconds end to end.
Observability ties it together. Export Prometheus metrics for request duration, time-to-first-audio-byte, queue depth, and hardware utilization, and put them in a dashboard before you tune anything. Latency problems that are invisible in averages become obvious in percentile graphs.
Security, Privacy, and Licensing
The strongest argument for a self-hosted TTS server is data residency. Every sentence your application speaks stays on your infrastructure, which simplifies GDPR, HIPAA, and enterprise data-processing compliance. No text, no audio, and no voice profiles are transmitted to third parties.
Licensing deserves careful attention. Server code is often MIT or Apache licensed, but the underlying TTS models frequently carry OpenRAIL-M or similar responsible-use licenses that restrict certain commercial applications, particularly voice cloning of real people. Read the model license separately from the server license; they are not the same thing.
On the API side, treat your TTS server like any public-facing service: require token or key-based authentication, put it behind TLS, and apply rate limiting per client. An unauthenticated TTS endpoint is an open door to GPU-burning abuse.
Practical Use Cases for a TTS Server
Voice assistants and AI agents are the headline use case. A self-hosted TTS server pairs naturally with frameworks like Pipecat for building conversational pipelines, and with LiveKit or VideoSDK rooms for real-time transport. In a VideoSDK-based AI voice agent, the agent's speech pipeline sends generated text to your TTS server, and the resulting audio stream is published into the room as a participant track, so users hear the agent in real time alongside human participants. VideoSDK's AI Agents documentation covers this pipeline pattern in depth.
Other proven use cases include e-learning platforms generating narration at scale without per-character fees, accessibility tools that need offline speech synthesis, and games producing dynamic character dialogue that cannot be pre-recorded. Because most modern servers expose an OpenAI-compatible TTS API, existing clients built against the OpenAI SDK, Pipecat, or a custom Python app can often migrate by changing one endpoint URL.
Choosing the Right TTS Server for Your Project
Pick by hardware first. GPU nodes point toward vllm-style multi-model servers; Apple Silicon or CPU-only hosts point toward ONNX Runtime or CoreML-based servers like supertonic-server; Android targets call for a mobile-first project. Second, check language and voice coverage, including voice cloning support if you need it. Third, verify the license of both server and model against your commercial use case. Fourth, weigh community activity: recent commits, responsive issue trackers, and published benchmarks are the best predictors of a project you can depend on in production.
For teams already building real-time voice applications, the pragmatic path is to start with a containerized deployment of an OpenAI-compatible server, benchmark time-to-first-audio on your actual hardware, and only then decide whether Kubernetes-scale or edge deployment is warranted.
Definitions Glossary
TTS Server: A self-hosted service that runs text-to-speech models behind an API, converting text to audio on infrastructure you control. It typically exposes HTTP and WebSocket endpoints and can run on CPU, GPU, or mobile hardware.
OpenAI-Compatible TTS API: An API endpoint that mirrors the request and response format of OpenAI's text-to-speech service, allowing existing clients to switch to a self-hosted server by changing only the base URL.
ONNX Runtime: A cross-platform inference engine that executes neural network models in the ONNX format on CPUs, GPUs, and accelerators like CoreML, enabling portable TTS server deployments.
Streaming PCM: A delivery pattern where raw audio samples are sent to the client in chunks as they are generated, letting playback begin before the full audio clip exists.
Time-to-First-Audio: The latency metric measuring the time from request arrival to the first playable audio chunk, the key number for conversational TTS performance.
Voice Cloning: A TTS capability that generates speech in a specific person's voice from a short reference sample, subject to licensing and consent restrictions under licenses like OpenRAIL-M.
Key Takeaways
- A self-hosted TTS server gives you control over cost, latency, and data residency that cloud TTS APIs cannot match, and open-source model quality has made it a production-viable choice in 2026.
- The core architecture, model loader, inference engine, API layer, and observability module, should be evaluated as separate components so each can be scaled and tuned independently.
- Open-source options span the full spectrum: ONNX-based portable servers, lightweight Python servers with WebSocket streaming, GPU-oriented multi-model servers, and Android on-device servers.
- Deployment should follow your growth stage: a containerized single-host setup for steady workloads, an orchestrated cluster with autoscaling for bursty traffic, and edge or bare-metal hardware for latency-critical and offline scenarios.
- Performance is won through quantization, warm-up, batch inference, and streaming delivery, with time-to-first-audio under 200 milliseconds as the practical target for conversational applications.
Conclusion
A TTS server is no longer a niche engineering project; it is a mainstream building block for voice assistants, AI agents, e-learning, and accessibility tools. The combination of mature open-source servers, portable runtimes like ONNX Runtime and CoreML, and standard deployment tooling means any team can own its speech synthesis stack end to end. Start small: run an OpenAI-compatible server in a container, measure time-to-first-audio on your real hardware, and scale to Kubernetes or edge only when the numbers demand it. If you are building real-time voice experiences, pair your TTS server with a transport layer like VideoSDK's real-time communication SDKs so generated speech reaches users with sub-second latency. Create a free account at app.videosdk.live to get started. What are you building with a self-hosted TTS server? Drop a comment, I'd love to hear about your use case.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ