


Stream translation is the real-time conversion of a continuous audio or speech stream from one language into another while the speaker is still talking, typically delivering translated text or synthesized speech within one to three seconds. VideoSDK supports stream translation scenarios by combining its low-latency WebRTC audio streaming with AI translation pipelines, letting you pipe live audio into a translation engine and return translated output to participants in real time. This guide covers the architecture, the major providers, and the implementation steps most tutorials skip.
Introduction to Stream Translation
A live webinar host speaks Portuguese, and an audience in Tokyo reads Japanese captions two seconds later. That gap between speech and translated output is the entire product experience, and it is measured in milliseconds.
Stream translation is the practice of feeding a continuous audio stream into a translation service and receiving translated output incrementally, rather than waiting for a recording to finish. It sits at the intersection of real-time communication and AI: the transport layer comes from the WebRTC and WebSocket world, and the intelligence comes from streaming speech recognition and large language models that can translate token by token as audio arrives.
The reason developers care now is latency. Traditional transcription pipelines batch audio into chunks, translate the finished transcript, and return results tens of seconds later. Modern streaming translation APIs return partial hypotheses continuously, so a viewer sees a caption evolve in near real time. As of 2026, leading providers deliver first translated tokens in well under a second on good connections, which finally makes live multilingual events, support lines, and voice agents practical.
How Stream Translation Works
Stream translation works by capturing raw audio, transporting it to a translation engine as a continuous stream, and incrementally emitting translated output as the engine processes each incoming segment.
The end-to-end flow has four stages. First, the client captures audio from a microphone or an existing media stream, typically as uncompressed PCM samples at a fixed sample rate. Second, the transport layer, usually a WebSocket binary connection or a WebRTC media track, sends those samples in small chunks, often 100 milliseconds or less, to the provider. Third, the translation engine runs streaming speech recognition on the incoming audio, detects or is told the source language, and passes recognized text through a translation model. Fourth, the provider streams back events: partial transcripts, translated text deltas, and optionally synthesized speech in the target language.
The critical design property is that nothing waits. Recognition, translation, and output emission all happen on partial audio. A sentence half-spoken already produces a partial translation that gets revised as more audio arrives. This is what separates stream translation from batch translation, and it is why latency budgets, chunk sizes, and transport choice dominate the engineering decisions.
Core Architecture of Stream Translation
A stream translation system has four core components: an audio source, a transport channel, a translation engine, and an output renderer. The audio source can be a microphone, a WebRTC participant's track, or a telephony trunk. The transport moves raw audio frames to the engine. The engine performs streaming speech recognition and translation. The renderer displays captions, plays synthesized speech, or forwards translated text into chat.
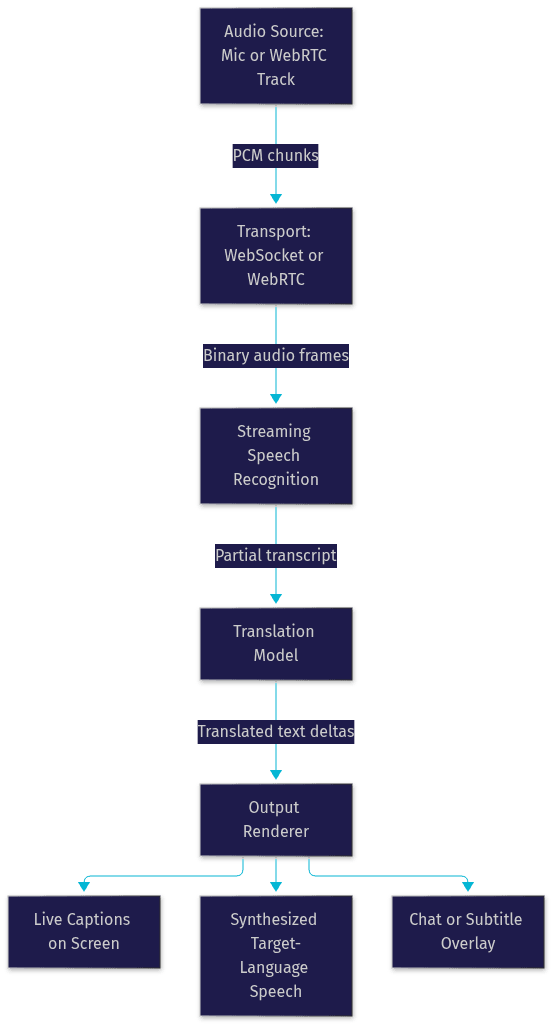
When you embed this inside a VideoSDK room, the architecture extends naturally: each participant's audio track can be forked into the translation pipeline while the original audio continues flowing to other participants, so listeners choose which language they receive.
Audio Capture and Transport Options
The two dominant transports are WebRTC media tracks and WebSocket binary frames, and they suit different environments.
WebRTC is the right choice when the audio already lives in a real-time session, such as a video call or interactive live stream. It handles jitter buffering, packet-loss concealment, and encryption automatically, and it works through restrictive networks via TURN relay fallback. The trade-off is that you typically process the received track on the server side or re-encode it before sending it to a translation provider.
WebSocket binary frames are the right choice when the client talks directly to a translation API. You control chunk size, timing, and backpressure explicitly, and most provider SDKs expect this shape. The trade-off is that you inherit responsibility for reconnection, and corporate firewalls occasionally interfere with long-lived sockets.
A common production pattern is hybrid: WebRTC carries audio between participants, and a server-side worker opens a WebSocket to the translation provider, forwarding decoded audio and returning translated events back into the room via pub/sub messaging.
Language Detection and BCP-47 Tags
Language tagging in stream translation is done with BCP-47 codes, the standard format like en-US or pt-BR that identifies both language and regional variant.
Most providers accept an explicit source and target language pair per session, and several also offer automatic language detection on the incoming audio. Explicit tagging is faster and more accurate because the recognizer loads the right acoustic model immediately. Auto-detection is useful for open-ended support lines where you cannot know the caller's language in advance, but it adds a short detection window at stream start and can misfire on short utterances or code-switching speakers. A practical rule: tag the language when you can, and reserve auto-detection for genuinely unknown-language scenarios.
Major Providers and Their Stream Translation APIs
Choosing a streaming translation provider in 2026 means comparing latency, language coverage, output modes, and pricing across a handful of well-defined services.
The providers below each expose a real-time, streaming interface rather than a batch API, which is the baseline requirement for stream translation. Their differences show up in transport style, event granularity, and how they handle speech-to-speech output versus text-only output.
OpenAI Realtime Translation
OpenAI's realtime models support live speech-to-speech translation through a single persistent session that accepts audio in and returns translated audio or text out. The realtime interface handles the full loop, recognition, translation, and synthesis, in one model, which simplifies your pipeline considerably. Language coverage spans major languages, and pricing is usage-based on audio minutes and tokens. The main consideration is cost at scale, since a single-model pipeline bills for every stage of the loop.
Google Gemini Live Translation
Google's Gemini Live API offers multimodal real-time translation, accepting audio and optionally video, and returning translated speech or text with low claimed latency. Configuration is session-based: you specify source and target languages using BCP-47 tags, and the model streams partial results as they stabilize. Its strength is multimodality and tight integration with Google's speech stack, which helps when your source audio is noisy or accented.
Soniox Real-Time Translation
Soniox focuses on streaming speech recognition with translation built on top, delivered over a WebSocket interface with token-based authentication. Its distinguishing feature is token-by-token streaming: translated text arrives as individual deltas you can render immediately, giving some of the fastest visible-caption latency available. It also supports a two-way mode where both sides of a conversation are translated in a single session, which maps cleanly onto bilingual support calls.
Other options worth evaluating include Bland for telephony-centric translation and UApi-style aggregators that normalize multiple providers behind one interface. The right choice depends less on headline accuracy and more on which output mode, text deltas or synthesized speech, matches your product.
Implementing Stream Translation in Your Application
Implementing stream translation involves four phases: authentication, audio preparation, stream session setup, and event handling. Each phase has failure modes that are cheap to avoid early and expensive to debug in production.
Setting Up Authentication and Tokens
Every streaming translation provider uses token-based authentication, and the pattern is consistent: generate a short-lived token server-side using your API key and secret, then pass it to the client or worker that opens the stream.
Never embed provider API secrets in frontend code. Run a small token endpoint on your server that mints scoped, expiring tokens on demand. This gives you revocation, per-session limits, and audit trails. The same discipline applies if you build on VideoSDK: VideoSDK meeting tokens are generated server-side with your API key and secret, as described in the VideoSDK authentication and token guide. A shared pattern is one backend that mints both the room token and the provider token, so a client joins the room and opens the translation stream in a single authenticated handshake.
Choosing Audio Formats and Sample Rates
Providers expect raw, uncompressed audio, most commonly PCM-16 at 16 kHz, with some accepting alternative encodings such as µ-law for telephony sources.
Sample rate choice is a latency-versus-fidelity trade-off. Sixteen kilohertz is the speech recognition standard: it captures the frequencies that matter for speech, keeps chunk sizes small, and minimizes transport overhead. Higher rates like 48 kHz improve music and ambient fidelity but double or triple your bandwidth for negligible recognition gain. If your source is a phone line, µ-law at 8 kHz is native and avoids a lossy transcoding step. The rule: match the provider's expected format exactly, and transcode once, server-side, rather than letting the client negotiate formats ad hoc.
Managing Stream Parts and Event Handling
A translation stream emits several distinct event types, and handling each correctly is what makes the experience feel instant.
Audio events carry synthesized target-language speech when the provider supports speech-to-speech output. You should buffer these into a jitter-tolerant playback queue rather than playing each chunk as it arrives, or output will stutter on any network hiccup.
Text-delta events carry incremental fragments of the translated transcript. The standard rendering approach is to append deltas into a live caption line, replacing the whole line whenever a revised partial arrives. This gives viewers the familiar experience of a caption that grows and corrects itself.
Final events mark a completed utterance with its settled translation. This is your signal to commit the text to a transcript log, persist it for post-call analytics, or hand it to downstream systems. A common bug is treating partials as final and committing unstable text; always key persistence on the final event.
In a VideoSDK room, the cleanest pattern is a server-side worker that joins as a participant, receives the audio tracks, forwards them to the provider, and publishes translated text back through the room's pub/sub messaging, so every client renders captions without each one opening its own provider session. The VideoSDK AI agents introduction describes this worker architecture in detail.
Best Practices for Low-Latency and Quality
Keeping stream translation fast and accurate is mostly about controlling chunk size, transport health, and how gracefully you degrade when things go wrong.
Network Optimization and Adaptive Bitrate
Latency in stream translation is dominated by network conditions, so treat the transport as a first-class engineering concern.
Use small, consistent audio chunks, around 100 milliseconds, so the engine always has fresh audio to work with. Deploy TURN relay fallback for WebRTC paths so restrictive corporate networks do not silently kill your stream. Monitor round-trip time and packet loss continuously, and when bandwidth degrades, drop to a lower-bitrate audio encoding before you drop quality elsewhere; recognition accuracy on clean 16 kHz speech degrades far less than users notice when playback stutters. VideoSDK's network-adaptive streaming applies the same principle to media sessions, adjusting bitrate and resolution automatically as conditions change, which you can read about in the VideoSDK video calling docs.
Handling Errors and Reconnection
Long-lived streams fail, and your handling determines whether users notice.
The common failure classes are authentication expiry, transient socket drops, and provider rate limits. For token expiry, refresh tokens before they lapse rather than after the stream errors. For socket drops, implement exponential backoff reconnection and, critically, buffer audio locally during the gap so the reconnected stream resumes without losing speech. For rate limits, queue or downsample rather than dropping the stream entirely. Graceful degradation matters most: if translation fails mid-event, fall back to showing the original-language transcript with a status indicator, never a blank screen.
Security and Privacy Considerations
Stream translation carries live personal conversations, so treat it as sensitive data. Use end-to-end encrypted transport wherever the provider supports it, keep tokens short-lived and scoped, and confirm provider data residency and retention policies against your compliance requirements, particularly for healthcare and legal use cases where translated speech is regulated content.
Use Cases and Real-World Examples
Stream translation is already shipping in three broad product categories, and each stresses a different part of the pipeline.
Live Events and Webinars
For live events and webinars, stream translation delivers real-time captions and multilingual audio channels to global audiences. A conference platform built on VideoSDK's interactive live streaming can fork the speaker's audio into a translation worker and publish per-language caption overlays, letting each viewer select their language while the original audio continues uninterrupted. The latency budget here is strict: captions lagging more than a few seconds behind the speaker break the viewing experience, which is why token-by-token streaming providers shine in this category.
Multilingual Customer Support
In multilingual customer support, stream translation lets a support agent speak one language while the customer hears another. The pipeline runs both directions: the agent's speech is translated for the customer, and the customer's speech is translated back. Two-way translation modes, like Soniox's single-session bidirectional mode, fit this exactly. The practical win is staffing: one support team covers many languages without hiring native speakers for each market, and the full translated transcript becomes a record for quality review.
Interactive Voice Agents
Interactive voice agents combine stream translation with AI agents for global reach. An AI voice agent built on VideoSDK's agent pipeline can recognize a caller's language, respond in it, and hand translated context to business systems, all within a single low-latency session. The VideoSDK AI agents documentation covers the agent worker architecture, and the Conversational Graph adds deterministic flow control for structured multilingual interactions like appointment booking, where every step must happen in order regardless of language.
Future Trends in Stream Translation
Stream translation is moving quickly, and two trends will reshape the stack over the next few years.
Multimodal Translation and AI Advances
Multimodal translation pipelines are beginning to combine audio, video, and text in a single model, so a provider can read a shared screen, a speaker's gestures, or on-screen slides alongside speech to improve translation context. Real-time multimodal models like Google's Gemini Live already accept mixed input, and the trajectory is toward translation engines that understand the full meeting context rather than audio in isolation. For developers, this means designing capture pipelines that can forward more than audio when the provider can use it.
Edge Computing and On-Device Models
Edge translation moves inference closer to the user, running smaller speech translation models on-device or at regional edge nodes to cut the round-trip entirely. For latency-critical uses like face-to-face conversation translation, on-device models can beat cloud round-trips simply by removing network transit. The trade-off today is language coverage and accuracy, but the direction is clear: hybrid architectures where cloud models handle breadth and edge models handle speed.
Definitions Glossary
Stream Translation: The real-time conversion of a continuous audio stream into translated text or speech while the speaker is still talking, delivering output incrementally rather than after the audio completes.
BCP-47 Language Tag: The standard code format, such as en-US or pt-BR, used to identify a language and regional variant when configuring translation sessions with providers.
PCM-16: A common uncompressed audio format, 16-bit samples at 16 kHz, expected by most streaming speech recognition and translation APIs for input audio.
Text Delta: An incremental fragment of translated text emitted by a streaming provider, appended to a live caption line as it arrives.
TURN Server: A relay server that keeps WebRTC media flowing through restrictive networks and firewalls when direct peer connections fail.
Agent Worker: The server-side Python process in VideoSDK's AI agent architecture that manages a session inside a VideoSDK room, and which can host a stream translation pipeline.
Key Takeaways
- Stream translation delivers translated output incrementally on partial audio, which is what makes live multilingual events, support lines, and voice agents feel instantaneous.
- Transport choice matters: WebRTC suits audio already inside real-time sessions, while WebSocket binary frames suit direct client-to-provider streaming, and hybrid server-side workers are the common production pattern.
- Always generate provider and VideoSDK tokens server-side, keep them short-lived and scoped, and never expose API secrets in frontend code.
- Handle stream events by their type: render text deltas as evolving captions, buffer audio events into a jitter-tolerant queue, and persist only final events.
- VideoSDK's low-latency WebRTC rooms, network-adaptive streaming, and agent worker architecture provide the real-time foundation that stream translation pipelines plug into.
Conclusion
Stream translation has crossed the threshold from demo to product: providers now return translated tokens in under a second, and the transport, authentication, and event-handling patterns are stable enough to build on. The engineering work is in the details this guide covered, small audio chunks, server-side token minting, correct handling of partial versus final events, and reconnection logic that buffers rather than drops. Start by forking one audio track from a VideoSDK room into a translation provider and rendering live captions, then extend into speech-to-speech output and bidirectional support flows. You can get started with a free account at app.videosdk.live and explore the code samples for real-time audio pipelines. What are you building with stream translation? Drop a comment, I'd love to hear which languages and use cases you're targeting.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ