


LLM reasoning is the ability of a large language model to work through multi-step problems, draw valid conclusions from evidence, and explain the path to an answer rather than just predicting the next token. Developers improve it through techniques like chain-of-thought prompting, tool augmentation, and reasoning-centric architectures. This guide covers reasoning types, benchmarks, limitations, and implementation strategies you can apply in production applications today.
Large language models have moved from autocomplete curiosities to systems that draft legal arguments, debug production code, and orchestrate multi-step workflows. What changed is not just scale but reasoning: the ability to decompose a problem, hold intermediate conclusions, and arrive at an answer that survives scrutiny. For developers, this shift matters because a model that reasons well can be trusted with decisions, while one that merely pattern-matches cannot.
The catch is that LLM reasoning is uneven. The same model that solves a graduate-level math problem can fail a trivial logic puzzle if the phrasing is unusual. Understanding why that happens, how to measure it, and how to engineer around it is now a core skill for anyone building AI-powered products. This guide walks through the full picture: what reasoning actually is in an LLM, how to evaluate it, where it breaks, and the prompting, tooling, and architectural strategies that make it production-grade.
What is LLM Reasoning?
LLM reasoning is defined as the process by which a large language model derives new conclusions from given information through intermediate steps, rather than retrieving a memorized answer. It works by generating a sequence of intermediate tokens, often called a reasoning trace or chain of thought, that connects the input to the final output. Because the model attends to its own generated context, each intermediate step conditions the next one, effectively giving the model a working memory for the problem at hand.
The distinction matters. A model that answers "Paris" when asked for the capital of France is retrieving knowledge. A model that works out whether a shipping discount applies given a tangled set of conditional rules is reasoning. In practice, most real applications need both, and the failure modes developers care about, hallucination and inconsistent logic, come from the reasoning side.
VideoSDK's AI ecosystem is a good example of where this lands in production: an AI voice agent holding a structured conversation must reason about what the user said, what the next step in the flow should be, and what data still needs collecting, all in real time.
Types of Reasoning in LLMs
Researchers generally break LLM reasoning into a few recognizable forms. Deductive reasoning applies general rules to specific cases, such as concluding a user is ineligible for a loan because their income fails a stated threshold. Inductive reasoning generalizes from examples, which is how models learn patterns from few-shot prompts. Abductive reasoning infers the most likely explanation for an observation, the engine behind diagnostic and troubleshooting agents. Causal reasoning asks what happens if an intervention changes something, and counterfactual reasoning asks what would have happened instead. Most real-world tasks are mixed-form: a customer support agent might abduce the cause of a complaint, deduce the applicable policy, and reason counterfactually about whether a refund would have been owed under different circumstances.
Why LLM Reasoning Matters for Developers
Every application that delegates judgment to a model depends on reasoning quality. In decision support, a model must weigh conflicting evidence and justify a recommendation. In code generation, it must trace data flow and anticipate edge cases, which is pure deductive work. In data analysis, it must form hypotheses, test them against the data, and avoid overclaiming. Autonomous agents push this furthest: an agent that books meetings, triages tickets, or handles outbound calls must chain dozens of reasoning steps, and a single weak link corrupts everything downstream.
The economics are also shifting. As raw text generation becomes commoditized, reasoning capability is becoming the differentiator between models and between products. A retrieval system that answers questions is table stakes; one that can reason over retrieved evidence, spot contradictions, and flag what it does not know commands premium trust. Developers who understand reasoning evaluation and improvement can pick the right model for each task instead of overpaying for capability they do not need or underpaying into failure.
Evaluating LLM Reasoning Capabilities
Evaluating LLM reasoning requires more than checking whether the final answer matches a gold label. A sound methodology tests the model on unseen problems, varies surface phrasing to separate genuine logic from memorization, and inspects the reasoning trace itself, not just the conclusion. Two models can produce the same correct answer while one reached it through valid steps and the other through a lucky guess, and only trace-level evaluation distinguishes them.
A practical evaluation pipeline has three layers. First, run standardized benchmarks for a comparable baseline. Second, build domain-specific test sets that reflect your actual workload, including adversarial cases where the correct behavior is to say "I don't know." Third, instrument trace-level review, where either human evaluators or a judge model score the intermediate steps for validity. Teams that skip the third layer consistently ship models that look good in demos and fail in production.
Common Benchmarks and Datasets
Several benchmarks dominate reasoning evaluation as of 2026. MMLU and its harder variants test broad knowledge applied across academic domains. BIG-Bench aggregates diverse reasoning tasks designed to exceed pure memorization. ARC focuses on grade-school science questions that require combining facts rather than recalling them. GSM8K and its successors test multi-step mathematical reasoning. GPQA and frontier math benchmarks stress expert-level problem solving. The solver-learner style tests evaluate whether a model can induce an underlying function or rule from examples and apply it to new inputs, which isolates inductive reasoning from knowledge recall. No single benchmark is sufficient; the right practice is a portfolio matched to your use case.
Metrics Beyond Accuracy
Accuracy alone hides most of what matters in reasoning performance. Researchers now evaluate along several axes. Correctness asks whether the final answer is right. Rigor asks whether every intermediate step is valid, not just the conclusion. Self-awareness asks whether the model knows when it is uncertain or lacks information. Active reasoning measures whether the model seeks missing information instead of guessing. Oriented reasoning checks whether the model stays on task and follows constraints. No-hallucination metrics measure how often the model fabricates facts, steps, or citations. A model that scores high on correctness but low on self-awareness is dangerous in production because it will confidently deliver wrong answers.
Challenges and Limitations of LLM Reasoning
LLM reasoning has well-documented failure modes that every developer should design around. Hallucination is the most visible: the model generates plausible-sounding but false premises or steps, and because the trace reads fluently, the error is easy to miss. Counterfactual failures are subtler: models often struggle when asked to hold a hypothetical world steady and reason about what would change, sometimes drifting back to factual reality mid-derivation.
Knowledge bias is another structural limit. A model trained heavily on one domain's patterns will import those priors into unrelated problems, producing confident but biased reasoning. Token limits constrain reasoning depth: a problem requiring thirty careful steps can exhaust the model's effective working memory, causing it to shortcut or lose earlier conclusions. Finally, reasoning is brittle to surface form. Reordering clauses, adding irrelevant details, or negating a premise can flip a model from correct to incorrect, a phenomenon sometimes called reasoning inconsistency. None of these limits are fully solved, which is why the strategies in the next section exist.
Strategies to Improve LLM Reasoning
Improving LLM reasoning in an application is an engineering problem with four main levers: prompting, tool augmentation, fine-tuning, and reinforcement learning. Most production systems combine several. The order matters: exhaust prompting and tooling before investing in fine-tuning, because they are cheaper, faster to iterate, and easier to swap as models improve.
Prompt Engineering Techniques
Chain-of-thought prompting is the foundational technique: instruct the model to work through a problem step by step before answering, which measurably improves multi-step accuracy because it forces the intermediate tokens that reasoning depends on. Self-consistency extends this by generating several independent reasoning paths and taking the majority answer, filtering out lucky-but-unsound traces. Few-shot prompting supplies worked examples in the prompt, engaging the model's in-context learning to pick up the desired reasoning pattern. For structured domains, explicitly asking the model to state its assumptions, enumerate cases, and verify its answer against the original constraints adds another layer of rigor.
Leveraging External Tools
Tool-augmented reasoning offloads the parts LLMs are worst at to systems that are best at them. Retrieval-augmented generation grounds the model in current, verifiable evidence instead of stale training data. Handing arithmetic to a calculator, equations to a symbolic solver, and data queries to a database eliminates entire classes of hallucination. The model's job becomes orchestration: deciding which tool to call, interpreting results, and integrating them into the reasoning trace. This is the architecture behind reliable reasoning agents, and it is how production voice systems, such as those built on VideoSDK's AI agent pipeline, stay accurate during live conversations where a wrong number or fabricated policy is immediately exposed.
Fine-tuning and RLHF
Fine-tuning for reasoning makes sense when prompting cannot close the gap: when your domain has a distinctive reasoning style, a private dataset of solved traces, or strict output constraints. The most effective approach trains on reasoning traces rather than final answers, so the model learns the process, not just the destination. Reinforcement learning from human feedback, and its reasoning-focused variants, goes further by rewarding traces that are valid, honest about uncertainty, and efficient. RLHF for reasoning is how the current generation of reasoning-focused models was built, and it is why they outperform their base models on rigor and self-awareness metrics, not just accuracy. The trade-off is cost and complexity, so reserve it for cases with real volume and measurable quality targets.
Architectural Approaches for Reasoning-Focused LLMs
Architecture determines whether reasoning improvements survive contact with production. Three patterns dominate. The pure LLM approach relies on a single strong model with good prompting: simplest to build, hardest to guarantee. The reasoning-centric model approach uses a model specifically trained for extended reasoning, trading latency and cost for depth. The hybrid pipeline approach decomposes reasoning into stages, planning, retrieval, solving, verification, and routes each stage to the component that handles it best, a calculator, a solver, a retriever, or the LLM itself.
Hybrid pipelines win for most business applications because they make reasoning auditable. Each stage produces inspectable output, so when the final answer is wrong, you can locate exactly where the trace went bad. That is nearly impossible with a monolithic model call.
Solver-Learner Framework Overview
The solver-learner framework is an instructive pattern for inductive reasoning tasks. The learner component observes input-output examples and induces a candidate function or rule explaining them. The solver component then applies that induced rule to new inputs. The loop closes when the solver's predictions are checked against held-out examples: if they fail, the learner revises its hypothesis. This separates rule induction from rule application, which mirrors how humans generalize from examples, and it makes the induced rule an inspectable artifact rather than a hidden internal state.
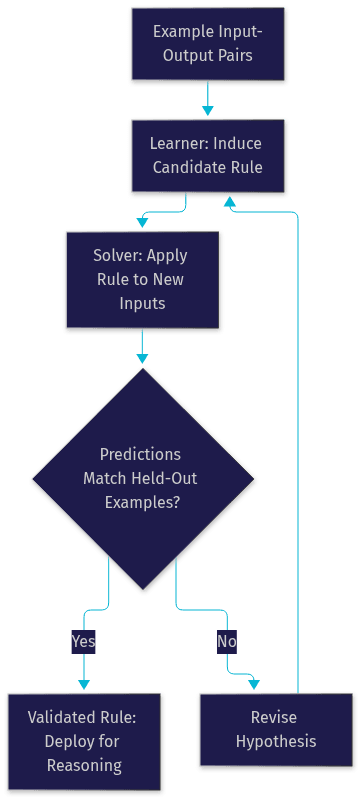
The framework generalizes beyond function learning. Any pipeline where one component proposes an explanation and another tests it against evidence follows the same shape, and it is a robust template for building reasoning agents that self-correct.
Comparison of Reasoning-Centric Architectures
| Architecture | Reasoning Depth | Latency and Cost | Auditability | Best For |
|---|---|---|---|---|
| Pure LLM with prompting | Moderate, brittle to phrasing | Low latency, low cost | Low, single opaque call | Prototypes, simple tasks |
| Reasoning-focused LLM | High on trained domains | Higher latency and cost | Medium, long visible traces | Math, code, expert analysis |
| Hybrid tool-augmented pipeline | High and verifiable | Medium, scales with stages | High, inspectable per stage | Production business logic, agents |
The hybrid pipeline is the default recommendation for production because auditability is what converts a demo into a dependable product. Pure LLM remains right for latency-critical, low-stakes interactions, and reasoning-focused models excel where the problem genuinely needs depth and the latency budget allows it.
Practical Implementation Guide
Integrating LLM reasoning into an application follows a repeatable sequence. First, define the reasoning task precisely: what inputs, what conclusions, what constraints, and what the correct behavior is when information is missing. Second, choose the model tier by benchmarking two or three candidates against your own test set, including trace-level review, not just final-answer accuracy. Third, design the prompt scaffold: the role, the required step-by-step format, the instruction to state assumptions, and the permission to say "I don't know." Fourth, wire in tools for anything deterministic: retrieval for facts, calculators for arithmetic, solvers for formal logic. Fifth, add a verification stage that checks the output against the original constraints before it reaches the user. Sixth, instrument logging from day one so every trace is stored and reviewable.
For conversational and voice-based products, the same flow applies but with tighter latency budgets. A voice agent built on VideoSDK's agent infrastructure reasons under real-time constraints, which usually means a shorter reasoning trace, aggressive tool use for anything verifiable, and a deterministic fallback for the highest-stakes answers. For complex multi-step flows where every step must happen in order, VideoSDK's Conversational Graph lets you define the reasoning flow as a graph while the LLM handles only natural language, keeping business rules deterministic.
Step-by-Step Integration Flow
The end-to-end data flow for a reasoning-enabled feature looks like this: the user query arrives and is enriched with retrieved context, the prompt scaffold assembles the query, context, and reasoning instructions, the model generates a visible reasoning trace, tools are invoked where the trace calls for verified computation, and a post-processing stage validates the final answer against constraints before delivery.
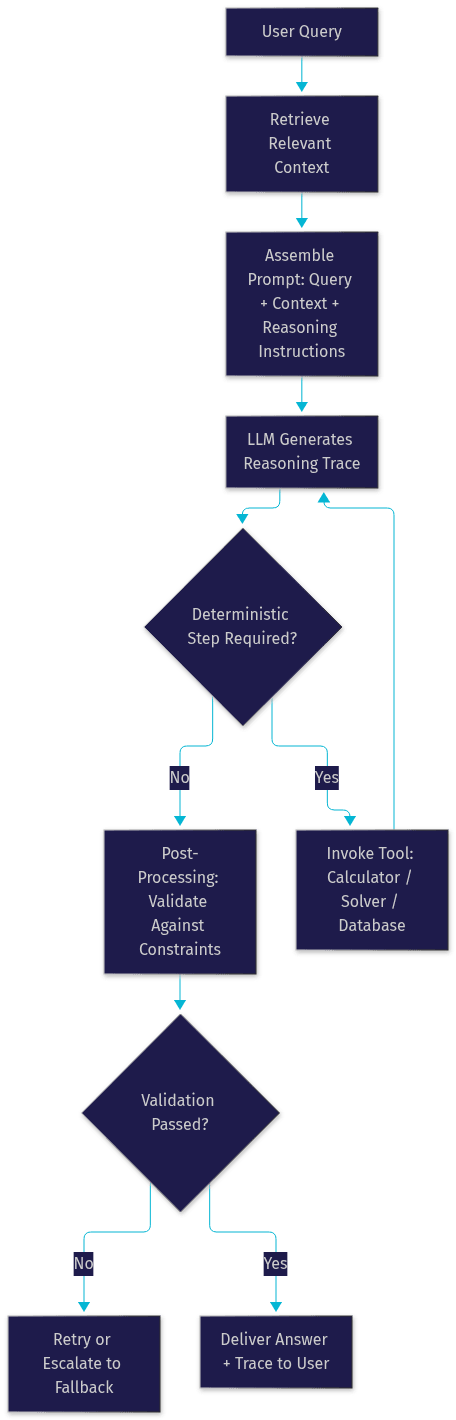
The validation gate is the piece most teams skip and most regret skipping. It is cheap, and it converts silent reasoning failures into handled ones.
Monitoring and Error Handling
Monitoring reasoning in production means logging full traces, not just answers. Three signals deserve dashboards: trace validity rate from sampled human or judge review, tool invocation failure rate, and the frequency of "I don't know" responses, which should be neither zero nor high. Detecting hallucination at runtime relies on cross-checks: verifying cited facts against the retrieval source, checking numeric results against recomputation, and flagging traces whose conclusions do not follow from their stated steps. Fallback strategies should be explicit: when confidence is low or validation fails, degrade gracefully to a narrower answer, ask a clarifying question, or route to a human. An agent that admits uncertainty retains more user trust than one that is confidently wrong, and in voice applications where responses are spoken aloud, that difference is immediately audible.
Future Directions in LLM Reasoning
Three directions will define the next phase. Multimodal reasoning, combining text, images, audio, and video evidence into a single coherent derivation, is maturing fast and unlocks domains like medical imaging triage and visual inspection. Reasoning agents that plan, act, observe, and revise over long horizons are becoming the standard architecture for autonomous work, with frameworks increasingly treating reasoning traces as first-class inspectable objects. Open-source reasoning models are closing the gap with frontier proprietary systems, which will push differentiation toward orchestration and evaluation rather than raw model access. Finally, benchmarks are evolving beyond accuracy toward rigor, self-awareness, and no-hallucination metrics, which means the models that win tomorrow will be the ones that know what they do not know.
Definitions Glossary
LLM reasoning: The process by which a large language model derives conclusions through intermediate steps rather than memorized retrieval, typically visible as a generated chain of thought.
Chain-of-thought prompting: A technique that instructs the model to work through a problem step by step before answering, improving multi-step accuracy by forcing explicit intermediate tokens.
Tool-augmented reasoning: An architecture where the LLM orchestrates external systems such as calculators, solvers, and retrievers to handle deterministic steps it would otherwise hallucinate.
Solver-learner framework: A pattern where one component induces a rule from examples and another applies it, with a validation loop that revises the rule when predictions fail.
Reasoning agent: An autonomous system that chains reasoning steps with actions and observations, revising its plan as new evidence arrives, such as those built on VideoSDK's AI agent pipeline.
RLHF for reasoning: Reinforcement learning from human feedback applied to reasoning traces, rewarding valid steps, honest uncertainty, and efficiency rather than only final answers.
Key Takeaways
- LLM reasoning is the multi-step derivation of conclusions from evidence, and it is distinct from knowledge retrieval; most production failures come from the reasoning side.
- Evaluate reasoning with a portfolio of benchmarks plus domain-specific tests, and always inspect reasoning traces, not just final answers.
- Accuracy is not enough: rigor, self-awareness, and no-hallucination metrics determine whether a model is safe in production.
- Improve reasoning in order of cost: prompting techniques first, tool augmentation second, fine-tuning and RLHF only when the cheaper levers are exhausted.
- Hybrid tool-augmented pipelines are the most auditable architecture for production reasoning, and deterministic flow layers like VideoSDK's Conversational Graph keep business-critical branching out of the LLM's hands.
Conclusion
LLM reasoning has become the dividing line between AI features that impress in demos and systems that hold up in production. The developers who win with it are the ones who treat reasoning as an engineering discipline: benchmarked, trace-inspected, tool-augmented, and monitored. Start with prompting and tooling, add a validation gate, and only then consider fine-tuning. If you are building reasoning-driven voice agents or structured conversational flows, explore VideoSDK's AI agents documentation and the Conversational Graph guide, and try the platform free at app.videosdk.live. What are you building with LLM reasoning? Drop a comment, I'd love to hear what kind of reasoning use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ