


Open-source voice cloning is the process of training or conditioning a publicly available text-to-speech model to reproduce a specific person's voice from reference audio, entirely on your own hardware. In 2026, projects like VoiceStudio, VoXtream2, and Irodori-TTS have made zero-shot cloning, streaming inference, and multi-language synthesis accessible without proprietary APIs. If you're building voice features into an app, VideoSDK's AI agent pipeline can pair these local models with real-time rooms for live voice experiences.
Introduction
Voice cloning has crossed a threshold. Two years ago, producing a convincing synthetic voice required a paid API, a GPU cluster, or both. Today, a developer with a single consumer graphics card can clone a voice from thirty seconds of reference audio using entirely open-source tooling, with no data leaving their machine.
That shift matters for reasons beyond cost. Open-source voice cloning gives you full control over the model, the weights, the inference pipeline, and the licensing terms. You can audit what the model does, fine-tune it on your own data, embed it in products without per-character billing, and keep sensitive audio off third-party servers.
The community has responded with a wave of new projects. VoiceStudio (also known by its OmniVoice engine) delivers a local-first, multi-language cloning studio with a graphical interface. VoXtream2 focuses on streaming text-to-speech with dynamic speaking-rate control. Irodori-TTS pushes the research frontier with a flow-matching diffusion model that even accepts emoji as style cues. Voice DNA Studio rounds out the landscape with an identity-lock workflow for preserving speaker characteristics across long generations.
This guide walks through the landscape, the neural technology underneath it, how to set up a pipeline, and the ethical guardrails you need before you clone anyone's voice.
What Is Voice Cloning?
Voice cloning is defined as the process of mapping a target speaker's vocal characteristics onto a speech synthesis model so that the model generates new speech in that voice. The model learns, or is conditioned on, the speaker's timbre, pitch range, pacing, and prosodic habits, then applies that identity to arbitrary text.
There are two broad approaches. Speaker-dependent cloning trains or fine-tunes a model on a specific person's recordings, producing the highest fidelity but requiring more data and compute. Zero-shot voice cloning instead extracts a speaker embedding from a short reference clip, often under a minute, and conditions a general-purpose model on that embedding at inference time. Most modern open-source projects, including VoiceStudio and Irodori-TTS, lean heavily on zero-shot methods because they work instantly with minimal data.
Landscape of Open-Source Voice Cloning
The 2026 open-source voice cloning ecosystem is no longer a collection of research demos. It is a set of production-grade projects with distinct philosophies, active maintainers, and real users.
Major Projects Overview
VoiceStudio (OmniVoice) takes the studio approach. It bundles a multi-language cloning engine behind a local-first interface, meaning everything runs on your machine with no cloud calls. It targets creators who want to manage a library of cloned voices, switch languages, and iterate on delivery without touching a terminal.
VoXtream2 is built for latency. It is a streaming TTS engine with dynamic speaking-rate control, which means you can speed a voice up or slow it down mid-generation without restarting the synthesis. That makes it a natural fit for conversational agents, live narration, and any pipeline where audio must start playing before the full text is processed.
Irodori-TTS represents the research frontier. It uses a flow-matching diffusion architecture for speech synthesis and supports expressive conditioning, including emoji-based style control, where an emoji in the input nudges the emotional coloring of the output. It is the most experimental of the group and the most interesting to watch.
Voice DNA Studio focuses on identity preservation. Its workflow extracts a durable "voice DNA" profile from reference audio and locks that identity across long-form generations, reducing the drift where a cloned voice slowly loses its character over a lengthy script.
Comparative Feature Table
[LINKABLE ASSET — comparison table]
| Project | License | Languages | Latency Profile | GPU Needs | Community Activity |
|---|---|---|---|---|---|
| VoiceStudio (OmuiVoice) | Permissive open source | Multi-language | Batch-oriented, moderate | Mid-range GPU recommended | High, active releases |
| VoXtream2 | Open source | Multi-language | Streaming, low-latency | Mid-range GPU, CPU fallback | High, streaming focus |
| Irodori-TTS | Research-friendly license | Primarily Japanese and English | Slower diffusion inference | Higher VRAM for best quality | Growing, research-driven |
| Voice DNA Studio | Open source | Multi-language | Batch with identity lock | Mid-range GPU | Moderate, niche focus |
The most important row for most developers is VoXtream2's latency profile. If your use case is conversational, streaming beats raw quality. If your use case is long-form narration, Voice DNA Studio's identity lock matters more than milliseconds.
Core Technologies Behind Open-Source Voice Cloning
Understanding what runs underneath these projects helps you choose between them and debug them when output quality disappoints.
Neural Architectures
Three architectural families dominate open-source voice cloning in 2026.
Diffusion and flow-matching models, used by Irodori-TTS, generate speech by iteratively refining noise into coherent audio under text and speaker conditioning. Flow-matching is a newer refinement of diffusion that learns a direct velocity field between noise and data, which typically means fewer inference steps and cleaner prosody. The trade-off is compute: even optimized, diffusion-based synthesis is slower than feed-forward alternatives.
Transformer-based TTS, the backbone of VoiceStudio and VoXtream2, treats speech generation as a sequence modeling problem. The model predicts audio codec tokens or mel-spectrogram frames autoregressively, conditioned on input text and a speaker embedding. Transformers parallelize well during training and support streaming during inference, which is why they anchor the low-latency projects.
GAN-style and auto-encoder approaches remain relevant for lightweight deployment. Generative adversarial setups produce mel-spectrograms in a single forward pass, trading some naturalness for speed. Auto-encoder-based codec models, popularized by projects on Hugging Face, compress audio into discrete tokens that a transformer can predict, forming the two-stage pipeline most modern systems share.
Speaker Embedding and Identity Preservation
A speaker encoder is a small neural network trained to compress everything that makes a voice recognizable, including timbre, pitch distribution, and prosodic habits, into a fixed-length vector. During zero-shot cloning, this embedding is extracted from reference audio and injected into the synthesis model as a conditioning signal.
Identity preservation is the hard part. Over long generations, models can drift away from the embedding, producing speech that sounds like a faded copy of the target. Voice DNA Studio's identity-lock workflow addresses this by periodically re-anchoring generation to the extracted profile, a technique worth studying if you build your own pipeline.
Real-Time and Low-Latency Inference
Latency in voice cloning comes from three places: model size, inference runtime, and whether synthesis is streaming or batch.
CUDA acceleration on an NVIDIA GPU remains the default path, cutting synthesis time per sentence from seconds to fractions of a second. Quantized weight formats in the GGUF family, popularized by the local LLM community, let these models run on smaller cards and even CPUs at reduced quality. Streaming pipelines, VoXtream2's specialty, split text into chunks, synthesize the first chunk immediately, and keep generating while earlier audio plays. The result is perceived latency close to the first chunk's synthesis time rather than the full utterance.
For live voice agents, this matters enormously. A conversational system that waits two seconds before responding feels broken. One that starts speaking in under 300 milliseconds feels alive.
Setting Up a Voice Cloning Pipeline
Here is where theory meets practice. The good news: installation has never been easier. The caveat: hardware choices determine what you can realistically run.
Hardware and Environment Requirements
For comfortable zero-shot cloning with transformer-based models, plan for a GPU with at least 8 to 12 GB of VRAM, a CUDA runtime matching your driver version, and a Linux or Windows environment with a few tens of gigabytes of free disk for weights. Diffusion-based models like Irodori-TTS want more headroom, ideally 16 GB or more, for high-quality inference. CPU-only operation is possible with quantized models but expect generation times measured in tens of seconds per sentence, which rules out conversational use.
Installation Workflow
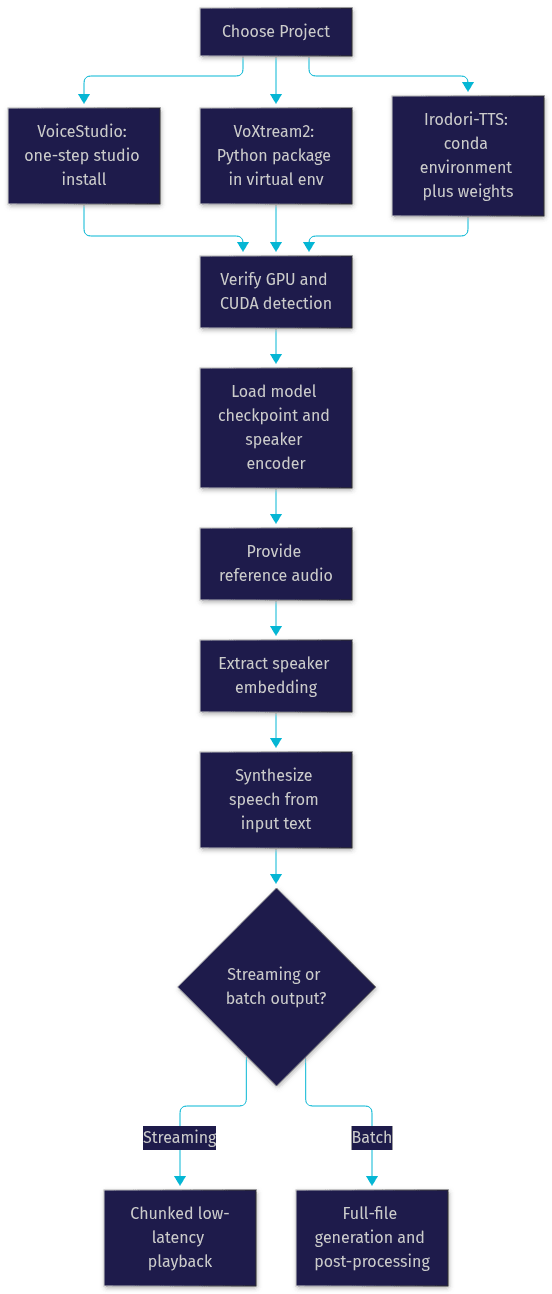
Each major project has converged on a different distribution philosophy, and the differences are worth understanding before you commit.
VoiceStudio ships as a self-contained local studio. Installation is a single step that pulls the interface, engine, and default voice library together. After it finishes, you launch the studio, verify that it detects your GPU, and you can clone your first voice within minutes. The local-first design means nothing phones home.
VoXtream2 distributes through Python's standard package ecosystem. You install it into a virtual environment, confirm the CUDA-backed inference backend is available, and load a model checkpoint. Because it is a library rather than an application, you integrate it into your own codebase, which suits developers embedding TTS into a larger service.
Irodori-TTS uses a conda-based environment to manage its research dependencies. You create the environment, activate it, fetch the model weights, and run inference through the project's provided entry points. It is the most involved setup of the three, reflecting its research origins.
The following diagram shows how these installation paths converge on a common inference pipeline:
Data Preparation and Voice DNA Extraction
Reference audio quality is the single biggest factor in cloning fidelity. Use clean recordings: no background music, minimal room echo, consistent microphone distance, and thirty seconds to a few minutes of natural speech. Trim silences, normalize loudness, and if possible capture a range of emotional delivery. Projects like Voice DNA Studio formalize this step as extracting a voice profile, but even a simple pipeline benefits from disciplined audio hygiene at this stage.
Practical Use Cases
Open-source voice cloning earns its place in real production workflows, not just hobby projects.
Content creation is the most obvious application. Creators producing Reels, Shorts, and podcasts clone their own voice once, then generate narration for dozens of videos without re-recording. Multi-language support in projects like VoiceStudio means the same cloned identity can narrate in several languages, which is transformative for creators with international audiences.
Localization and dubbing benefit from the same capability. Instead of hiring voice talent per market, a production team can clone a performance (with consent) and generate localized audio that preserves the original speaker's recognizable character across languages.
Interactive voice agents and gaming NPCs are where low latency becomes essential. VoXtream2-class streaming engines let a game character or support agent speak with a consistent, distinctive voice while responding in near real time. If you are building this kind of experience, VideoSDK's AI voice agent pipeline handles the speech-to-text, LLM reasoning, and text-to-speech chain inside real-time rooms, and you can pair it with your own TTS provider choices for full control over the voice layer.
Accessibility tools may be the most meaningful use case. Individuals facing voice loss from illness can bank their voice early and continue speaking through a cloned synthetic version. Open-source tooling matters here because it keeps deeply personal voice data under the user's control, on their own hardware, with no third-party retention.
Challenges and Ethical Considerations
The same technology that restores a voice can steal one. Every developer working in this space needs to take the risks seriously.
Voice identity theft and deepfake risk is the headline concern. A convincing clone of a public figure can be used for fraud, misinformation, and harassment. As synthesis quality improves, detection becomes harder, and the burden shifts to builders to prevent misuse. Treat the ability to clone a voice as the ability to impersonate a person.
Licensing implications are subtler. An open-source license on the code does not always mean open rights on the model weights, the training data, or the cloned voice itself. Some research-friendly licenses restrict commercial use. A cloned voice may carry personality rights belonging to the person recorded. Before shipping a product, verify the code license, the weights license, and your rights to the target voice, all three.
Best practices for consent and watermarking are emerging as community norms. Obtain explicit, documented consent from anyone whose voice you clone, and keep that record. Prefer synthetic or self-cloned voices for public demos. Where available, enable provenance watermarking so generated audio can be identified as synthetic. And when building interactive agents, disclose that the voice is AI-generated to the people interacting with it. The W3C and related standards bodies have ongoing work on content provenance that is worth tracking as this area matures.
Future Trends in Open-Source Voice Cloning
Three trends will shape the next two years.
First, diffusion-based and flow-matching TTS will keep closing the latency gap with transformers. Techniques like distillation and fewer-step sampling are already bringing Irodori-TTS-class quality closer to interactive speeds, and the quality ceiling for expressive, emotionally controllable speech sits with these architectures.
Second, multimodal conditioning is arriving. Emoji style control in Irodori-TTS is an early signal of a broader shift toward controlling delivery through natural, non-verbal cues, alongside text prompts that describe tone, emotion, and pacing directly.
Third, community-driven model hubs, building on the distribution patterns proven by Hugging Face and the open-weight LLM ecosystem, will make cloned-voice models and speaker embeddings shareable, versioned artifacts. Expect better multilingual coverage, smaller quantized variants, and faster iteration cycles as a result. For developers building live experiences, these improvements pair naturally with real-time infrastructure, and VideoSDK's Python SDK offers a path to connect custom synthesis pipelines into real-time audio rooms.
Definitions Glossary
Voice cloning: The process of conditioning or training a speech synthesis model to reproduce a specific person's voice from reference audio, applying that vocal identity to arbitrary new text.
Zero-shot voice cloning: Cloning that extracts a speaker embedding from a short reference clip at inference time, requiring no per-speaker training and enabling instant cloning from seconds of audio.
Speaker embedding: A fixed-length vector produced by a speaker encoder that captures the recognizable characteristics of a voice, including timbre, pitch distribution, and prosodic habits, used to condition synthesis models.
Flow-matching TTS: A diffusion-derived synthesis approach that learns a direct transformation path from noise to speech, typically achieving high naturalness with fewer inference steps than classic diffusion.
Streaming TTS: A synthesis pipeline that splits text into chunks and begins playing audio for the first chunk while later chunks are still being generated, minimizing perceived latency for conversational use.
Voice DNA: A durable speaker profile extracted from reference audio and used to lock voice identity across long-form generations, reducing character drift in extended output.
Key Takeaways
- Open-source voice cloning in 2026 lets developers clone voices from under a minute of reference audio, entirely on local hardware, with no proprietary API or per-character billing.
- VoiceStudio offers a local-first multi-language studio, VoXtream2 delivers streaming low-latency synthesis with dynamic rate control, Irodori-TTS pushes flow-matching diffusion quality, and Voice DNA Studio solves long-form identity preservation.
- Transformer architectures power the low-latency projects, while diffusion and flow-matching models hold the quality ceiling, with quantized formats extending both to smaller GPUs.
- Reference audio quality is the single biggest determinant of cloning fidelity, so invest in clean, consistent recordings before tuning anything else.
- Consent, licensing verification across code, weights, and voice rights, and provenance watermarking are non-negotiable practices for responsible deployment.
Conclusion
Open-source voice cloning has matured from research curiosity into a practical toolkit. Whether you need a local-first studio like VoiceStudio, streaming latency from VoXtream2, or the expressive frontier of Irodori-TTS, the ecosystem now covers the full spectrum from hobby narration to production voice agents, all under your control. Build with consent, verify your licenses, and watermark where you can. If you're taking cloned voices into live, interactive experiences, explore how VideoSDK's AI agents and real-time communication SDKs connect custom TTS pipelines to real-time rooms, and get started free at app.videosdk.live/login. What are you building with open-source voice cloning? Drop a comment, I'd love to hear what kind of voice experience you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ