


A speech recognition SDK is a software development kit that converts spoken audio into text inside your application, handling audio capture, encoding, model inference, and result delivery so you don't have to build speech-to-text infrastructure yourself. The right choice depends on your latency budget, privacy requirements, and platform targets. VideoSDK, for example, pairs real-time transcription with its video and audio calling SDKs, so you can add live captions to a call in one integration. Start by defining your use case, then pilot two or three candidates.
Voice is becoming a default interface. From virtual assistants and telehealth consultations to in-game voice commands and live call transcription, users increasingly expect apps to listen, transcribe, and respond in real time. Building that capability from scratch means training acoustic models, maintaining inference infrastructure, and keeping up with an accuracy arms race that large providers run continuously. That is why most teams reach for a speech recognition SDK instead.
A speech recognition SDK gives you a packaged pipeline: audio capture, encoding, model inference, and result handling, exposed through a clean API surface. This guide covers what these SDKs are, the features that actually matter, a comparison of the leading options in 2026, and how to integrate one without the usual production headaches.
What Is a Speech Recognition SDK?
A speech recognition SDK is defined as a set of libraries, APIs, and tools that let developers embed automatic speech recognition (ASR) into an application without building the underlying machine learning systems. It works by capturing raw audio from a microphone or stream, encoding it into a format the recognition model accepts, sending it to an inference engine (either in the cloud or on-device), and returning transcribed text to your application logic.
Most SDKs expose four core components. Audio capture interfaces with the device microphone or an incoming media stream. The encoding layer normalizes sample rates, channel layouts, and compression formats. The inference engine, whether a hosted neural model or a bundled on-device model, converts audio features into text. Finally, result handling delivers final and interim transcripts, confidence scores, and timing metadata back to your app.
The distinction between an SDK and a raw API matters. A speech recognition SDK typically ships client libraries for multiple platforms, handles audio stream management for you, and manages reconnection and session state. A bare REST transcription API expects you to do that plumbing yourself. For real-time products like live captioning or voice agents, the SDK route saves weeks of work.
Why Choose a Speech Recognition SDK?
Building custom ASR is a multi-year commitment: data collection, model training, and constant retraining as accents, domains, and devices evolve. A speech recognition SDK offloads all of that.
The benefits compound. Speed to market is the obvious one: a working transcription feature in days instead of quarters. Scalability is another, since cloud SDKs absorb concurrency spikes without you provisioning GPUs. Accuracy improves for free as providers upgrade their models. And maintenance, the invisible cost, disappears: no model drift to monitor, no inference fleet to patch.
There is a trade-off worth naming. SDKs create vendor dependency and per-usage cost. For highly sensitive domains or fully offline products, an open-source on-device SDK may be the better fit, which we cover below.
Key Features to Look For
Real-Time Transcription
Real-time transcription is the difference between a transcript that arrives after the conversation and one that arrives during it. Look for streaming recognition with interim results, where the SDK returns best-guess text that refines as more audio context arrives. Low-latency speech SDKs target final results within a few hundred milliseconds of speech ending. Active speaker detection, which identifies who is talking in multi-party audio, is essential for meeting transcription and voice agents. VideoSDK's real-time transcription runs inside its calling rooms, so captions align with the active speaker automatically.
Multi-Language & Locale Support
If your product ships internationally, language coverage is a hard requirement. Evaluate not just the count of supported languages but dialect and accent coverage within each, and whether you can switch languages mid-session. Some SDKs auto-detect the spoken language; others require you to declare it per request, which affects UX for multilingual users.
Offline vs. Cloud Processing
Cloud speech SDKs offer the best accuracy and the largest models, but they require connectivity and introduce privacy considerations. Offline speech recognition SDKs run models on-device: lower accuracy in most cases, but zero network latency, no data leaving the device, and guaranteed availability. Telehealth, legal, and field-work apps often mandate offline or on-premise processing. Hybrid approaches use cloud recognition with an offline fallback when connectivity drops.
Custom Vocabulary & Contextual Biasing
Domain vocabulary is where generic models fail. Product names, drug names, and industry jargon get mangled by default models. Look for custom vocabulary support, sometimes called speech context or contextual biasing, where you supply a list of terms the model should prefer. Some providers also support custom model training on your own audio data for maximum accuracy in specialized domains.
Security & Privacy Controls
Evaluate authentication (token-based auth with server-side generation, never embedded keys), encryption in transit and at rest, and data residency options. For regulated industries, check whether the provider offers region pinning, zero data retention modes, and compliance certifications like HIPAA or SOC 2. Privacy-focused speech SDKs that process everything on-device eliminate the data residency question entirely.
Platform Coverage
A cross-platform speech SDK saves you from maintaining parallel integrations. Check for Web (JavaScript), iOS, Android, React Native, Flutter, Unity, Python, and C++ support, and verify feature parity across platforms. Gaming and IoT products should specifically confirm Unity and embedded C++ support, which many cloud SDKs still lack.
Comparison of Leading Speech Recognition SDKs
Choosing a category first narrows the field faster than comparing individual products. Cloud providers win on accuracy and language breadth. Mobile-first SDKs win on device integration. Open-source options win on cost and privacy.
Cloud Providers
Azure Speech SDK, Google Cloud Speech-to-Text, and AWS Transcribe form the enterprise tier: broad language coverage, strong custom vocabulary tooling, and deep integration with their respective clouds. Deepgram has built a strong developer following for low-latency streaming recognition, with its current generation of models targeting fast, accurate conversational transcription. Pricing models differ meaningfully: per-minute audio pricing is standard, but streaming versus batch rates, and tiered volume discounts, change real costs at scale.
Mobile-First SDKs
Apple's Speech framework gives iOS apps free on-device recognition with good accuracy for supported languages, with no network dependency. Naver CLOVA dominates in Korean and Japanese markets. These SDKs shine when your product lives entirely on one mobile platform, though cross-platform teams then face a fragmentation problem: different SDKs, different accuracy profiles, different behavior.
Open-Source & On-Device Options
Vosk offers lightweight offline recognition across 20-plus languages, running on devices as small as a Raspberry Pi. Whisper-based runtimes like Whisper-CPP bring OpenAI's open-weight Whisper models on-device with efficient CPU inference. The pros: zero per-minute cost, full privacy, offline operation. The cons: you own the accuracy ceiling, model updates, and performance tuning on low-end hardware.
The decision tree below maps these categories to typical constraints:
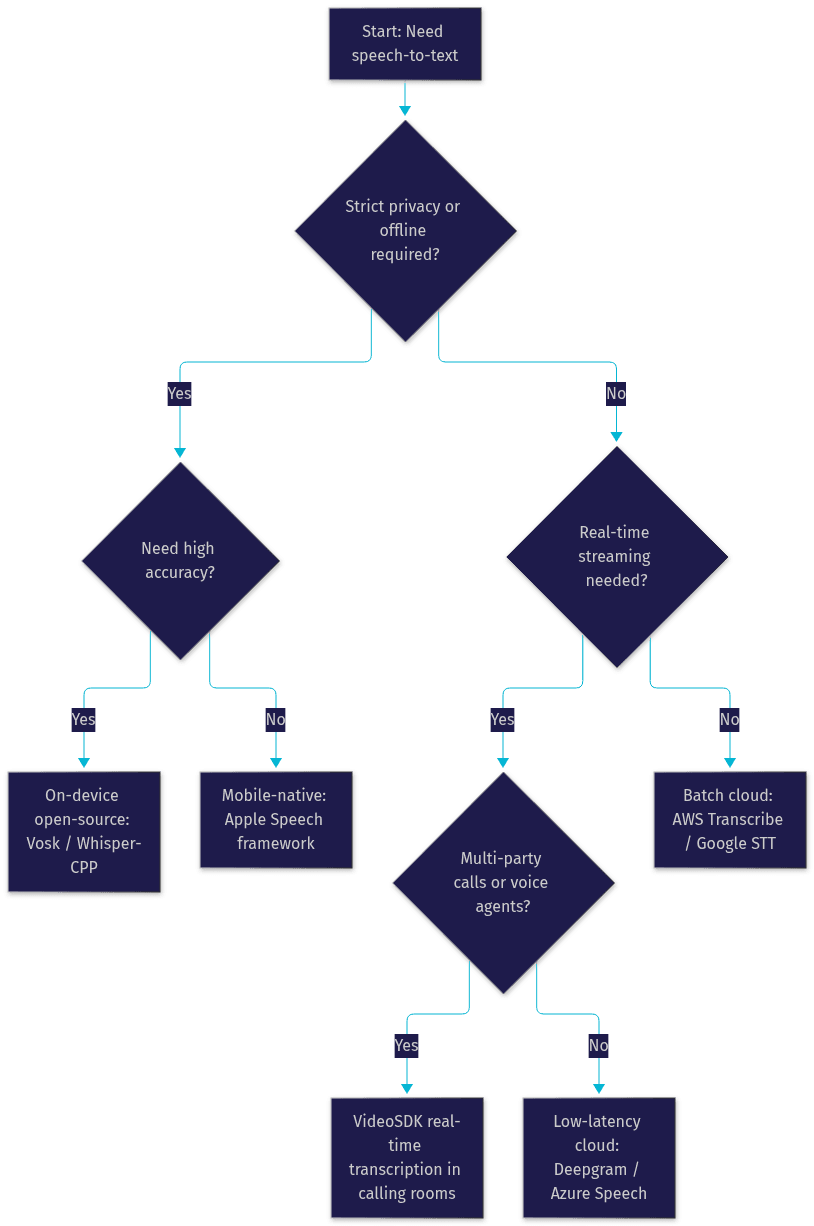
[LINKABLE ASSET: SDK category decision tree]
How to Evaluate and Select a Speech Recognition SDK
A structured evaluation beats a feature-checklist skim. Follow these five steps.
1. Define your use case precisely. Voice commands, meeting transcription, and voice agents have wildly different requirements. A gaming voice command system needs sub-200ms latency and small vocabularies. A telehealth transcription system needs accuracy, HIPAA compliance, and speaker labels. Write down your scenario before looking at any vendor.
2. Set accuracy and latency targets. Pick measurable numbers: word error rate below a threshold on your domain's audio, and final-result latency under your UX budget. Interim results matter for conversational UX; final accuracy matters for records and analytics.
3. Run a pilot test on real audio. Vendor benchmarks use clean datasets. Your audio has accents, background noise, and domain jargon. Collect 30 to 60 minutes of representative audio and run it through each candidate SDK. Measure word error rate yourself.
4. Compare pricing at your real volume. Model your monthly audio minutes, including growth, against each provider's tiers. Watch for streaming-versus-batch rate differences and features gated behind higher tiers, like custom vocabulary or speaker diarization.
5. Assess documentation and support. Read the actual integration guides, check SDK release cadence, and test the support channel responsiveness. A speech recognition SDK with stale docs and slow support costs more than a slightly pricier one with an active team behind it.
Integration Best Practices
Once you've selected a speech recognition SDK, these practices separate a demo from a production feature.
Token Management & Authentication
Generate authentication tokens server-side using your credentials, then hand short-lived tokens to clients. Never embed API keys in client code. Rotate tokens on a short interval and revoke them on session end. This is the same pattern VideoSDK uses for its meeting tokens, and it's the single most common security mistake in speech SDK integrations.
Audio Pre-Processing
Match the SDK's expected audio format exactly: sample rate, channel count, and encoding. Mismatches cause silent accuracy degradation. Apply noise suppression before recognition when your environment is noisy, but test carefully: aggressive suppression can hurt accuracy on some models. For multi-party calls, use the SDK's active speaker detection rather than transcribing a mixed stream and guessing who spoke.
Handling Latency & Network Variability
Buffer audio client-side during network hiccups and resume streaming when connectivity returns. For products where transcription is critical, implement a fallback: switch to an offline recognition model when the cloud connection degrades beyond a threshold. Show interim results in the UI so users perceive responsiveness even when final results lag.
Error Handling & Resilience
Plan for the failure modes you will actually hit: authentication expiry mid-session, microphone permission revocation, silence timeouts, and rate limits. Use exponential backoff on retries, and design your result pipeline to be idempotent so a retried recognition request doesn't duplicate transcript entries.
Scaling for High Concurrency
At scale, connection pooling and regional load balancing keep latency stable. Monitor concurrent streams against your provider's limits, and set up cost alerts: per-minute pricing scales linearly with usage, and a runaway transcription loop can produce a surprising bill. Track cost per session as a first-class metric.
A typical production integration looks like this:
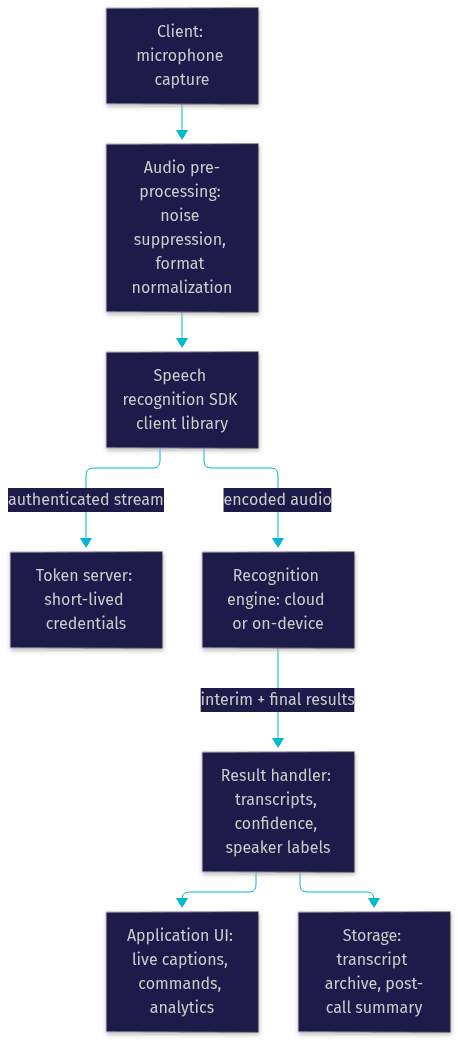
[LINKABLE ASSET: integration architecture diagram]
Future Trends in Speech Recognition
Three shifts are reshaping the speech recognition SDK landscape in 2026. First, real-time multimodal models, like OpenAI's Realtime API and Google's Gemini Live, are collapsing speech recognition and language understanding into a single streaming model, enabling voice agents that transcribe, reason, and respond in one pass. Second, on-device neural accelerators in modern phones and laptops are making high-accuracy offline recognition practical, shrinking the accuracy gap between cloud and on-device SDKs. Third, privacy-preserving techniques, including federated learning, let providers improve models without centralizing user audio, which will ease compliance burdens in healthcare and finance.
For developers, the practical implication is that the line between a speech recognition SDK and a full voice AI pipeline is blurring. Platforms like VideoSDK's AI agents already combine speech-to-text, LLM reasoning, and text-to-speech inside real-time communication rooms, a preview of where the whole category is heading.
Definitions Glossary
Speech Recognition SDK: A development kit that packages audio capture, encoding, model inference, and result delivery so developers can embed speech-to-text without building ASR infrastructure themselves.
ASR (Automatic Speech Recognition): The underlying technology that converts spoken audio into text using acoustic and language models, powering every speech recognition SDK.
Interim Results: Partial, best-guess transcripts returned while the user is still speaking, which refine as more audio context arrives; essential for responsive conversational UX.
Custom Vocabulary Support: An SDK feature that lets developers supply domain-specific terms the recognition model should prefer, improving accuracy on product names, jargon, and specialized terminology.
Speaker Diarization: The process of separating a transcript by who spoke, critical for meeting transcription and multi-party calls; VideoSDK provides this via active speaker detection in its rooms.
On-Device Recognition: Speech recognition that runs entirely on the local device using bundled models, offering offline operation and full data privacy at the cost of some accuracy.
Key Takeaways
- A speech recognition SDK packages the full speech-to-text pipeline, saving months of model training and infrastructure work compared to building custom ASR.
- Choose cloud SDKs for accuracy and language breadth, mobile-native SDKs for single-platform simplicity, and open-source on-device SDKs for privacy and offline needs.
- Real-time features that matter most are streaming recognition with interim results, active speaker detection, and custom vocabulary support for domain accuracy.
- Evaluate candidates with a pilot test on your own audio, measuring word error rate and latency yourself rather than trusting vendor benchmarks.
- For real-time communication products, VideoSDK combines calling, live transcription, and AI voice agents in one SDK, eliminating a separate transcription integration.
Conclusion
The speech recognition SDK you pick should be decided by your use case, not a feature checklist: latency budget, privacy constraints, platform targets, and domain vocabulary all narrow the field quickly. Pilot two or three finalists on your real audio before committing, and design the integration for token security, network variability, and cost monitoring from day one. If your product involves real-time calls or voice agents, explore VideoSDK's real-time transcription and AI voice agent capabilities alongside its video and audio calling SDKs. You can start free at app.videosdk.live/login. What are you building with speech recognition? Drop a comment, I'd love to hear what kind of voice use case you're working on.
Microsoft Azure Speech SDK
The Microsoft Azure Speech SDK is a cloud-based service that offers a wide range of speech recognition capabilities, including speech-to-text, text-to-speech, and speech translation. It supports a variety of languages and offers high accuracy rates. It is known for its strong enterprise features and integrations with other Azure services.
Python
1import azure.cognitiveservices.speech as speechsdk
2
3speech_config = speechsdk.SpeechConfig(subscription="YOUR_SUBSCRIPTION_KEY", region="YOUR_REGION")
4audio_config = speechsdk.AudioConfig(filename="audio.wav")
5
6speech_recognizer = speechsdk.SpeechRecognizer(speech_config=speech_config, audio_config=audio_config)
7
8print("Recognizing...")
9
10result = speech_recognizer.recognize_once_async().get()
11
12if result.reason == speechsdk.ResultReason.RecognizedSpeech:
13    print("Recognized: {}".format(result.text))
14elif result.reason == speechsdk.ResultReason.NoMatch:
15    print("No speech could be recognized: {}".format(result.no_match_details))
16elif result.reason == speechsdk.ResultReason.Canceled:
17    cancellation_details = result.cancellation_details
18    print("Speech Recognition Canceled: {}".format(cancellation_details.reason))
19    if cancellation_details.reason == speechsdk.CancellationReason.Error:
20        print("Error details: {}".format(cancellation_details.error_details))
Google Cloud Speech-to-Text
Google Cloud Speech-to-Text is another powerful cloud-based speech-to-text SDK that leverages Google's advanced machine learning algorithms. It offers high accuracy, supports a wide range of languages, and provides features like automatic punctuation and speaker diarization. It also integrates seamlessly with other Google Cloud services.
Python
1from google.cloud import speech
2
3def transcribe_file(speech_file):
4    """Transcribe the given audio file."""
5    client = speech.SpeechClient()
6
7    with open(speech_file, "rb") as audio_file:
8        content = audio_file.read()
9
10    audio = speech.RecognitionAudio(content=content)
11    config = speech.RecognitionConfig(
12        encoding=speech.RecognitionConfig.AudioEncoding.LINEAR16,
13        sample_rate_hertz=16000,
14        language_code="en-US",
15    )
16
17    response = client.recognize(config=config, audio=audio)
18
19    for result in response.results:
20        print("Transcript: {}".format(result.alternatives[0].transcript))
21
22transcribe_file("audio.wav")
Amazon Transcribe
Amazon Transcribe is a speech-to-text SDK offered by Amazon Web Services (AWS). It provides accurate and scalable speech recognition capabilities for a variety of use cases, including transcription of audio and video files, real-time transcription, and call center analytics. It integrates well with other AWS services. The tool allows you to create a custom speech recognition SDK.
AssemblyAI
AssemblyAI provides a speech recognition SDK designed for developers who need accurate transcription and powerful audio intelligence features. It's known for its ease of use and developer-friendly API. They offer features like entity detection, topic detection, and sentiment analysis alongside the core speech-to-text functionality.
Other Notable SDKs
Other notable speech recognition SDKs include Deepgram, Kaldi (an open-source toolkit), and CMU Sphinx. The best speech recognition SDK for you depends on your specific requirements and budget.
Integrating a Speech Recognition SDK into Your Application
Integrating a speech recognition SDK into your application typically involves the following steps:
Setting Up Your Development Environment
Before you begin, ensure that you have the necessary tools and libraries installed. This may include installing the SDK itself, setting up API keys, and configuring your development environment to work with the SDK. Follow the SDK's speech recognition SDK documentation for specific instructions.
Step-by-Step Integration Guide
- Install the SDK: Use the appropriate package manager or installation method to install the speech recognition SDK in your project. Example:
pip install azure-cognitiveservices-speech - Authenticate: Obtain API keys or credentials from the speech recognition API provider and configure your application to authenticate with the service.
- Configure Speech Recognition: Create a
SpeechConfigobject (or equivalent) to specify the language, region, and other settings for speech recognition. For example, for Azure this configures language to use, region to connect to, and the Azure subscription information. - Create an Audio Configuration: Configure the audio input source, such as a microphone or an audio file. Use an
AudioConfig(or equivalent) to specify these settings. You can specify the location of a .wav file, or set it to use the microphone as input. - Create a Speech Recognizer: Instantiate a
SpeechRecognizerobject (or equivalent) using the configuredSpeechConfigandAudioConfigobjects. - Start Speech Recognition: Call the appropriate method to start speech recognition. This may involve calling
recognize_once_async()for single utterances orstart_continuous_recognition_async()for continuous speech recognition. - Handle Results: Implement event handlers or callbacks to process the results of speech recognition. Extract the recognized text from the results and use it in your application.
- Error Handling: Implement error handling to catch and handle any errors that may occur during speech recognition. Check for network connectivity issues, invalid API keys, or other potential problems.
Python
1# This is a generic example and will need adaptation for the specific SDK.
2
3# Replace with your actual SDK import
4#import myspeechsdk as speechsdk
5
6# Replace with your actual API key and region
7API_KEY = "YOUR_API_KEY"
8REGION = "YOUR_REGION"
9
10# Replace with your actual audio file path
11AUDIO_FILE = "audio.wav"
12
13try:
14    # Initialize speech recognition engine
15    #engine = speechsdk.SpeechRecognitionEngine(API_KEY, REGION)
16
17    # Configure audio source
18    #engine.set_audio_source(AUDIO_FILE)
19
20    # Start recognition
21    #result = engine.recognize()
22
23    # Print the result
24    #print(f"Recognized text: {result.text}")
25    print("Please note: This is a placeholder for actual code integration")
26
27except Exception as e:
28    print(f"Error during speech recognition: {e}")
Handling Errors and Debugging
When integrating a speech recognition SDK, it's important to implement robust error handling to gracefully handle potential issues. Common errors include network connectivity problems, invalid API keys, and incorrect audio formats. Use logging and debugging tools to identify and resolve these issues. Check for API rate limits and handle them gracefully.
Optimizing Performance
To optimize the performance of your speech recognition SDK integration, consider the following tips:
- Use appropriate audio formats: Choose audio formats that are optimized for speech recognition, such as WAV or FLAC.
- Reduce background noise: Minimize background noise in the audio input to improve accuracy.
- Use appropriate sample rates: Use appropriate sample rates for speech recognition, typically 16 kHz or 44.1 kHz.
- Cache results: Cache frequently accessed speech recognition results to reduce latency and improve performance.
Advanced Features and Customization
Many speech recognition SDKs offer advanced features and customization options to enhance the accuracy and functionality of your applications.
Custom Speech Models
Custom speech models allow you to train the speech recognition SDK on specific vocabularies or accents, improving accuracy for niche applications or industries. This is particularly useful for applications that involve specialized terminology or require recognition of unique accents. This option can greatly improve the accuracy of speech recognition SDKs.
Language Support and Localization
Ensure that the speech recognition SDK supports the languages and regions you need to target. Some SDKs offer advanced localization features, such as automatic language detection and regional accent adaptation. If you are looking for a multilingual speech recognition SDK, pay attention to which locales the SDK has strong models for.
Real-time vs. Offline Processing
Choose the appropriate processing mode based on your application's requirements. Real-time speech recognition SDK is suitable for applications that require immediate transcription or voice commands, while offline speech recognition SDK is ideal for transcribing pre-recorded audio files. Pay attention to the limitations of speech recognition SDKs, such as latency in real-time processing.
Future Trends in Speech Recognition SDKs
The future of speech recognition SDKs is promising, with ongoing advancements in machine learning and artificial intelligence. Some key trends include:
- Improved Accuracy: Continued improvements in machine learning algorithms are leading to more accurate and robust speech recognition capabilities.
- Enhanced Customization: SDKs are offering more advanced customization options, allowing developers to fine-tune speech recognition models for specific use cases.
- Edge Computing: The rise of edge computing is enabling on-device speech recognition SDK for applications that require low latency or operate in offline environments (offline speech recognition SDK).
- Integration with AI: Speech recognition SDKs are increasingly being integrated with other AI technologies, such as natural language processing (NLP) and machine translation, to create more intelligent and versatile applications.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ