


Realtime API function calling is the mechanism that lets a live, streaming AI model invoke external tools mid-conversation, without ending the session or waiting for a full request-response cycle. Instead of the model producing text that your backend later parses, the model emits a structured function call event over the WebSocket while the user is still talking, your server executes the tool, and the result streams back so the model can respond in natural speech. VideoSDK's AI Voice Agent SDK uses this same pattern to connect speech-to-text, LLM, and text-to-speech providers into sub-second voice interactions, including function tools and MCP integration for real-time tool invocation.
Latency is the whole game in voice AI. A text chatbot can take two seconds to think and nobody notices. A voice agent that pauses for two seconds after you finish speaking feels broken. That single constraint reshapes how function calling has to work: the traditional pattern of sending a full prompt, waiting for a complete response, and parsing tool invocations from the output simply cannot keep up with a live audio stream.
Realtime API function calling solves this by moving tool invocation into the streaming session itself. The model knows your function schemas up front, decides mid-turn whether a tool is needed, and pauses its speech generation just long enough for your server to return a result. By the end of this article you will understand the full architecture, how to configure sessions and turn detection, how to build robust function handlers, and how to monitor, optimize, and secure a production realtime function calling pipeline.
What Is Realtime API Function Calling?
Realtime API function calling is defined as the ability of a streaming, multimodal AI model to invoke developer-defined tools during a live session, emitting structured call events over a persistent connection such as a WebSocket rather than returning tool requests in a completed text response. It works by declaring function schemas at session setup, streaming user audio or text into the model, and letting the model decide mid-conversation to emit a function call event that the client executes and answers within the same session.
The contrast with traditional function calling is the part most developers underestimate. In the classic async pattern, popularized by chat-completion APIs, your application sends a prompt, the model responds with a tool request, your code executes it, and you send everything back in a new request. Each round trip rebuilds context, reprocesses the conversation, and adds hundreds of milliseconds to seconds of latency. In the realtime pattern, the session persists, the model holds conversational state, and a function call is a lightweight event inside an already-open stream.
Three core components make this work. First, the persistent WebSocket connection, which carries audio, text, events, and function results bidirectionally. Second, voice activity detection (VAD), which decides when the user has finished speaking and a turn is complete. Third, the function schema, a structured declaration of available tools, their parameters, and their expected behavior, which the model consults whenever a user request might need external data or action.
VideoSDK provides realtime function calling through its open-source AI Agent SDK, where function tools and MCP integration let a Python agent worker execute developer-defined tools inside a live VideoSDK room, alongside built-in turn detection and voice activity detection.
Core Architecture Overview
The client-server flow follows a consistent lifecycle: authenticate and create a session, stream user audio in, let the model transcribe and reason, receive a function call event if a tool is needed, execute the function server-side, return the result, and stream the model's spoken response back out. The diagram below shows that full cycle.
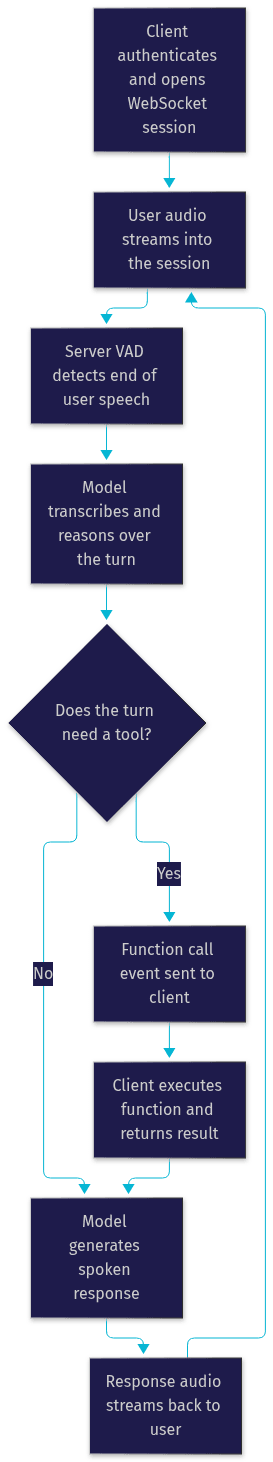
The critical property of this loop is that the session never tears down between turns. Context, audio buffers, and function schemas persist, which is why realtime function calling can hit response times that the request-response pattern physically cannot.
Setting Up a Realtime Session
Every realtime function calling deployment starts with session configuration, and the choices you make here determine your latency ceiling for the entire conversation. The setup sequence has three phases: authentication, connection, and session configuration.
Authentication should always happen server-side. Your API credentials grant access to billed, rate-limited infrastructure, so the standard pattern is a small backend service that validates your own users, requests a session or token from the realtime provider, and hands the connection details to the client. Never embed provider API keys in a browser or mobile bundle. VideoSDK applies the same principle: tokens are generated server-side using your API key and secret, as described in the authentication and token guide, and the same discipline applies to AI agent sessions.
Once authenticated, the client opens a persistent WebSocket connection to the realtime endpoint. This connection is the backbone for everything: inbound audio, outbound audio, transcription events, function call events, and session-level errors all travel over it. Treat it as long-lived infrastructure, with reconnect logic and heartbeat handling, not as a per-request resource.
The third phase is session configuration, typically done through a session update message sent immediately after connecting. This is where you declare the audio formats for input and output, choose your turn detection mode, set the voice and output instructions, and, most importantly for this article, register your function declarations. Getting this right up front matters because mid-session reconfiguration is possible but disruptive, and a poorly configured session is the most common source of avoidable latency.
For latency and reliability, a few settings consistently matter. Choose the narrowest audio format your pipeline supports, since transcoding adds delay on both sides. Prefer server-side turn detection over client-side silence heuristics unless you have a specific reason not to. Keep your output instructions concise, because every word of system context is processed on every turn. And declare only the functions the session actually needs, since a bloated tool list degrades both the model's tool-selection accuracy and its response speed.
Declaring Functions in the Session
Function declarations are structured descriptions of the tools your application offers. Each declaration gives the function a name, a plain-language description of what it does and when to use it, and a parameter schema that defines the inputs the model must supply when it invokes the tool.
The description field deserves more attention than developers usually give it. The model selects tools based on these descriptions, so a vague description like "gets data" produces erratic tool selection, while a specific one like "looks up the current delivery status of an order by order number, returns carrier, last scan event, and estimated delivery date" produces reliable invocation. Parameter schemas should declare types, mark required fields, and constrain values with enums or ranges wherever the domain allows, because a well-constrained schema is your first line of input validation.
The model discovers these functions entirely through the session declarations. There is no separate registration step, no runtime reflection. Whatever you declare at session setup (or via a later session update) is the complete tool surface the model can draw from, which makes the declaration list both your capability boundary and your security boundary.
Turn Detection and VAD Options
Turn detection decides when the user has finished speaking, and it directly controls when function calls get triggered. The three practical options are server VAD, semantic VAD, and custom client-side VAD.
Server VAD runs on the provider's infrastructure. It monitors the incoming audio stream for silence boundaries and emits an event when the user appears to have stopped talking. It is the lowest-friction option, requires no client logic, and its thresholds are usually tunable, letting you trade responsiveness against the risk of cutting off a user who pauses mid-sentence.
Semantic VAD goes further by reasoning about meaning, not just silence. Instead of ending a turn when the audio goes quiet, it evaluates whether the utterance seems semantically complete, which handles users who say "um", pause, and continue. It reduces false turn endings at the cost of slightly more processing on the provider side.
Custom VAD moves detection into your client or backend, giving you full control over thresholds, barge-in handling, and interruption behavior. It is the right choice when you have unusual audio conditions, need offline detection, or want tight integration with your own interruption UX. The tradeoff is that you now own the correctness of turn boundaries, and a bad custom VAD is worse than a good default one.
Whichever mode you choose, the function call trigger follows from it: the model only reasons about tools once a turn boundary is detected, so VAD latency is function calling latency.
How Function Calls Are Triggered in Real Time
A typical conversation turn proceeds through a well-defined sequence, and understanding each stage is essential for diagnosing latency. The user speaks, and their audio streams into the session while a transcription runs in parallel, producing incremental text. When turn detection fires, the model reasons over the complete utterance in the context of the session history and the declared function list.
If the model decides a tool is needed, it emits a function call event containing the function name and the arguments it has inferred, structured according to your declaration schema. This event arrives on the client side of the WebSocket. Your application is now responsible for executing the actual work, whether that is querying a database, calling a third-party API, or running internal logic.
When execution finishes, your client sends the result back through the session as a function call output message. The model incorporates that result and generates its spoken response, which streams out as audio. From the user's perspective, the whole cycle should feel like a natural conversational pause, typically well under a second for fast tools.
Latency considerations cluster around three points. The turn detection boundary adds a fixed cost that you control through VAD configuration. The model's reasoning time over the utterance and tool list scales with context size, which is why trimming system instructions and tool descriptions pays off. And your function execution time is entirely yours, which is why the next section treats handler engineering as a first-class concern.
Error handling deserves explicit design. If your function throws, times out, or returns an error payload, do not silently drop the result, because the model is waiting for it and the session will stall or hallucinate a response. Always return a structured error message so the model can apologize, offer an alternative, or ask the user for clarification. A tool that fails gracefully produces a better conversation than a tool that fails silently.
Handling Asynchronous vs. Blocking Calls
Realtime sessions support non-blocking function call behavior, where the model can continue generating speech or even handle other events while a long-running tool executes in the background. This matters for tasks that cannot complete in a conversational pause: generating a document, running a multi-step workflow, or querying a slow backend.
With non-blocking calls, your client acknowledges the function call, starts execution, and delivers the output later, when the result arrives the model weaves it into the ongoing conversation. Cancellation is the companion capability: if the user interrupts or the conversation moves on, you can cancel an in-flight call rather than wasting resources on a result nobody will use.
The practical guidance is simple. Use blocking-style, fast-returning functions for lookups and quick queries where sub-second execution is achievable. Use non-blocking calls with explicit cancellation for anything that might take more than a couple of seconds, and design your spoken responses to bridge the gap, telling the user their request is being processed rather than leaving dead air.
Implementing Function Logic
Robust function handlers are where realtime function calling succeeds or fails in production. The handler is ordinary server-side code, but it operates under constraints that traditional request handlers do not face: strict latency budgets, conversational error recovery, and a model that will faithfully pass along whatever you return.
Start with input validation at the boundary. The model infers arguments from user speech, which means arguments can be wrong, incomplete, or subtly malformed in ways a human caller's input would not be. Validate every parameter against the declared schema, reject impossible values, and return a structured, model-readable error when validation fails so the model can ask the user a clarifying question instead of guessing.
For external API calls, apply the standard production disciplines with extra rigor. Set aggressive timeouts matched to your latency budget, because a slow upstream API silently destroys the conversational experience. Cache aggressively where the domain allows, since voice conversations frequently repeat the same lookups, and a cache hit turns a 400-millisecond tool into a near-instant one. Respect rate limits on your upstream providers, and implement backoff so a burst of conversational tool calls does not get your credentials throttled.
Security belongs in the handler, not just at the edge. Never let a function handler execute with credentials that exceed what the function needs, and never trust the model's inferred arguments as authorization, since a user saying "check order 55" is not proof they own order 55. Validate identity and permissions inside the handler against your own session context.
Two further practices separate reliable deployments from fragile ones. Idempotency matters because realtime sessions can retry or duplicate function call events during reconnection, so design handlers so that executing the same call twice produces the same result rather than a duplicate side effect like a double order placement. Graceful degradation means every handler has a defined fallback path, a cached answer, a default response, or an honest error message, so no single tool failure can stall the conversation.
Example Use Cases
The use cases that showcase realtime function calling best are ones where the answer cannot be static. A weather lookup agent converts a spoken city name into a live forecast query and speaks the result in the same breath. An order status agent for an e-commerce or delivery platform takes an order number from speech, checks the fulfillment system, and reads back the carrier and estimated delivery date. A knowledge-base retrieval agent performs real-time RAG, turning a user question into a vector search and feeding the retrieved passages back for the model to answer from.
Dynamic content generation rounds out the picture: an agent that drafts a personalized offer, generates a summary document, or produces a tailored recommendation mid-conversation, using non-blocking calls for anything slow. These patterns map directly onto VideoSDK's function tools and agent capabilities, where a Python agent worker executes tools inside a live room for web, mobile, and phone-based users.
Monitoring, Debugging, and Optimization
You cannot optimize what you cannot measure, and realtime sessions generate exactly the telemetry you need if you instrument them. The metrics that matter most are per-stage latency, token and audio usage, and function call success rates.
Per-stage latency is the headline metric. Break the loop into measurable segments: time from speech end to turn detection, from turn detection to function call event, from event to your function result, and from result to first response audio. Logging each segment separately tells you whether your problem is VAD configuration, model reasoning, tool execution, or output generation, and without that breakdown you will optimize the wrong stage.
Token usage and audio quality round out the operational picture. Realtime sessions bill on both audio and text tokens, and sessions with long histories or verbose instructions accumulate cost quietly. Audio quality metrics, including dropped frames and reconnect frequency, reveal network problems that manifest as conversational lag before they manifest as errors.
Function call success rate is your reliability signal. Track the ratio of calls that return valid results within budget versus those that time out, error, or get cancelled, and alert on degradation. A tool whose success rate quietly drops from 99 percent to 80 percent is failing your users long before anything crashes.
For scaling, treat each WebSocket as a stateful, long-lived resource. Plan connection limits, load distribution across agent workers, and graceful session migration. VideoSDK's agent architecture addresses this directly: the agent worker model runs each session as a managed Python process, with observability hooks for pipeline events, and can be deployed on VideoSDK Agent Cloud or self-hosted with Docker or Kubernetes.
When things go wrong, the error handling path should be explicit rather than improvised. The flowchart below shows a disciplined decision path for a failing function call.
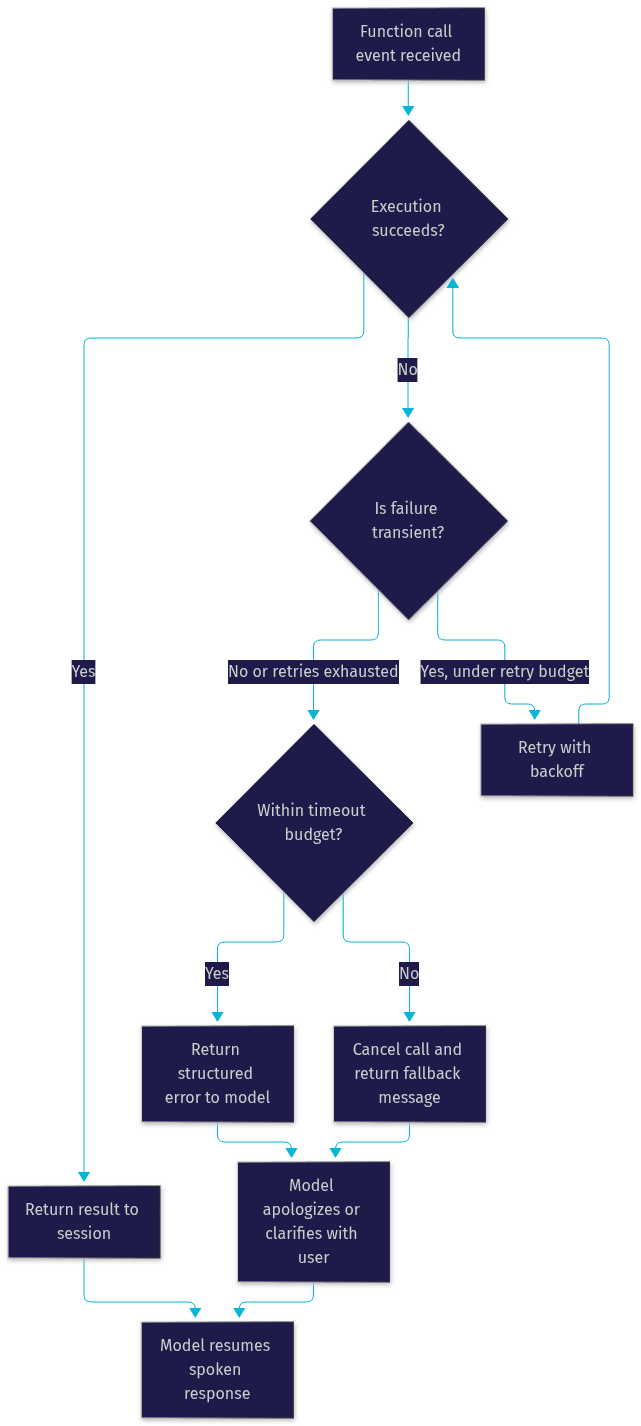
The principle behind the flowchart is that every failure path ends with the model receiving something it can speak about. Retry transient failures within a tight budget, time out everything else, and always deliver a structured outcome so the conversation continues.
Security and Compliance Considerations
Realtime function calling multiplies your security surface, because it combines live audio streams, persistent connections, and executable tools in one pipeline. Authentication best practices start with server-side credential handling and short-lived session tokens, so a compromised client cannot open unlimited billed sessions. Scope each session's function declarations to the minimum tool set that conversation needs, since an undeclared function cannot be invoked.
Data privacy for audio streams deserves specific attention. Live speech is biometric-adjacent personal data in most jurisdictions, so know where your realtime provider processes and retains audio, configure retention to the minimum, and disclose recording and transcription to users where required. If your deployment handles regulated conversations in healthcare or finance, verify regional processing and encryption guarantees before routing audio to any third-party model provider.
Safe handling of function outputs is the piece teams most often miss. Whatever your handler returns is spoken aloud and treated as authoritative by the model, so never return raw database rows, internal error stacks, or other users' data. Sanitize outputs to exactly what the conversation needs. And treat model-inferred arguments as untrusted input, validating identity and authorization inside every handler, because a persuasive voice is not an authentication factor.
Future Trends and Emerging Features
The realtime function calling landscape is moving quickly, and three trends are worth tracking as you architect for 2026 and beyond. Proactive audio, where the agent initiates speech or actions without an explicit user turn, is expanding function calling from reactive to agentic, enabling agents that monitor conditions and reach out. Multimodal inputs are broadening beyond voice, with vision and screen context feeding tool decisions, so a function call can be triggered by what the agent sees as well as what it hears. And cross-provider realtime APIs are emerging as a real pattern, with multiple vendors offering streaming speech-to-speech endpoints, making provider-agnostic agent frameworks increasingly valuable.
That last trend is where architecture choices made today pay off. VideoSDK's open-source agent SDK is explicitly designed around pluggable providers, supporting real-time models from OpenAI, Google, and AWS alongside interchangeable STT and TTS providers, so your function calling layer can survive individual model vendors changing, deprecating, or repricing. Building your tool layer against a portable abstraction rather than a single vendor's session format is the durable move.
Definitions Glossary
Realtime API function calling: The mechanism by which a streaming AI model invokes developer-defined tools mid-conversation over a persistent connection, emitting structured call events instead of returning tool requests in completed responses.
WebSocket session: The long-lived bidirectional connection that carries audio, text, events, and function results between the client and the realtime model, persisting across multiple conversation turns.
Voice Activity Detection (VAD): The mechanism that determines when a user has started and stopped speaking, defining turn boundaries that control when the model reasons about and triggers function calls.
Function declaration: The structured schema, consisting of a name, description, and parameter definitions, registered at session setup, through which the model discovers and invokes available tools.
Non-blocking function call: A function call mode where the model continues generating speech or handling events while a long-running tool executes, with the result delivered later and cancellation supported.
Agent Worker: In VideoSDK's architecture, the Python process that runs an AI agent, manages its session lifecycle, and executes function tools inside a live VideoSDK room.
Key Takeaways
- Realtime API function calling moves tool invocation inside a persistent streaming session, eliminating the request-response round trips that make traditional function calling too slow for voice.
- Turn detection is the hidden latency gate: the model only reasons about tools after a turn boundary, so your VAD configuration directly controls responsiveness.
- Function declarations are both a capability boundary and a security boundary, so declare only what a session needs and write descriptions precise enough for reliable tool selection.
- Robust handlers validate model-inferred arguments, enforce authorization internally, cache aggressively, and always return a structured outcome so no failure stalls the conversation.
- VideoSDK's open-source AI Agent SDK implements this full pattern with pluggable STT, LLM, and TTS providers, function tools, MCP integration, and managed or self-hosted deployment.
Conclusion
Realtime API function calling is the difference between a voice agent that feels conversational and one that feels like a form with a microphone attached. The architecture is now well understood: persistent sessions, server-side turn detection, well-constrained function schemas, and handlers engineered for latency, idempotency, and graceful failure. Teams that instrument per-stage latency and treat tool reliability as a first-class metric are the ones shipping voice experiences users actually tolerate.
If you want to see this pattern running end to end, start with the VideoSDK AI Agents documentation, explore the open-source agent SDK on GitHub, and try the free tier by signing up at app.videosdk.live/login. What are you building with realtime function calling? Drop a comment, I'd love to hear what kind of voice agent use case you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ