


The OpenAI Stream API is a mode of the chat completions endpoint that delivers model output token-by-token over a persistent HTTP connection using server-sent events (SSE), instead of waiting for the full response to finish. This cuts perceived latency from several seconds to a few hundred milliseconds for the first visible output. This article explains the mechanics, integration patterns, cost behavior, and error handling in plain language, with no code snippets required to follow along. If you want to ship streaming AI features into a production app, the VideoSDK real-time communication docs cover the broader real-time stack this fits into.
Real-time AI output has become a baseline expectation for modern applications. When a chatbot pauses for five seconds before answering, users perceive it as broken, even when the underlying model is fast. Streaming solves the perception problem: the moment the model produces its first token, the user sees it.
The OpenAI Stream API is the gateway to that token-by-token delivery. It is not a separate product but a mode you enable on the standard chat completions request, which changes the response from a single JSON document into a live sequence of small JSON chunks pushed over the connection as the model generates text.
This article focuses on concepts rather than syntax. You will learn how the streaming mechanism works under the hood, how server-sent events are structured, how front-end frameworks and edge runtimes consume the stream, and how to manage cost, errors, and security. By the end, you will understand the full streaming pipeline well enough to design, debug, and optimize it in your own product.
How the OpenAI Stream API Works
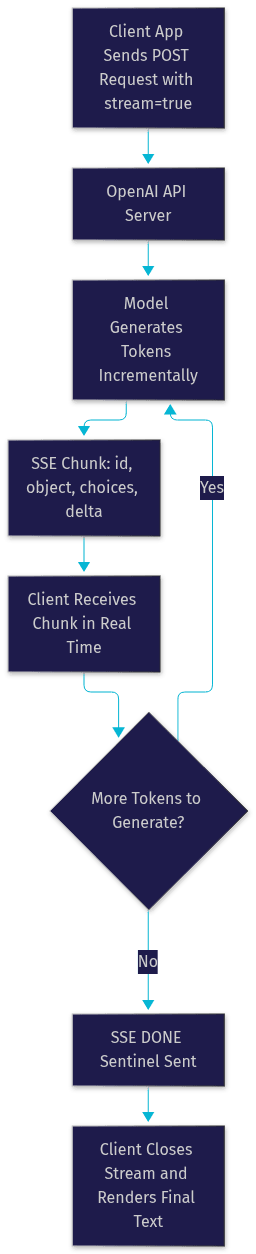
The OpenAI Stream API works by keeping a single HTTP POST connection open while the model generates its answer, pushing each fragment of the response to the client the instant it is produced. Under normal (non-streaming) behavior, the client sends a request, the model computes the entire completion, and only then does the server return one complete JSON payload. With streaming enabled, the same request returns a live channel of incremental updates instead.
The mechanics are straightforward. Your server sends the usual chat completions request to OpenAI, with the streaming flag set to true. OpenAI responds with a content type of text/event-stream, which is the standard server-sent events (SSE) format. The connection stays open, and OpenAI writes a series of small JSON objects to it, one per generation step. Each object is a self-contained chunk describing what changed since the previous chunk, typically a few characters or a single token of new text.
Each chunk carries a consistent structure: an identifier for the response, an object type marking it as a chat completion chunk, a creation timestamp, the model that produced it, a choices array containing a delta (the new content since the last chunk), and, when requested, a final usage block with token counts. The stream terminates with a special sentinel value rather than closing silently, so the client always knows the response is complete.
The overall flow looks like this:
The Role of Chunked Responses
Chunking is what makes streaming feel instant. Instead of one large payload arriving after full generation, the response is split into discrete chunks, each delivered the moment it exists. The first chunk typically arrives within a few hundred milliseconds, so the user starts reading while the model is still writing.
Chunked delivery also improves resilience. If the connection drops mid-response, the client has already received and rendered everything up to the failure point, and can display a partial answer rather than nothing at all. For long generations, this partial-output property is a genuine UX advantage over the all-or-nothing batch mode.
Enabling Streaming in Your Requests
Enabling streaming in the OpenAI API is a matter of toggling a single boolean flag on the chat completions request. The core parameters remain the same as non-streaming mode: the model identifier, the messages array describing the conversation, and the streaming flag itself. An optional stream options object lets you request token usage metrics to be included in the final chunk, which matters for cost tracking and will be covered in the performance section.
Because the flag is a single boolean, you can toggle streaming on and off per request. That flexibility is useful in practice: streaming for interactive chat interfaces, batch mode for background jobs where latency does not matter and a single complete JSON object is easier to process.
A few best-practice defaults are worth adopting. Keep temperature at a moderate value unless your use case specifically needs more or less randomness, because extreme values increase the chance of rambling, expensive completions. Set a sensible maximum token limit so a runaway generation cannot silently inflate your bill. And enable usage reporting in the stream options so every response ends with an accurate accounting of prompt and completion tokens.
One thing that catches teams out: streaming responses cannot be retried as a whole the way batch responses can. If a stream fails at chunk forty of a hundred, you must decide whether to resume, regenerate, or show partial output. Designing for that decision up front saves pain later.
Understanding Server-Sent Events (SSE)
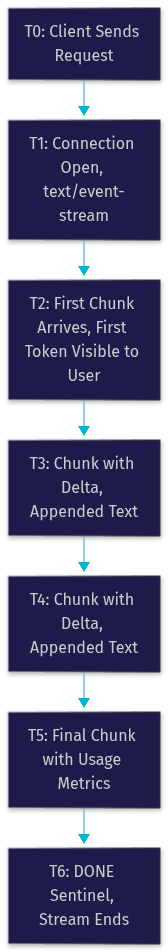
Server-sent events are a long-standing web standard for pushing text updates from a server to a browser over a plain HTTP connection. SSE is defined by the browser's event-source mechanism and uses a content type of text/event-stream. Each update is a line beginning with a data prefix, followed by the JSON payload for that chunk. The OpenAI Stream API uses a sentinel data line containing the word DONE to signal that no more chunks are coming, after which the server closes the connection.
SSE contrasts with two alternatives. WebSockets provide a full-duplex, bidirectional channel, which is more powerful but also more complex to provision, proxy, and authenticate. Long polling repeatedly opens new requests to simulate push behavior, wasting connections and adding latency. SSE sits in the middle: unidirectional (server to client), trivially compatible with existing HTTP infrastructure like proxies and CDNs, and automatically reconnecting in native browser implementations.
For OpenAI's use case, SSE is the right fit because the data flow is fundamentally one-directional during generation: the client asked a question, and the server pushes the answer. There is no need for the client to send anything mid-stream, so the simplicity of SSE wins over WebSocket overhead.
A typical stream timeline looks like this:
Integrating the Stream API with Front-End Frameworks
Integrating the OpenAI Stream API with a front-end is really two integrations: your client talks to your own backend, and your backend talks to OpenAI. The API key must live server-side, so the browser never streams directly from OpenAI. Your backend acts as a secure proxy that forwards the stream to the client while it arrives.
Edge functions are the preferred hosting layer for this proxy in 2026. Vercel Edge Functions and Cloudflare Workers both support streaming response bodies natively, run close to users at the network edge, and have minimal cold-start times. Because streaming is latency-sensitive, the difference between an edge runtime near the user and a central Node server can be a noticeable fraction of a second on first-token time.
On the browser side, the stream is consumed through the standard web streams interface. The fetch response exposes a readable body, and the client reads it incrementally, parsing each data line as it arrives and appending the delta text to the interface. The key UI patterns that make this feel polished are incremental text display (appending each delta as it lands), a loading placeholder before the first chunk arrives, and scroll-aware rendering that keeps the newest text visible without hijacking the user's scroll position.
Next.js API routes deserve a specific mention because they are the most common deployment pattern for this architecture. A Next.js route can receive the browser request, open the upstream OpenAI stream, and pipe it straight back to the browser. The same pattern works in any framework with streaming response support, including Remix, SvelteKit, and plain Node servers.
Edge vs. Node Runtime Considerations
Edge runtimes generally beat traditional Node servers on cold-start time and geographic proximity to users, both of which directly affect first-token latency. Node runtimes win on ecosystem compatibility: some libraries and native dependencies only run in Node, and long-lived connections with heavy processing can be cheaper there.
Environment variable handling also differs. Edge platforms typically expose secrets as simple string bindings, while Node servers may use richer configuration. Whichever runtime you choose, the principle is the same: the OpenAI key is injected server-side and never shipped to the browser bundle.
Performance and Cost Optimization
Streaming does not change how you are billed. OpenAI charges per token, and a streamed response costs exactly the same as the identical response delivered in batch mode. What streaming changes is when tokens arrive, not what they cost. This is a common misconception worth correcting early with stakeholders.
The most valuable cost feature is usage reporting in the stream options. When enabled, the final chunk of every stream carries a usage block with exact prompt and completion token counts. Without it, streamed responses historically gave you no usage data at all, forcing teams to estimate costs from character counts. With it, you can log precise per-request costs, build dashboards, and alert on anomalies.
Beyond measurement, the standard levers apply. Set a maximum token limit on every request so a degenerate generation cannot run away. Keep prompts concise, because prompt tokens are billed on every request even though they are never displayed to the user. For repeated or near-identical queries, cache the completed response and serve it instantly, skipping the model call entirely. Semantic caching, where similar prompts hit a stored answer, can cut a surprising amount of spend in production chat applications.
Finally, consider model tiering. Route simple queries to smaller, cheaper models and reserve the flagship models for complex reasoning. Streaming works identically across tiers, so users see no difference in responsiveness while your bill shrinks.
Error Handling and Retry Strategies
Streaming errors come in two flavors: errors before the stream starts, and errors during the stream. Before the stream starts, you get normal HTTP status codes. A 401 means your API key is invalid or expired. A 429 means you have hit a rate limit, and the response headers tell you when to retry. A 500-series error means something failed on the provider side. These behave exactly like non-streaming errors and are handled at the request level.
Errors during the stream are trickier. The connection is already open, the client is already rendering text, and then a chunk arrives that is not a normal delta. Your consumption logic needs to inspect each chunk: if it carries a delta, append it; if it is the DONE sentinel, finish cleanly; if it contains an error object, surface it gracefully. A robust client treats any of those three shapes as first-class cases rather than assuming every chunk is content.
For retries, exponential backoff is the standard pattern: wait a short interval, retry, and double the wait on each consecutive failure, up to a cap. Apply backoff to connection failures and 429 responses, but be careful about retrying mid-stream failures, because regenerating means paying for the tokens already produced and shown to the user.
For the UI, graceful fallback matters as much as the retry logic. If a stream dies at 80 percent complete, showing the partial answer with a subtle indicator that generation was interrupted is far better than wiping the text and showing a spinner. Users forgive an incomplete answer; they do not forgive a disappearing one.
Security and Privacy Best Practices
The single most important security rule: your OpenAI API key never reaches the browser. Every streaming architecture in this article assumes a server-side proxy that holds the key and forwards the stream. A key exposed in client-side code, even obfuscated, is a key that will be extracted and abused, and usage-based billing means the abuse shows up on your invoice.
Respect rate-limit headers. OpenAI returns headers describing your current limit, remaining requests, and reset time. Reading these lets your backend throttle proactively instead of discovering limits through 429 errors, and lets you implement user-level quotas so one heavy user cannot consume your entire allocation.
On privacy, sanitize user prompts before they leave your system. Strip identifiers, emails, and account numbers from prompts where they are not needed for the answer. Be deliberate about data retention settings on your OpenAI organization, and disclose to users how their inputs are processed. For regulated domains like healthcare or legal, this sanitization step is not optional.
Comparison with Other Provider Streaming APIs
OpenAI is not the only provider with streaming, and the differences matter if you are designing a multi-provider abstraction. Anthropic's streaming API also uses server-sent events, with a similar chunked structure, but its event types distinguish message start, content block deltas, and message stop, giving you slightly more structural signal about where you are in the response. Cohere likewise streams over SSE but organizes its events around generation stages rather than a flat delta sequence.
OpenAI's distinguishing features are its usage metadata in the final chunk when requested, its consistent delta-based chunk shape across model generations, and its broad ecosystem support, since nearly every framework and library in the space handles the OpenAI stream format first. If you are building a provider-agnostic layer, the OpenAI delta pattern is a sensible normalization target because it is the most widely imitated.
Future Trends and Roadmap
Streaming AI output is still evolving. Multi-modal streaming, where text, image, and audio tokens interleave in a single response, is the clear next step as models become natively multimodal. Real-time voice models already stream audio tokens directly, blurring the line between a completion API and a live media channel.
Fine-grained control is also coming: expect more developer influence over chunking granularity, mid-stream steering, and richer per-chunk metadata. For teams building live voice or video experiences on top of streaming models, platforms like VideoSDK's AI voice agents already combine streaming model output with real-time transport, a preview of where the whole stack is heading.
Definitions Glossary
Server-Sent Events (SSE): A web standard for pushing text updates from a server to a browser over a single HTTP connection, using the text/event-stream content type. The OpenAI Stream API delivers its chunks in this format.
Delta: The incremental content carried by each streaming chunk, representing only the new text generated since the previous chunk. Clients append deltas to build the full response.
DONE Sentinel: The special final data line in an OpenAI stream that signals generation is complete and no further chunks will arrive.
Usage Metrics: Token counts for prompt and completion, delivered in the final chunk when usage reporting is enabled in the stream options. Essential for accurate cost tracking of streamed responses.
Edge Function: A serverless function executed at the network edge close to the user, such as Vercel Edge Functions or Cloudflare Workers. Its low cold-start time makes it well suited for proxying latency-sensitive streams.
Exponential Backoff: A retry strategy that doubles the wait interval between consecutive failed requests, preventing overwhelmed servers from being hammered with immediate retries.
Key Takeaways
- The OpenAI Stream API delivers model output token-by-token over server-sent events, cutting perceived latency from seconds to a few hundred milliseconds for first visible output.
- Streaming is enabled with a single boolean flag on the standard chat completions request, and each chunk carries an identifier, the model, a choices array, and a delta of new content.
- Streaming costs exactly the same as batch mode per token; enabling usage reporting in the stream options is what gives you precise per-request cost visibility.
- Always proxy streams through a server-side layer (ideally an edge function) so the API key never reaches the browser, and handle the three chunk shapes: delta, DONE sentinel, and error payload.
- Graceful partial-output handling and exponential backoff are the difference between a streaming UI that feels resilient and one that breaks visibly.
Conclusion
The OpenAI Stream API turns AI generation from a waiting game into a live experience. By understanding how server-sent events carry chunked deltas, how edge runtimes and browser stream consumption fit together, and how token billing and usage metrics work, you can build streaming interfaces that are fast, cost-aware, and resilient to failure. The concepts here pair naturally with broader real-time features, and if your product also needs live video, audio, or interactive streaming, explore the VideoSDK quickstart guides and grab a free tier at app.videosdk.live/login to experiment. What are you building with streaming AI responses? Drop a comment, I'd love to hear what kind of real-time experience you're working on.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ