


Google speech recognition is Google's family of speech-to-text technologies that convert spoken audio into text using neural network models, available as cloud APIs (Cloud Speech-to-Text and Gemini Transcribe) and on-device recognizers (Gboard voice typing). It supports more than 85 languages, real-time streaming transcription, speaker diarization, and automatic punctuation. If you're building voice features, start by choosing the right service tier, then follow the official Google Cloud Speech-to-Text docs or explore real-time transcription inside VideoSDK rooms.
Voice interfaces have quietly become the default way millions of people interact with software. Gboard alone processes billions of voice-typed queries, and every major product category, from call center analytics to live captioning, now depends on accurate speech-to-text. Google's speech recognition stack is one of the most widely deployed in the world, and in 2026 it spans everything from tiny on-device neural models to massive cloud transformers.
That breadth is exactly why it confuses developers. Google currently offers multiple speech services with overlapping capabilities, different pricing models, and different latency profiles. Picking the wrong one means overpaying, shipping laggy UX, or fighting quota limits in production. This guide walks through the full landscape: how the technology works, which service fits which use case, how to authenticate and integrate, and how to tune accuracy and cost.
Understanding Google Speech Recognition
Google speech recognition is defined as the set of machine learning systems Google uses to convert spoken audio into machine-readable text, spanning on-device recognizers, cloud APIs, and multimodal foundation models. It works by feeding raw or encoded audio into neural networks that have been trained on enormous corpora of human speech, producing text output with confidence scores, timestamps, and optional metadata like speaker labels.
The landscape has three distinct layers. The legacy Google Speech API was the original cloud offering, now largely superseded. Google Cloud Speech-to-Text (currently on its v2 API surface) is the production-grade service most teams integrate today, with dedicated models for short audio, long-form transcription, phone audio, and command-and-control use cases. The newest entrant is Gemini Transcribe, a multimodal model family that handles transcription as part of a larger understanding pipeline, supporting long context windows, multilingual switching, and richer output formatting.
There's also the on-device recognizer that powers Gboard voice typing, which runs entirely on the phone without sending audio to Google's servers. Each layer makes different trade-offs between latency, privacy, cost, and accuracy, and the rest of this guide helps you navigate those trade-offs.
How the Technology Works
Modern Google speech recognition is built on end-to-end neural networks rather than the older pipeline of separate acoustic and language models. This architectural shift is the single biggest reason accuracy has improved so dramatically over the past decade.
Neural Models Behind the Service
An end-to-end neural network takes audio features directly as input and produces text tokens as output, learning the entire mapping in one trainable system. Google's research has heavily featured the RNN-T (Recurrent Neural Network Transducer) architecture, which processes audio as a continuous stream rather than fixed-length chunks. RNN-T models emit text incrementally as speech arrives, which makes them ideal for streaming recognition where you need partial results before the speaker finishes a sentence.
Newer Gemini-class transcription models extend this with transformer-based architectures that can attend over much longer audio contexts, improving handling of long conversations, code-switching between languages, and domain-specific vocabulary. Cloud inference runs these large models on Google's serving infrastructure, while on-device variants are aggressively compressed and quantized so they fit within a few hundred megabytes and run in real time on mobile silicon.
Streaming vs. Batch Processing
Streaming speech recognition opens a persistent, bidirectional connection to the service. Audio flows in continuously, and the recognizer sends back interim (partial) hypotheses that get refined as more context arrives, followed by a final result when the utterance ends. This is what powers live captioning and voice assistants, where sub-second feedback matters.
Batch processing, by contrast, submits a complete recorded file for transcription. The service processes the whole file and returns the final transcript, typically with better accuracy because the model can use full-file context, and at a lower price point. Use batch for call recordings, meeting archives, and media asset workflows where latency doesn't matter.
On-Device vs. Cloud Deployment
On-device recognition, like the recognizer inside Gboard, keeps audio entirely on the hardware. Latency is minimal because there's no network round trip, privacy is stronger because nothing leaves the device, and it works offline. The trade-off is a smaller model with lower accuracy on noisy or accented speech, and limited language coverage.
Cloud recognition offers the largest models, the best accuracy, and the richest feature set (diarization, custom vocabularies, multilingual detection), at the cost of network latency, per-minute pricing, and data leaving the device. For most production applications, a hybrid pattern works well: on-device for wake words and simple commands, cloud for full transcription.
Key Features and Capabilities
Google's speech services expose a feature set that goes well beyond raw transcription. These capabilities often determine which service you actually need.
Language and Multilingual Support
Cloud Speech-to-Text supports more than 85 languages and regional variants, and newer model generations add automatic language detection, where the recognizer identifies the spoken language on the fly. Multilingual transcription handles speakers who switch languages mid-utterance, a common scenario in support calls across multilingual regions.
Real-Time Transcription and Partial Results
Streaming recognition returns interim results as the user speaks, so your UI can display text character-by-character and refine it live. This low-latency feedback loop is what makes voice typing and live captions feel responsive. Final results arrive once the recognizer detects an end-of-utterance, giving you the polished version to persist.
Speaker Diarization and Timestamps
Diarization separates a multi-speaker recording into per-speaker segments, labeling which words belong to which participant. Combined with word-level timestamps, you can build meeting minutes, call analytics, and searchable transcripts. Diarization is available on the long-form and newer model tiers, and it pairs naturally with real-time communication platforms like VideoSDK's real-time transcription, where each participant's audio track can be transcribed and attributed separately.
Automatic Punctuation and Smart Formatting
Modern models insert punctuation, capitalization, and formatting automatically, converting raw hypothesis strings into readable text. Filler words like "um" and "uh" can be filtered, numbers are formatted appropriately, and profanity filtering is configurable. This post-processing dramatically reduces the cleanup work your application would otherwise need.
Choosing the Right Google Speech Service
The decision comes down to three questions: does latency matter, does audio need to leave the device, and how long is the audio? The matrix below maps the three main options to their strongest use cases.
| Service | Best For | Latency | Pricing Model | Key Limitation |
|---|---|---|---|---|
| Cloud Speech-to-Text (v2) | Production transcription, call analytics, captioning | Low (streaming) to minutes (batch) | Per minute, tiered by model | Streaming session limits |
| Gemini Transcribe | Long-form, multilingual, context-rich transcription | Near real-time | Per minute / token-based | Newer surface, evolving API |
| On-device recognizer (Gboard-style) | Voice typing, offline commands, privacy-first apps | Instant | Free (no API cost) | Lower accuracy, limited languages |
[LINKABLE ASSET — decision matrix]
Use Cloud Speech-to-Text when you need reliable, well-documented production transcription with mature SDKs. Use Gemini Transcribe when your audio is long, multilingual, or benefits from a model that understands broader context. Use on-device recognition when audio must never leave the hardware or when you need offline support.
Setting Up Authentication and Access
Before any API call succeeds, you need a Google Cloud project with billing enabled and the correct credentials. Getting this right up front prevents the most common integration failures.
Enabling the API
Start in the Google Cloud Console by creating (or selecting) a project, then enable the Speech-to-Text API from the API library. Confirm billing is active, since the service has no sustained free usage without a billing account, though a monthly free tier applies to initial usage. From there, you can test recognition directly in the console's interactive tool before writing any integration code.
API Key vs. Service Account
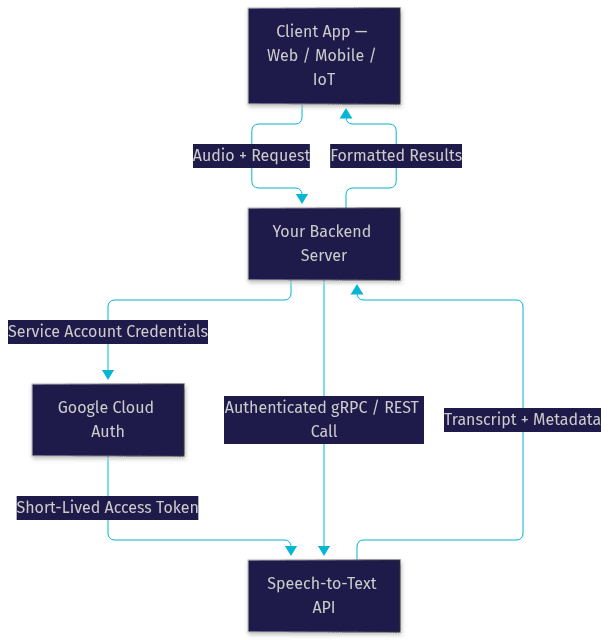
An API key is a simple string identifier, appropriate for prototyping and for client-side calls where you've restricted the key by API, referrer, or IP. A service account is a machine identity with a JSON key file, appropriate for all server-side integrations. The security rule is simple: never embed a service account key in a client application or public repository. Server-side, prefer attaching the service account to the compute workload itself (Compute Engine, Cloud Run, GKE) so no key file exists at all. For production apps that transcribe calls inside a real-time communication session, generate short-lived credentials on your backend, the same pattern VideoSDK uses for token-based authentication in its SDKs.
Authentication Flow Diagram
The flow below shows how a typical production setup keeps credentials server-side while the client talks only to your own backend.
Integration Approaches
Google exposes two API surfaces, and choosing between them shapes your entire integration. Both are covered by official client libraries for Node.js, Python, Java, and Go.
REST Endpoint Overview
The REST interface works on a request-response model. You send a request containing configuration (language code, model selection, encoding details, optional features like diarization or punctuation) plus the audio itself, either embedded directly for short clips or referenced as a Cloud Storage URI for longer files. The response returns a transcript with confidence scores and, depending on configuration, word-level timing and speaker labels. REST is the right choice for batch workloads, simple server-side scripts, and environments where gRPC isn't practical. It's simpler to debug, works with any HTTP tooling, and handles files up to the documented size limits when audio is passed via Cloud Storage.
gRPC Streaming Overview
gRPC is the interface for real-time recognition. It opens a bidirectional streaming session: your client pushes audio chunks continuously while the service pushes back interim and final results on the same connection. The session has a lifecycle, starting with an initial configuration message, continuing with audio frames, and ending either when you close the stream or when the service's streaming time limit is reached. Partial results arrive as the recognizer refines its hypothesis, and your application decides whether to display them live or wait for finals. This is the architecture behind live captioning, voice assistants, and real-time transcription overlays in video calling apps. For teams building live transcription into meetings, VideoSDK's real-time transcription capabilities handle this streaming complexity inside the SDK so you consume finished transcript events instead of managing raw streams.
SDK Landscape (Node.js, Python, Java, Go)
Google publishes first-party client libraries for all four major server languages. The Python and Node.js libraries are the most commonly used for speech workloads and follow the same high-level pattern: construct a client with credentials, build a recognition configuration, then either call a one-shot method for batch audio or open a streaming session for live audio. Java and Go libraries cover the same surface for teams standardized on those stacks. All libraries handle authentication, retry logic, and connection management, so prefer them over hand-rolled HTTP calls. For Python teams building AI voice pipelines, VideoSDK's Python SDK integrates cleanly alongside these Google clients for connecting transcription to live media sessions.
Best Practices for Accuracy and Performance
Accuracy is mostly determined before the audio reaches the model. These practices consistently separate high-performing integrations from frustrating ones.
Audio Format and Sample Rate
Use 16 kHz, 16-bit PCM mono for speech recorded from microphones and voice calls. This matches the sample rate the speech models were trained on for telephony and voice scenarios, and mismatched sample rates are a leading cause of degraded accuracy. For media files recorded at higher rates, either downsample to 16 kHz or use a model tier that handles the native rate. Always declare the encoding and rate accurately in your request configuration rather than relying on auto-detection where it's unsupported.
Noise Suppression and VAD
Improve the signal before it reaches the recognizer. Apply noise suppression on the capture side, use a headset or directional mic where possible, and implement voice activity detection so you only stream audio when someone is actually speaking. VAD cuts cost (you're not paying to transcribe silence), reduces false positives, and improves the recognizer's end-of-utterance detection. Many real-time platforms, including VideoSDK's SDKs, ship built-in noise suppression and voice activity detection you can enable at the media layer before transcription ever runs.
Managing Latency and Throughput
For streaming sessions, keep audio chunks small and evenly paced so the recognizer can emit partial results promptly. Design for reconnection: streaming sessions have a maximum duration, so implement a seamless restart that carries context across the boundary. For batch workloads, parallelize across multiple requests rather than sending one giant job, and prefer the cheaper batch model tier when latency tolerance allows. Monitor quota usage and set up alerts before you hit per-minute rate limits in production.
Common Pitfalls and Troubleshooting
Every team integrating Google speech recognition hits at least one of these. Knowing the cause saves hours.
403 Errors and Quota Limits
A 403 typically means the API isn't enabled on the project, the credential lacks the correct scope or role, or you've exceeded a quota. Check that the Speech-to-Text API is enabled, that the service account has the appropriate IAM role, and review the quotas page in the console. If you're hitting sustained rate limits, request a quota increase rather than implementing aggressive retry loops, which can make throttling worse.
Streaming Session Timeouts
Streaming recognition sessions have a maximum duration (around five minutes on standard tiers). Long-running applications must detect the session ending and open a new stream, ideally mid-utterance so no audio is lost at the boundary. Buffer a few seconds of audio across the reconnect and deduplicate the overlapping transcript on your side.
Language Code Mismatches
Specifying the wrong locale identifier, or omitting it when auto-detection isn't enabled, produces garbled or empty transcripts. Always send the exact BCP-47 style language code matching the spoken audio, and for multilingual audio, use a model tier that supports language detection rather than forcing a single locale.
Cost and Pricing Overview
Google prices speech recognition per minute of audio processed, with rates varying by model tier and feature set. Standard recognition models cost less; premium and long-form models with diarization cost more. Data logging also matters: if you opt in to allow Google to use your audio to improve its models, you get a discounted rate, which is a meaningful cost lever for non-sensitive workloads. A monthly free tier covers initial usage at no cost.
Cost-saving tactics: use batch processing instead of streaming whenever latency tolerance allows, pick the cheapest model tier that meets your accuracy bar, apply VAD so you're not paying to transcribe silence, and evaluate the logging discount for audio without privacy constraints. For teams transcribing live meetings at scale, pairing a real-time platform's built-in transcription (like VideoSDK's) with batch post-call summaries can cut transcription spend significantly.
Future Trends and Roadmap
The trajectory through 2026 and beyond points in three directions. Gemini-class transcription models will continue expanding, bringing longer context windows, better multilingual code-switching, and unified transcription-plus-understanding in a single call. On-device recognition will keep improving as model compression techniques advance, shrinking the accuracy gap with cloud models while preserving offline, private operation. And multilingual switching will get more fluid, with recognizers handling mid-sentence language changes that currently trip up single-locale configurations. Watch the Google Cloud release notes for model deprecations, since older model tiers are retired on a published schedule and migrations are required periodically.
Definitions Glossary
Speech-to-Text (STT): The process of converting spoken audio into written text using machine learning models. Google offers it as cloud APIs and on-device recognizers.
Streaming Speech Recognition: A recognition mode where audio is sent continuously over a bidirectional connection and interim results are returned before the speaker finishes. Ideal for live captioning and voice assistants.
Speaker Diarization: The task of separating a multi-speaker audio recording into segments attributed to individual speakers. Available on Google's long-form and premium transcription tiers.
RNN-T (Recurrent Neural Network Transducer): A neural architecture that processes audio as a continuous stream and emits text incrementally, enabling low-latency streaming recognition.
Voice Activity Detection (VAD): A technique that detects when speech is present in audio, used to skip silence, reduce cost, and improve utterance boundary detection.
Service Account: A Google Cloud machine identity used for server-to-server authentication. Preferred over API keys for all backend integrations.
Key Takeaways
- Google speech recognition spans three layers: the mature Cloud Speech-to-Text API, the newer Gemini Transcribe model family, and free on-device recognizers, each with distinct latency, cost, and privacy trade-offs.
- Streaming recognition over gRPC delivers interim results for live UX; batch processing is cheaper and often more accurate for recorded audio.
- Authentication belongs server-side: use service accounts on your backend and never expose credentials in client apps, mirroring the token-based pattern used by platforms like VideoSDK.
- Accuracy is won before the API call: 16 kHz PCM audio, noise suppression, and voice activity detection do more for transcript quality than model tuning.
- Manage streaming session limits, language codes, and quotas proactively, since these three areas cause most production failures.
Conclusion
Google speech recognition remains one of the most capable and widely deployed speech-to-text stacks available in 2026, covering everything from instant on-device voice typing to cloud transcription with diarization and multilingual understanding. The winning approach is matching the service to your use case: streaming for live experiences, batch for archives, on-device for privacy. If you're building live transcription into a video or voice application, VideoSDK's real-time communication SDKs handle the media layer, including noise suppression and per-participant tracks, so your Google speech recognition integration gets clean audio from the start. Try the free tier on Google Cloud and VideoSDK's free credits, and join the VideoSDK Discord community to compare notes. What are you building with speech recognition? Drop a comment, I'd love to hear about your use case.
Free $20 Balance for AI Voice Agents & Video Calls
FAQ